
Key takeaways
• Pick the cloning tier that matches the use case. Zero-shot (3–10 s sample) for interactive agents, instant clones (30 s–2 min) for stable product voices, Professional Voice Cloning (30+ min) for audiobooks and broadcast.
• Sub-500 ms end-to-end is routine in October 2026. Cartesia Sonic 3.6 (under 90 ms), ElevenLabs Flash v2.5 (~75 ms) and Inworld TTS-2 (90 ms P90) all start speaking in under 100 ms; Eleven v4 Turbo (~150 ms) now tops the Artificial Analysis quality leaderboard. The bottleneck is usually your LLM, not the TTS.
• Consent and watermarking are architecture, not legal notes. EU AI Act Article 50 disclosure has applied since 2 August 2026, with machine-readable marking due by 2 December 2026 for systems already on the market; Tennessee’s ELVIS Act and Illinois BIPA add consent duties in the US. Retrofit cost is brutal.
• Cost spans ~5× across managed TTS. At October 2026 list prices Inworld TTS-2 Flash is $0.015 per 1k chars and TTS-2 $0.025, Cartesia $0.038–$0.065, ElevenLabs $0.04 (Flash, v4 Turbo) to $0.08 (v3, v4). Self-hosted Chatterbox (MIT) is cheapest at scale — but XTTS-v2 and F5-TTS weights are non-commercial, so read the licence first.
• Quality is a loop, not a launch. Speaker similarity (ECAPA-TDNN cosine ≥ 0.75 zero-shot, ≥ 0.85 PVC), MOS ≥ 4.0, pronunciation error rate < 2% — measured weekly on a held-out sample set — is how you keep a voice product honest.
Updated October 2026: Eleven v4, Cartesia Sonic 3.6 and Inworld TTS-2 latency and pricing, OpenAI gpt-realtime-2.1 and GPT-Live-1, Resemble AI’s exit from commercial TTS, Digital Omnibus marking dates and the 2026 NO FAKES Act vote.
Real-time voice cloning technology went from research demo to production feature in two years. In October 2026 you can send a few seconds of reference audio (3 s on Inworld, about 10 s on Cartesia) to a WebSocket endpoint and stream back natural synthesized speech at roughly 50–150 ms time-to-first-audio. That opens up a category of products — AI call-centre agents, real-time dubbing, accessibility voice restoration, multilingual meeting translation, personalised assistants — that were impossible at this price a year ago. It also creates real risks: the FBI’s IC3 logged 22,364 complaints mentioning AI and $893M in losses in 2025, the first year it tracked AI separately (report released April 2026), and Resemble AI’s 2025 Deepfake Threat Report counted $1.28B in documented deepfake losses across 1,567 verified incidents. This guide walks through how to ship it well: the decisions, the vendors, the compliance shape, the cost model and the pitfalls.
Target audience: CTOs, founders, product leads and engineering managers scoping a voice-cloning product — call-centre AI, accessibility tool, media dubbing, games NPCs, educational assistants. Everything below ties back to a real protocol, vendor, model or number; we deliberately keep cost estimates conservative.
Why Fora Soft wrote this playbook
Fora Soft has built real-time video, audio and AI products since 2005 — 250+ projects, with a heavy concentration in voice, streaming and conversational AI. We’ve built custom text-to-speech and voice-cloning pipelines using ElevenLabs, Cartesia, OpenAI Realtime, self-hosted open models (Chatterbox in production, XTTS-v2 for R&D) and NVIDIA Riva across telemedicine, remote education, interpretation and customer support. We ship AI integration and custom video and audio processing products where latency budgets are measured in tens of milliseconds and compliance shape changes the architecture.
This playbook compresses what we learned on those builds, plus 2025–2026 research on production voice cloning, into a single reference you can hand to your engineering team or to a partner. If you want a second opinion on vendor choice, architecture or cost modelling, book a call at the end — our Agent Engineering workflow turns a proof-of-concept around fast and cheap.
Scoping a real-time voice product?
Tell us the latency target, language mix and compliance region. In 30 minutes we’ll sketch the right vendor, a realistic cost-per-minute and a 4-week proof-of-concept plan.
What “real-time voice cloning” actually means in 2026
Voice cloning technology generates speech in a target speaker’s voice from arbitrary text, conditioned on a reference sample. “Real-time” narrows that to latency budgets that support live conversation: sub-500 ms end-to-end for an agent that talks back while a human is still finishing their sentence, sub-1s for live dubbing, sub-3s for batched voiceover. Distinguish it from plain TTS (fixed library voices, no personalisation) and voice conversion (audio-in → same content, different voice, not generative).
| Tier | Sample needed | Typical speaker similarity | Best fit |
|---|---|---|---|
| Zero-shot | 3–10 seconds | 0.70–0.82 | Agents, NPCs, ephemeral user-facing clones |
| Instant / few-shot | 30 s–2 min | 0.80–0.88 | Brand voices, podcasts, educational tutors |
| Professional Voice Cloning (PVC) | 30+ minutes | 0.90–0.96 | Audiobooks, broadcast dubbing, celebrity licensing |
| Fine-tuned custom model | 8–16 hours | 0.95+ | Legacy brand continuity, long-running IP voices |
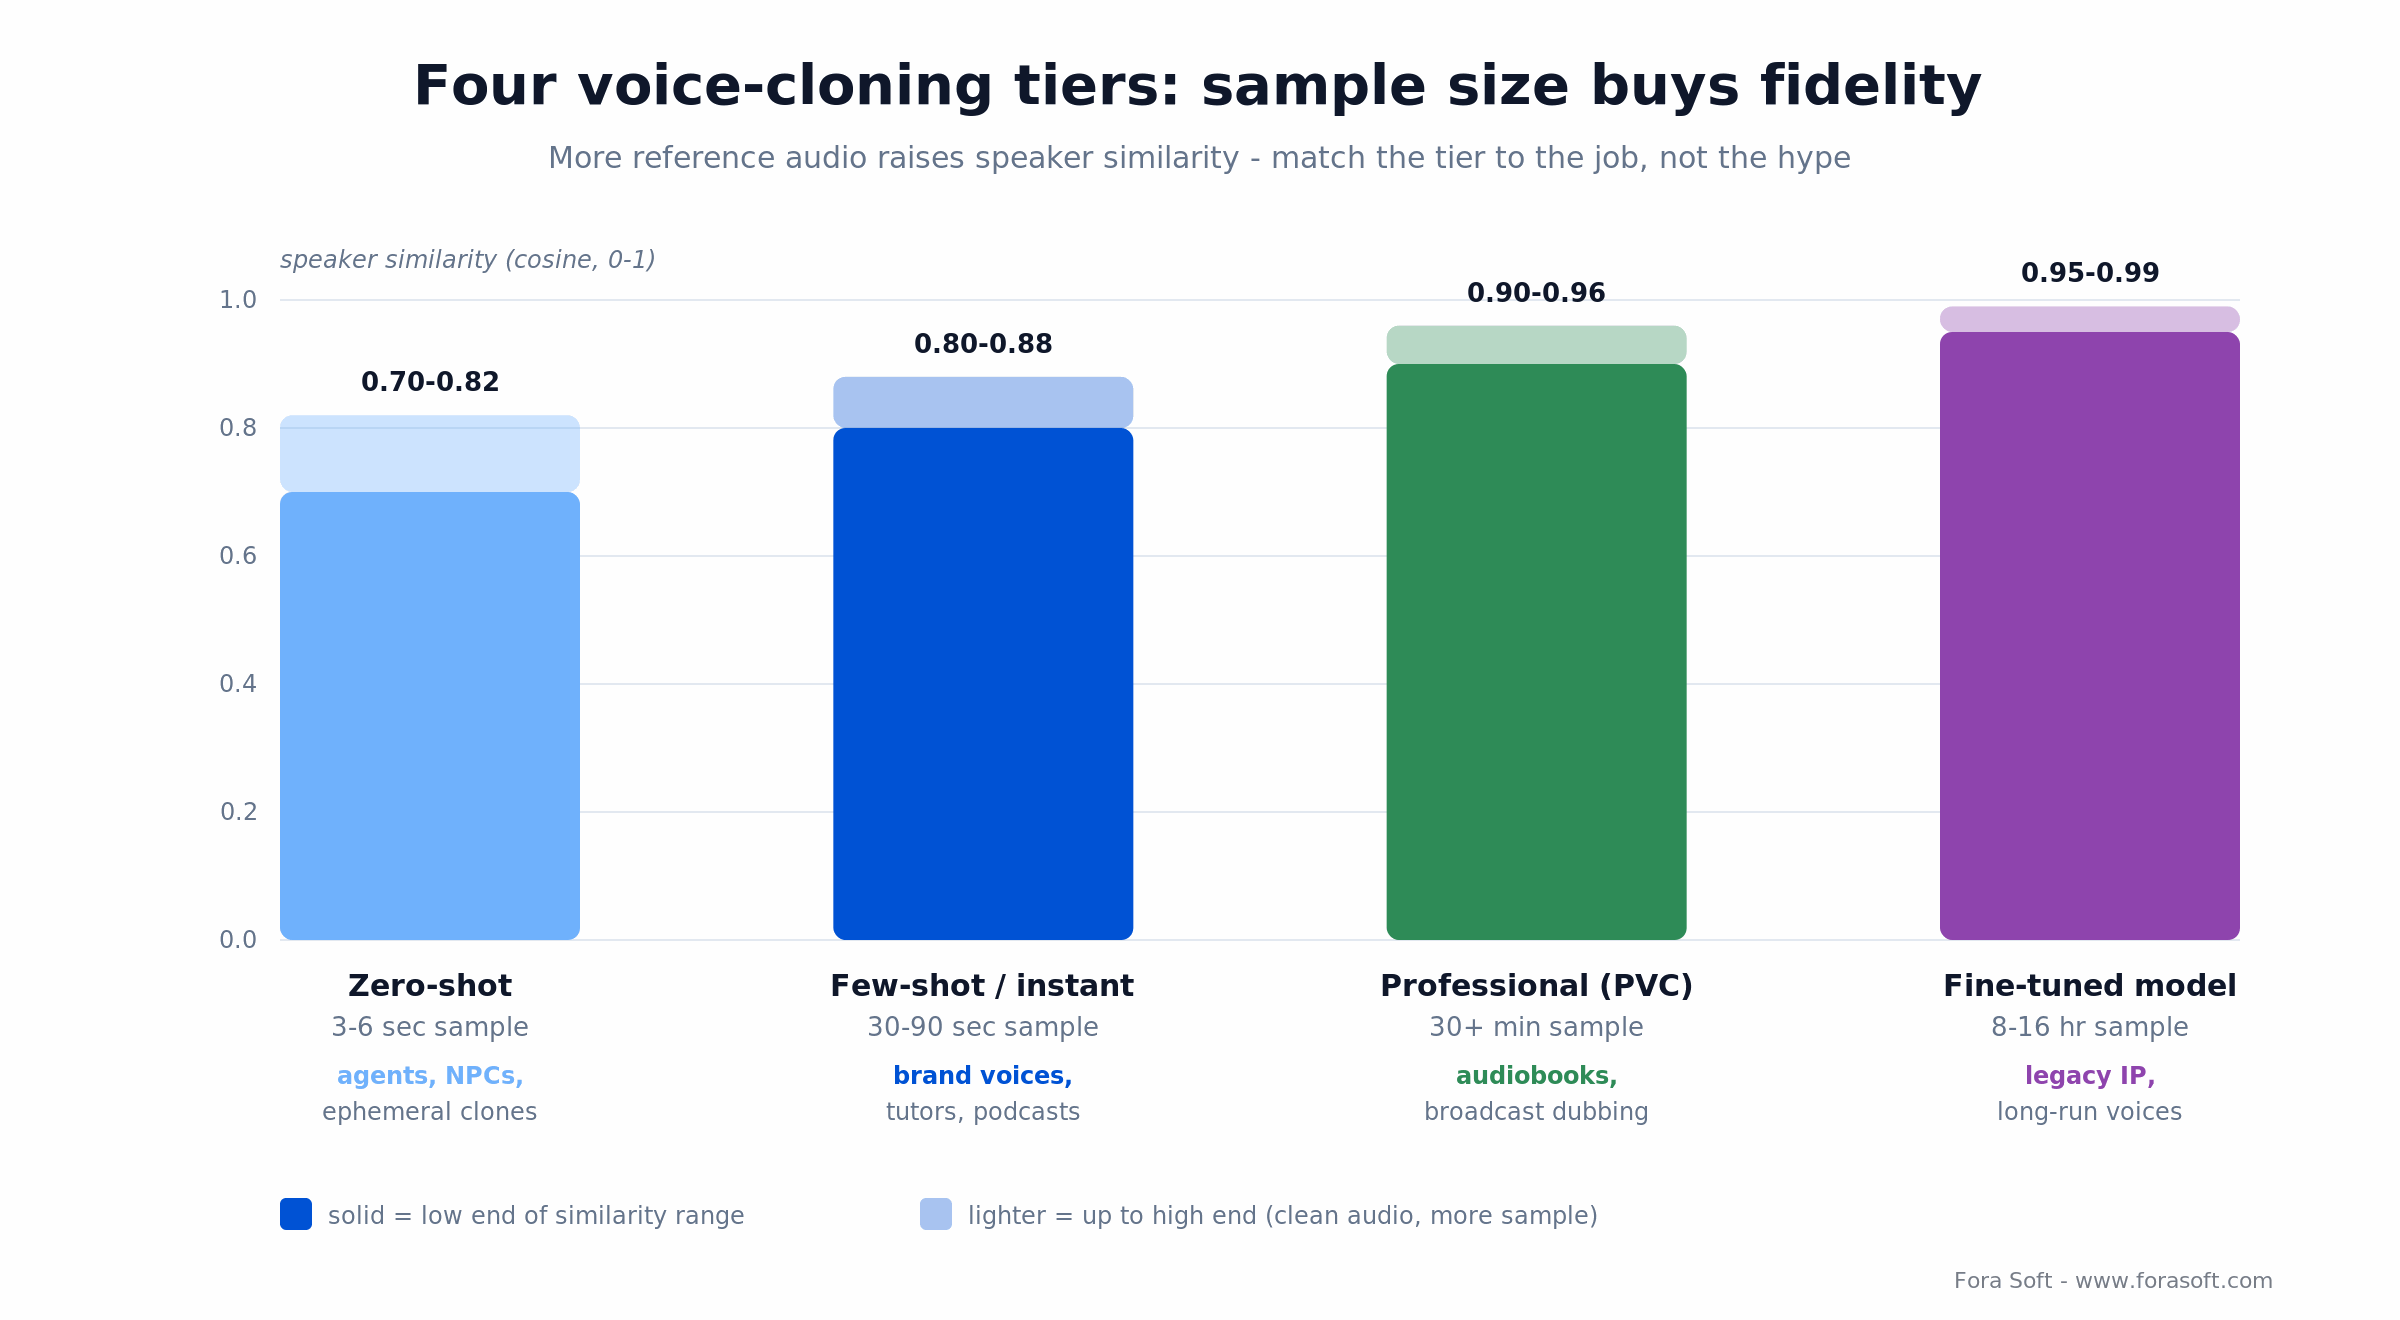
Figure 1. More reference audio buys higher speaker similarity - match the tier to the job.
Reach for zero-shot when: your product needs to onboard a new speaker per session (NPC per player, customer voice for personalised IVR). Quality is good enough for conversational UX but not for audiobook-grade content.
Reach for few-shot when: the voice is a product asset that needs consistent personality — brand agents, tutors, permanent game characters. Worth the extra minute of sample capture.
Reach for PVC when: the output is distributed: audiobooks, dubbed films, YouTube series. Zero-shot never sounds broadcast-clean; PVC does.
Where real-time voice cloning actually earns its place
Not every product needs a cloned voice. The use cases where the ROI is unambiguous in 2026 cluster into a few categories.
AI call-centre agents. Replacing or augmenting tier-1 support with a 24/7 multilingual agent speaking in a consistent, pleasant voice — ideally one cloned from your top-performing human agent. Per-minute cost at 2026 managed pricing is pennies; the savings vs per-call outsourcing are immediate at mid-size call volumes.
Real-time dubbing and multilingual translation. Live translation of meetings, webinars and sport commentary with the original speaker’s voice preserved in the target language. Broadcasters are adopting it step by step: CAMB.AI ran live AI subtitling for Eurovision Sport at the Milano Cortina 2026 Paralympic Winter Games (March 2026), and voice-preserving dubbing is the next layer. For the translation layer, pair voice cloning with the stacks we cover in real-time meeting translation and multilingual video-call translation.
Accessibility and voice banking. ALS, Parkinson’s and pre-operative patients record 30+ minutes while their voice is still healthy (or 30–90 seconds as an instant-clone fallback) that the system uses to restore their own voice on an AAC device or communication app. Deeply high-stakes; PVC-grade quality justified; consent/disclosure absolutely airtight.
Conversational avatars and assistants. Personal branding for influencers, custom voice for household assistants, multilingual customer support bots. Cartesia Sonic and Inworld TTS drive these at sub-200 ms latency.
Media localisation and voiceover automation. YouTube, TikTok, LinkedIn creator content, audiobook production, corporate training dubbing. Batched workflows are now fast enough that a creator can localise an hour of content in minutes.
Game NPCs with dynamic dialogue. Procedural dialogue trees voiced in real-time; previously prohibitive because of voice-actor costs. Now a few cents per NPC-hour.
Language-learning partners. A tutor voice that matches the learner’s dialect preferences, or a partner that corrects pronunciation interactively. Pair with ASR for closed-loop feedback.
AI call assistants and outbound sales. For the call-specific tech stack (VoIP bridging, latency budget, barge-in) see our AI call assistants API guide.
Vendor comparison: who leads on latency, quality and price
Pick the vendor by the three axes that actually matter to your product: time-to-first-audio, voice fidelity, and per-minute cost. Quality differences between the top tier are narrow; cost differences are huge.
| Vendor | Time-to-first-audio | Clone sample | Pricing (Oct 2026) | Best fit |
|---|---|---|---|---|
| ElevenLabs (Flash v2.5, v4 Turbo, v4) | Flash ~75 ms model latency; v4 Turbo ~150 ms to first speech | Under 2 min (instant) / ~30 min (PVC) | $0.04 per 1k chars (Flash, v4 Turbo); $0.08 (v3, v4) | Quality-first products, 90+ languages, broadcast |
| Cartesia Sonic 3.6 | Under 90 ms | 10 s instant (up to 60 s); 30+ min pro | $0.038–$0.065 per 1k chars over plan (Scale–Pro) | Latency-critical agents, cost-sensitive scale |
| Inworld TTS-2 / TTS-2 Flash | 90 ms P90 / ~50 ms | 3 s instant | $0.025 / $0.015 per 1k chars on-demand | Games, companions, high-volume agents |
| OpenAI gpt-realtime-2.1 / GPT-Live-1 | Speech-to-speech; no TTFA published | Cloned voices for eligible customers only, 10–30 s + consent recording | Audio $32 in / $64 out per 1M tokens; GPT-Live voice layer $0.05/min | All-in-one speech-to-speech agents |
| Microsoft Azure Personal Voice | Not published | 5–90 s + spoken consent (approved customers) | $0.024 per 1k chars | Azure ecosystem, enterprise compliance |
| Google Chirp 3 HD Instant Custom Voice | Not published | ~10 s + consent (allow-list) | $0.06 per 1k chars | GCP stacks, 30 locales |
| Respeecher | Real-time speech-to-speech in beta | 30+ minutes, broadcast-grade | Custom enterprise | Film, TV, high-end advertising |
| Chatterbox (MIT) / VoxCPM2 (Apache-2.0), self-host | Depends on your GPU | A few seconds | Self-host cost only | On-prem and privacy-bound products |

Figure 2. Vendor-published first-audio latency against list price per 1,000 characters, October 2026. Inworld holds the cheapest corner; ElevenLabs Flash and Cartesia Sonic 3.6 start speaking in under 100 ms for about $0.04.
Three shifts since summer 2026 change the shortlist. First, the top of the Artificial Analysis TTS leaderboard turned over: on 17 October 2026 Eleven v4 Turbo leads (Elo 1330), Cartesia Sonic 3.6 is fourth, and July’s leader, Speechify Simba 3.2, is ninth. Second, models now retire fast: Cartesia switches off Sonic Turbo on 20 October 2026, and OpenAI shuts down the original gpt-realtime on 20 January 2027 in favour of gpt-realtime-2.1, so pin model snapshots and budget a migration. Third, Resemble AI stopped selling voice AI to new customers on 13 August 2026 to focus on deepfake detection; its open Chatterbox (MIT) stays free to build on and was preferred over ElevenLabs in 63.75% of a Podonos blind test Resemble commissioned. For licensing, watermarking and the market numbers behind build vs license, see our voice cloning software guide with market data. For the broader TTS vendor set (including non-cloning voices), see our best synthetic voice libraries; for the upstream ASR and audio tooling, the 7 best AI tools for audio apps maps the full stack.
How mature is multilingual voice cloning for real-time customer service?
Mature enough to ship in the 20–30 biggest languages, not yet in the long tail. As of October 2026, Eleven v4 keeps one cloned voice across 90+ languages, Cartesia Sonic 3.6 covers 44 languages with instant clones that keep their accent when they switch language, and Google’s Instant Custom Voice supports 30 locales from about 10 seconds of reference audio. What still breaks in production is code-switching inside one sentence, names and numbers in the second language, and accent drift on low-resource languages — so test every language you sell, not just English.
| Model | Languages (Oct 2026) | One cloned voice across languages | Watch out for |
|---|---|---|---|
| ElevenLabs v4 / v4 Turbo | 90+ | Yes | PVC needs ~30 min of audio per voice |
| Cartesia Sonic 3.6 | 44 | Yes, instant clones keep the accent | Older Sonic Turbo retires 20 Oct 2026 |
| Google Chirp 3 HD Instant Custom Voice | 30 locales | Per locale | Allow-list access, consent required |
| Chatterbox Multilingual (MIT, self-host) | 23+ | Yes | You own GPU scaling and QA |
| Fish Audio Drama 3 (open weights) | 83 | Yes | Community licence: free commercial use only under $500k revenue |
For customer service the honest maturity test is containment, not demo quality: run a two-week pilot per language, have native speakers score 50 real calls, and track re-transcription WER on the agent’s own output (see the quality metrics below). If you are building the phone side, our AI call agent development team ships multilingual inbound and outbound agents with SIP, CRM lookups and warm transfer to a human.
Reference architecture for a real-time voice-cloning product
A real-time voice-cloning product stitches four subsystems: capture, clone registry, synthesis pipeline, and delivery. A fifth — compliance — gates everything.
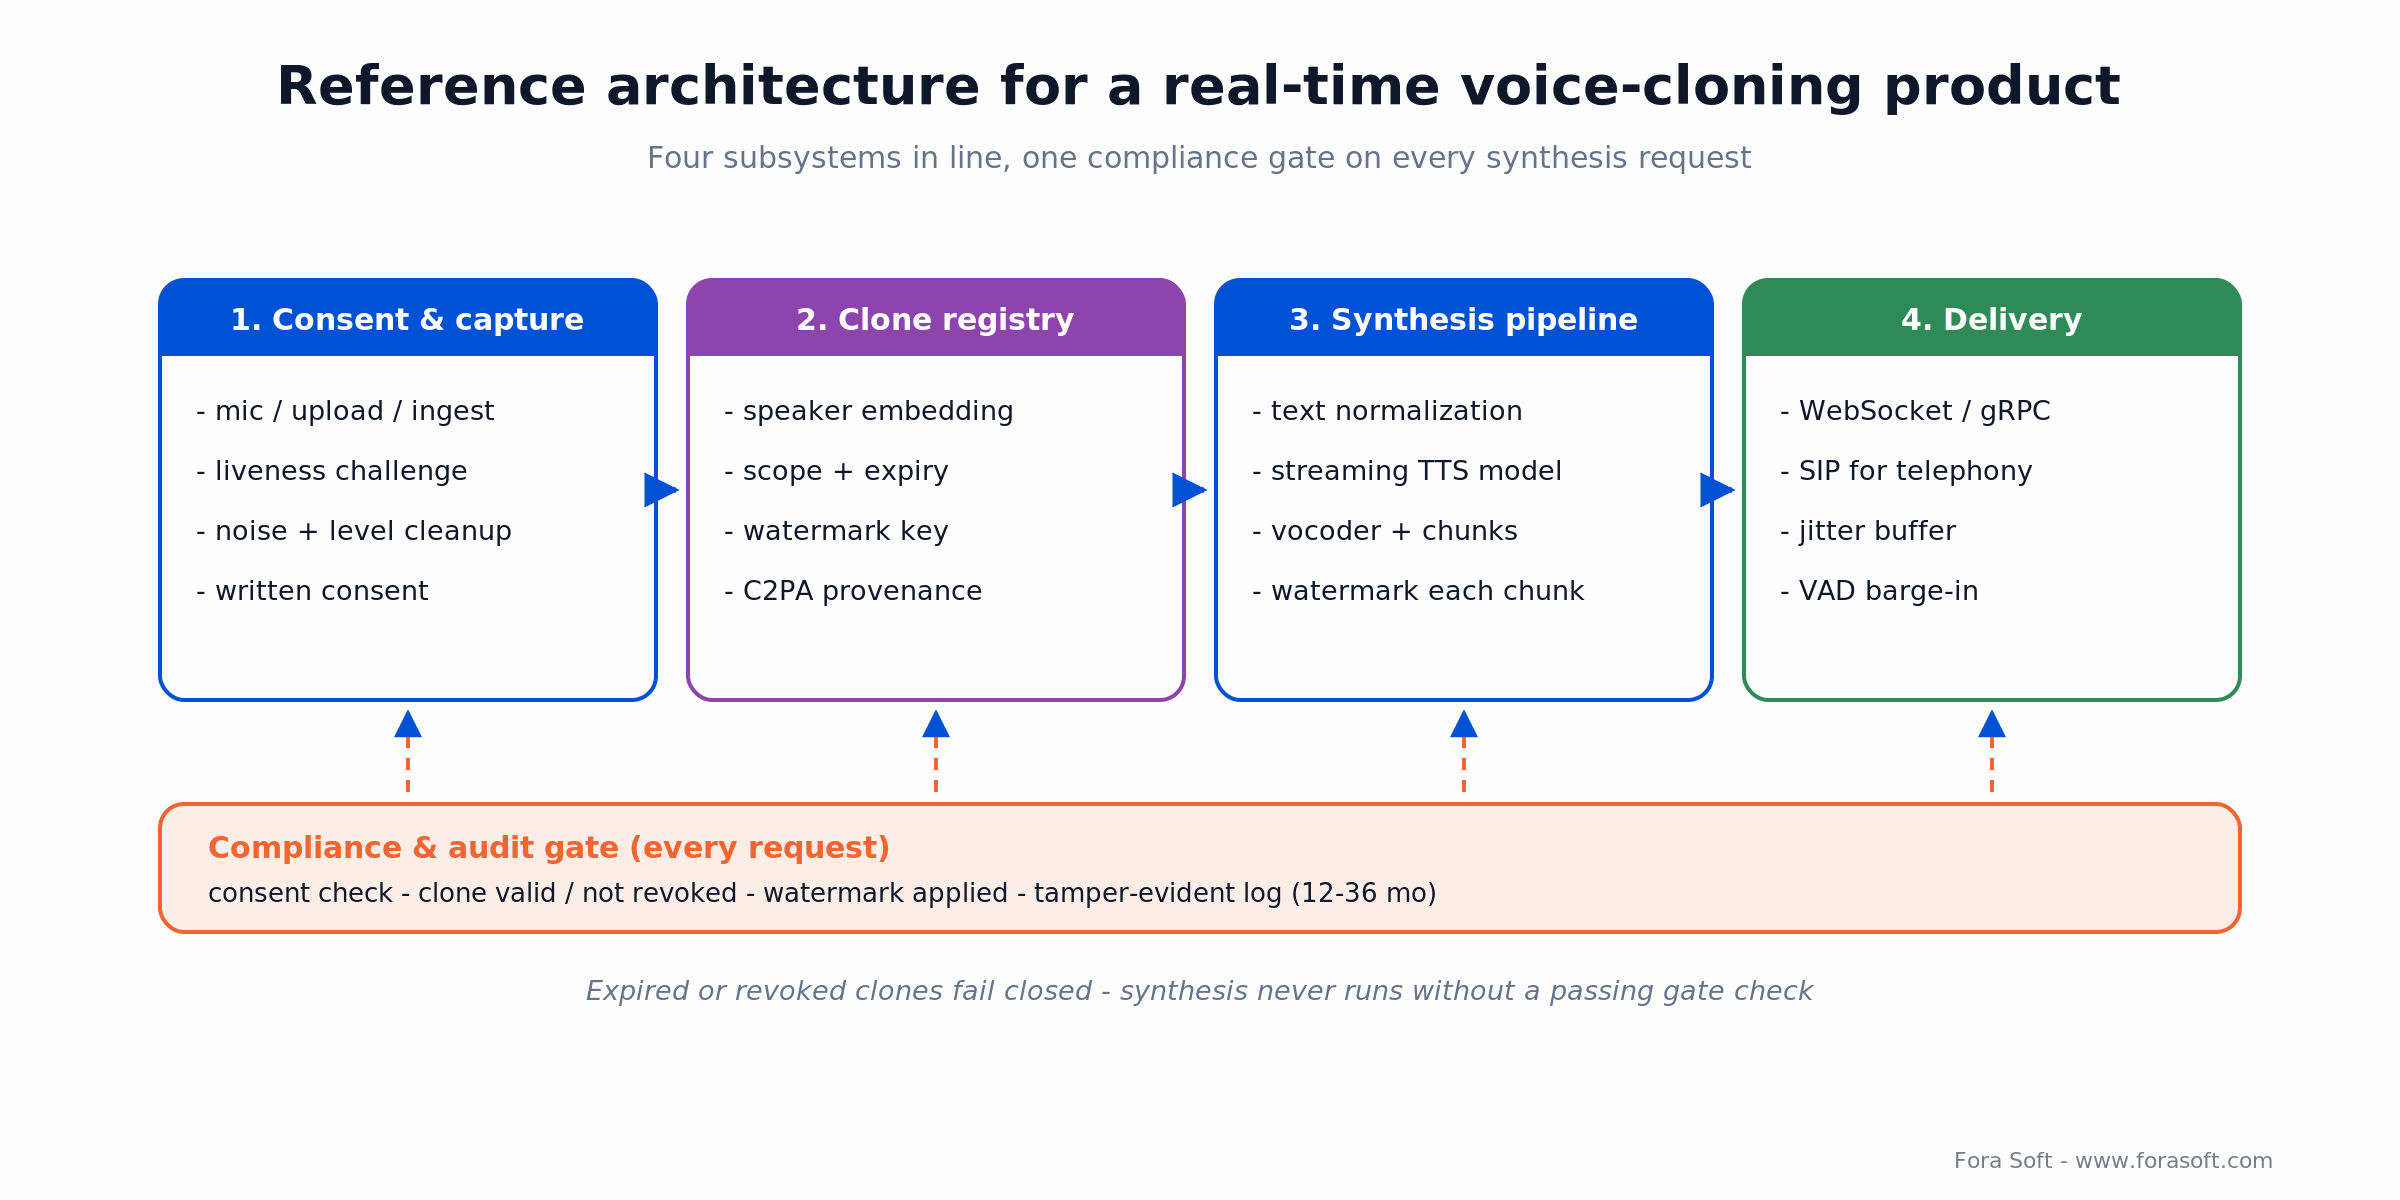
Figure 3. Four subsystems in line; a compliance gate checks consent, revocation and watermark on every request.
Capture and consent
Reference samples arrive via mic capture, uploaded audio, or content ingest (film, podcast, video). Every sample gets: explicit written consent, a liveness check where the speaker reads a dynamic phrase, PII scrubbing on metadata, and quality pre-processing — noise suppression, level normalisation, sample-rate unification to 24 kHz / 48 kHz, clipping detection, speaker-diarisation if multi-voice.
Clone registry
The registry stores: speaker embedding, permission scope (internal / external / distribution), expiry date, watermark key, provenance metadata (C2PA-compatible). Every inference request carries a clone ID and is gated against the registry — expired or revoked clones fail closed.
Synthesis pipeline
Text normalisation (numbers, dates, acronyms, URLs) → phonemiser / SSML pass → streaming acoustic model or decoder (autoregressive or flow-matching) → vocoder or codec decoder (HiFi-GAN, BigVGAN, Vocos) → opus-encoded chunks. Every chunk goes through an audio watermarker (AudioSeal, Perth, ElevenLabs AI Authenticity) before it leaves the server.
Delivery and barge-in
WebRTC (for example LiveKit) for browser-to-server, WebSocket for server-to-vendor, gRPC for enterprise or telephony, SIP bridging for call-centre. On the client, an adaptive jitter buffer (typically under 150 ms) absorbs network variance. A server-side VAD detects user turn-taking and cancels in-flight TTS / LLM generation when the user speaks — barge-in is non-optional for real conversation.
Compliance layer
Every inference logs: caller, clone ID, text, timestamp, watermark, provenance. Audit log is tamper-evident (S3 Object Lock or equivalent), retained for 12–36 months depending on jurisdiction.
Model families actually powering production voice cloning
Autoregressive transformer (Chatterbox, XTTS-v2, CosyVoice-style). Token-by-token generation, low latency (150–200 ms), naturally streamable. The default architecture for real-time agents (remember XTTS-v2 weights are non-commercial). Cheaper to serve, simpler to debug, minor repetition issues on very long outputs.
Diffusion + flow matching (NaturalSpeech 3, Voicebox, F5-TTS, E2-TTS). Highest quality and best emotional range; slower by default (200–500 ms) but catching up with accelerated sampling. The pick when broadcast-grade quality matters.
Neural codec language models (VALL-E X, OuteTTS). Predict discrete audio tokens with a GPT-style model; strong zero-shot from ~3–10 seconds, excellent multilingual transfer. Slight artefacts from token quantisation.
Two-stage acoustic model + vocoder (FastSpeech or Tacotron + HiFi-GAN / BigVGAN / Vocos). The classic modular pipeline: well-understood, reliable and streamable chunk by chunk, but with less expressive range than the newer families.
GPU sizing. A single A10 handles ~3–5 concurrent zero-shot clones at sub-300 ms latency; an A100 pushes that to 10–15; an H100 to 25+. XTTS-v2 or Chatterbox on a consumer RTX 4090 runs 5–10 concurrent streams for homelab experiments. Call-centre deployments of 1,000+ concurrent agents need managed APIs or a dedicated GPU fleet.
The open-source licence trap. Coqui — the company behind XTTS — shut down in early 2024, and XTTS-v2 weights remain under the Coqui Public Model License, which is non-commercial. F5-TTS code is MIT, but its pretrained weights are CC-BY-NC. Piper moved in October 2025 to the Open Home Foundation’s piper1-gpl repository under GPL-3.0, and Fish Audio’s open-weight Drama 3 (October 2026) allows free commercial use only below $500k annual revenue. For a paid product the safe open picks with cloning are Chatterbox (MIT; Turbo, Nano and Multilingual variants) and OpenBMB’s VoxCPM2 (Apache-2.0); Kokoro (Apache-2.0) is a strong fixed-voice TTS but does not clone. Read the licence before you ship, not after legal asks.
Reach for self-host when: you’re privacy-bound (healthcare, defence, legal) or running past a few thousand sustained concurrent streams, and you have the ML ops to own scaling and uptime. Use an MIT or Apache model (Chatterbox, VoxCPM2), never a non-commercial one.
Need to pick between Cartesia, ElevenLabs and self-host?
Share your expected concurrency, language mix and residency rules. We’ll give you a vendor recommendation and cost model in 30 minutes — grounded in production experience, not spec sheets.
Latency engineering: how to get under 500 ms end-to-end
In a voice agent the perceived latency is the full round-trip: user finishes speaking → ASR transcribes → LLM responds → TTS speaks. The TTS is rarely the bottleneck in 2026. The stack needs to overlap stages aggressively.
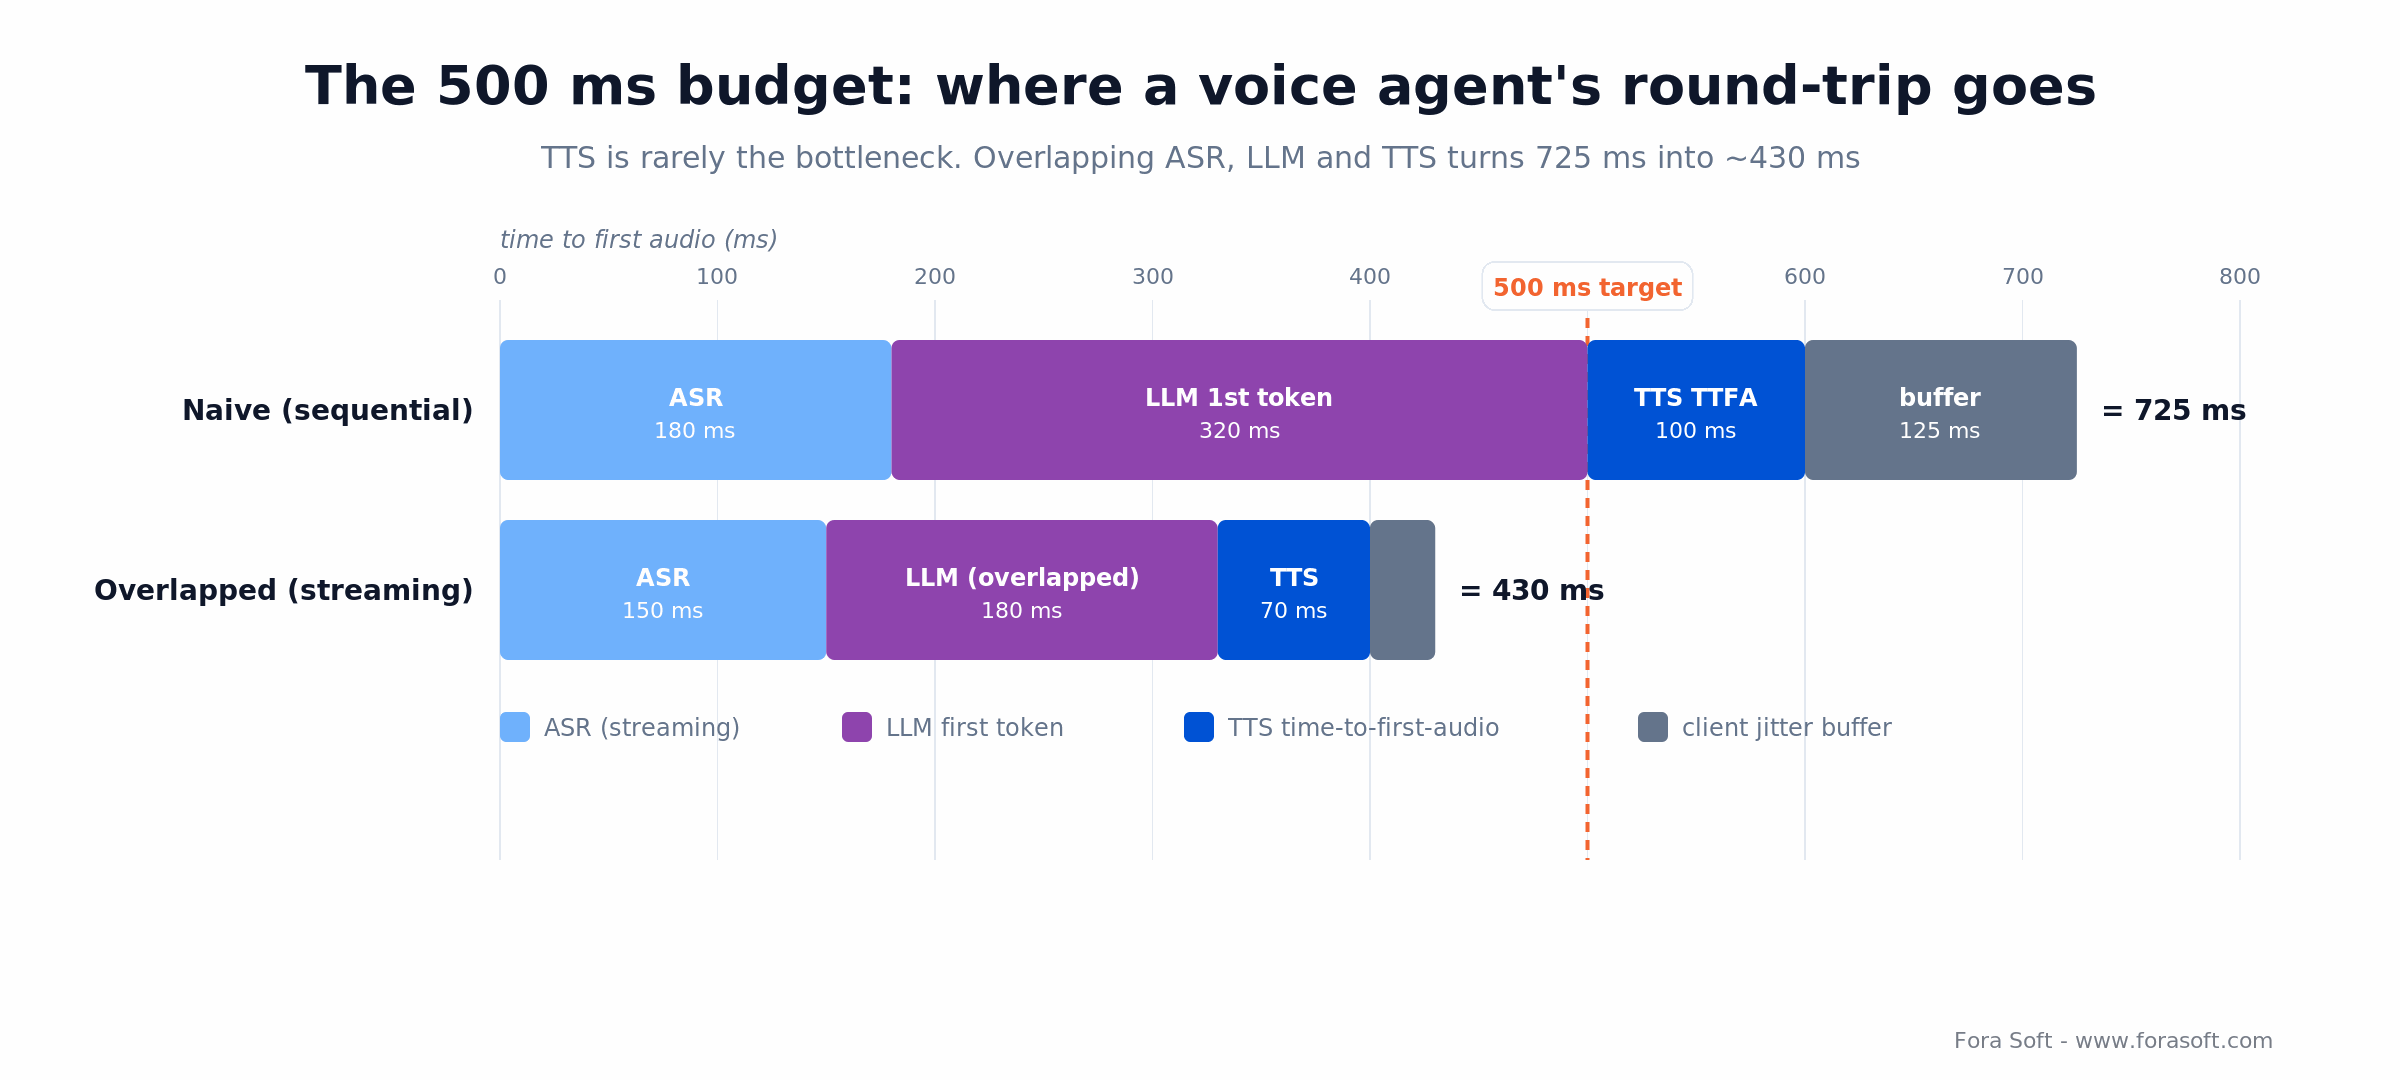
Figure 4. Overlapping ASR, LLM and TTS turns a 725 ms sequential round-trip into ~430 ms, before end-of-turn detection, which adds its own silence threshold unless you use a semantic turn detector.
1. Streaming ASR. Deepgram, Whisper-streaming, NVIDIA Riva ASR return partial transcripts under 200 ms. Feed those into the LLM as they arrive.
2. Streaming LLM. A small fast model (Claude Haiku 4.5 class, or a quantised 8B open model) streams first tokens in roughly 150–400 ms. Avoid any model that doesn’t support streaming; it kills the budget. The alternative is to skip the cascade: speech-to-speech models such as OpenAI gpt-realtime-2.1 and the full-duplex GPT-Live-1 (September 2026) listen and speak in one model, but cloned custom voices on OpenAI are limited to eligible customers.
3. Streaming TTS. As soon as the LLM emits a sentence-length chunk, push it into the TTS. Cartesia and ElevenLabs emit first audio in under 200 ms. Chunking at punctuation boundaries avoids mid-phoneme glitches.
4. Client buffer and VAD. An adaptive client-side jitter buffer (typically under 150 ms) absorbs network variance. Silero VAD detects user turn-taking in under 50 ms so the agent can stop speaking the instant the user resumes.
5. Regional endpoints. Anycast or regional deployment cuts 50–100 ms vs a single US endpoint. For global products, split APAC and EU into their own clusters.
For the ASR side of the pipeline, particularly in noisy environments, see our speech recognition in noisy environments guide and the speech-to-text live streaming tooling roundup. If you would rather not wire turn-taking yourself, our LiveKit AI agent development team builds this exact cascade — streaming ASR, LLM and cloned-voice TTS with barge-in — on LiveKit Agents. The deeper engineering discipline behind these budgets is in our AI for video engineering course.
Integration patterns: REST, WebSocket, gRPC, SIP
REST (batch). Post text, get an MP3 URL. Fine for voiceover, video dubbing, audiobook generation — anything where 5–15 seconds of wall time is acceptable. Simple to cache at a CDN.
WebSocket (real-time). Browser-native, firewall-friendly, sub-second time-to-first-audio. The default for web agents and conversational apps.
gRPC bidirectional streaming. Enterprise agents and telephony bridges. Lower overhead than WebSocket, strong typing, first-class in NVIDIA Riva and enterprise vendors.
SIP / MRCP bridging. For plugging into Asterisk, FreeSWITCH, Twilio Voice and other telephony stacks. Few TTS vendors offer a direct SIP adapter, so most deployments go through Twilio, LiveKit SIP or a media gateway on your side.
SSML and style tokens. Prosody, emotion, pitch, speed. ElevenLabs v3 and Cartesia accept per-chunk emotion tokens. Azure and Google support SSML. Keep the prompting pattern consistent across vendors so swap-in is cheap.
Compliance, consent and deepfake risk
Voice cloning is one of the fastest-moving regulated AI domains. In the EU, the AI Act’s Article 50 transparency duties have applied since 2 August 2026: providers must tell people when they are talking to an AI and mark synthetic output in a machine-readable way, and deployers must disclose deep-fake audio, cloned voices included. The Digital Omnibus (Regulation (EU) 2026/1744, in force since 27 July 2026) gives a marking grace period until 2 December 2026 only to generative systems placed on the market before 2 August 2026, and the Commission’s final Code of Practice on marking and labelling (10 June 2026) is the practical playbook. Fines reach €15M or 3% of worldwide turnover. In the US, Illinois BIPA treats voiceprints as biometrics, Tennessee’s ELVIS Act (effective 1 July 2024) bars unauthorised digital replicas, California’s AB 2602 and AB 1836 (effective 1 January 2025) cover replica contracts and deceased performers, New York has required disclosure of synthetic performers in ads since 9 June 2026, and the FCC ruled in February 2024 that AI-generated voices in robocalls are “artificial” under the TCPA. The federal NO FAKES Act (2026 version, S.4591) cleared the Senate Judiciary Committee on 18 June 2026, but a unanimous-consent vote was blocked on 30 September 2026, so it is still not law. Non-compliance is business-ending commercially, and potentially criminal personally.
1. Written consent, not verbal. Every cloned voice needs a documented permission from the speaker — scope (internal / external / commercial distribution), expiry date, revocation procedure. Keep the consent artefact alongside the clone.
2. Voice liveness check. A dynamic challenge phrase at sample capture proves the speaker is the one in front of the mic, not a recording. Prevents consent-by-stolen-audio.
3. Watermarking and provenance. Imperceptible audio watermarks (AudioSeal, Perth, ElevenLabs AI Authenticity) plus C2PA Content Credentials on the audio file and the metadata. Detectability matters both for compliance and for recovering trust if a clip goes viral.
4. Disclosure on user-facing outputs. Since 2 August 2026, Article 50 requires a “this audio was generated with AI” disclosure in most consumer deployments. Machine-readable marking is due now for new systems and by 2 December 2026 for generative systems already on the market before August. Plan UX accordingly — subtle, but present.
5. Revocation. The speaker can turn the clone off. That requires a live registry check on every inference, not a one-time key.
6. US state and sector rules. Illinois BIPA treats voiceprints as biometrics ($1,000 per negligent and $5,000 per intentional violation; since the August 2024 amendment, damages accrue once per person rather than per scan). Tennessee’s ELVIS Act protects voice and likeness as a digital-replica right. California’s AB 2602 and AB 1836 cover digital-replica contracts and deceased personalities. Game studios also need the performer’s informed consent and disclosure for digital replicas under SAG-AFTRA’s 2025 Interactive Media Agreement (ratified July 2025). Outside the US and EU, Denmark introduced a bill on 8 October 2026 giving people rights over their own voice and likeness, proposed to start on 1 January 2027. Watch the federal NO FAKES Act — if it passes, it preempts much of the state patchwork.
Cost model: what real-time voice cloning actually costs
Start per minute, then scale. Speech runs ~150 words per minute, or ~850 characters, so the TTS cost of one talk-minute is price-per-1k-chars × 0.85. At October 2026 list prices: Inworld TTS-2 $0.025 × 0.85 = $0.021/min; Cartesia (Scale overage) $0.038 × 0.85 = $0.032/min; ElevenLabs Flash or v4 Turbo $0.04 × 0.85 = $0.034/min; ElevenLabs v3 or v4 = $0.068/min. Add streaming ASR (Deepgram Nova-3 lists $0.0077/min, $0.0048 on its current promo) and a small streaming LLM (roughly $0.02/min) and a managed cascade lands near $0.05–$0.10 per conversation-minute. Speech-to-speech models bill differently: OpenAI’s GPT-Live-1 charges $0.05/min for the voice layer plus the LLM behind it, and gpt-realtime-2.1 bills audio at $32 in and $64 out per 1M tokens. They are the simplest to wire, but model them on your real call lengths, because longer calls re-send more history each turn.
Scenario. Take 500,000 TTS talk-minutes a month — a mid-size deployment — roughly 135 agents over business hours at a 35% talk ratio. At ~850 chars/min that is 425M characters. The monthly TTS bill, on list pricing before volume discounts:
| Option | Per 1k chars | Monthly TTS (500k min) | Trade-off |
|---|---|---|---|
| Self-hosted Chatterbox (MIT) | GPU-amortised | ~$8,000 GPU only (estimate) | Excludes ML-ops staff; with staffing, managed APIs usually stay cheaper until a few thousand sustained streams |
| Inworld TTS-2 | $0.025 | ~$10,625 | Low managed list price (TTS-2 Flash is $0.015; Azure Personal Voice lists $0.024); check voices and languages |
| Cartesia Sonic 3.6 (Scale) | $0.038 | ~$16,150 | Sub-90 ms latency at a low managed price |
| ElevenLabs Flash v2.5 / v4 Turbo | $0.04 | ~$17,000 | Fast, broad voices, top quality score (v4 Turbo) |
| ElevenLabs v3 / v4 | $0.08 | ~$34,000 | Most expressive for broadcast; twice the fast tier |
| OpenAI GPT-Live-1 (voice layer) | $0.05/min | ~$25,000 + LLM | One full-duplex model; compare per conversation |

Figure 5. Monthly TTS for 500k talk-minutes on October 2026 list pricing. Expressive v3/v4-class voices cost twice the fast tier.
The gap that matters is against people, not other APIs: even the most expensive line here is a fraction of the loaded cost of staffing 500k talk-minutes with human agents. Two honest caveats: at true call-centre scale you negotiate below list, and self-host cost is mostly fixed GPU spend, so it flattens as volume climbs and flips ahead of managed APIs past a few thousand sustained concurrent streams. We keep these numbers conservative and re-price with live metrics after a 30-day pilot — using our Agent Engineering workflow to get that pilot in front of real users fast.
Quality metrics worth measuring every week
Speaker similarity. Cosine similarity of speaker embeddings (ECAPA-TDNN or x-vectors). Target ≥ 0.85 for PVC, ≥ 0.75 for zero-shot. Falls when training data drifts or the clone misaligns to the speaker’s accent.
Mean Opinion Score (MOS). 1–5 human rating of naturalness. Target ≥ 4.0 for broadcast. Collect 20+ listeners per snapshot sample.
Word Error Rate (WER) on re-transcription. Run the synthesized audio back through ASR and compare to the input text. Target < 3% for broadcast, < 5% for agents. Catches pronunciation regressions fast.
Pronunciation error rate. Phoneme-level comparison. Target < 2% for multilingual deployments.
Time-to-first-audio (TTFA) p50/p95. p50 under 200 ms, p95 under 500 ms. Spikes usually indicate GPU contention or cold-starts on managed endpoints.
Emotion preservation. Human rating or an emotion-classifier comparison. Only matters in dubbing and narrative use cases; ignore for flat call-centre agents.
Mini case: a bilingual voice agent for an education platform
Situation. A pattern we see across our e-learning and interpretation clients: a tutoring or support agent that speaks in one consistent “house” voice across English and Spanish, answers in under 500 ms, and passes a human review before any new voice reaches students. We have shipped the streaming-speech and real-time-audio pieces of this on projects like TransLinguist (interpretation across 75+ languages) and BrainCert.
What we built. Consent capture with liveness check, Professional Voice Cloning for the two house voices, Cartesia Sonic for streaming synthesis at <150 ms TTFA, Whisper-streaming ASR with custom vocabulary tuned to course jargon, a small Claude Haiku agent orchestrating dialogue with a RAG lookup over course materials. AudioSeal watermarking on every output. Faculty review UI to approve or revoke voices. Retention log with 24-month immutability for audit.
Outcome. End-to-end latency holds under 450 ms with Cartesia streaming, and the review gate means no voice reaches a student until a human approves it — the single control that makes voice cloning defensible in education. The bilingual house voice removes the friction of introducing a new synthetic identity per language. Want this shape of build? Book 30 minutes and we’ll walk the architecture.
A 12-week plan to ship your first voice-cloning product
Weeks 1–2 — Outcome, compliance shape, vendor shortlist. Lock the latency target, language mix, regulatory region and one primary KPI. Draft the consent flow and revocation mechanism. Shortlist two vendors.
Weeks 3–4 — Capture pipeline. Ship the sample-collection UI with liveness check, PII scrubbing, audio pre-processing and explicit consent artefacts. Standardise on 24 kHz (or 48 kHz) mono WAV with noise gate at −50 dB.
Weeks 5–7 — Voice registry and synthesis. Stand up the clone registry (expiry, scope, revocation), wire the streaming TTS API, chain ASR → LLM → TTS with overlap, validate TTFA under 300 ms on a dev corpus.
Weeks 8–9 — Watermarking and review UI. Add AudioSeal or equivalent; ship a reviewer dashboard where an admin approves/rejects new voices before they go live.
Weeks 10–11 — Barge-in and QA. Add VAD-driven interruption, soak-test for echo / barge-in regressions, measure speaker similarity and WER on a held-out set, fix regressions.
Week 12 — Pilot and rollout plan. Invite 5% of users; measure TTFA p50/p95, WER, MOS, revocation requests, legal incidents. Expand once signals are green.
Five pitfalls that sink voice-cloning rollouts
1. Poor reference audio. Noise, inconsistent sample rates, reverberation, uneven level — all drop speaker similarity from 0.88 to 0.65 overnight. Fix capture before you fix the model.
2. Shipping zero-shot for broadcast. A 3-second reference is enough for a call-centre agent but never enough for audiobook production. Use PVC where quality matters — and accept the 30-minute capture cost.
3. No barge-in. Users talk over the agent and get ignored. Voice products without interruption handling feel broken within seconds.
4. Missing consent or watermark. Regulatory and brand risk. One incident of an unauthorised clone being used for fraud and the product gets pulled. Consent plus watermark must be week-1 architecture.
5. GPU under-provisioning. Dev runs on one A10; production surge spikes to 1,000 concurrent agents; TTFA balloons, churn starts. Autoscale the GPU pool or price the managed API against realistic peak.
When you should not use a cloned voice
There are products that don’t need a clone: a generic TTS voice is fine, and simpler to compliance-prove. Don’t clone a voice when your users would be happy with ElevenLabs’ “Rachel” or Google’s Studio voices; don’t clone when you can’t obtain proper consent; don’t clone when the use case could be mistaken for impersonation (elections, legal communications, financial authorisation). Reach for cloning only when voice identity is a product feature — brand, accessibility, entertainment, localisation — and you control the consent loop.
A decision framework — pick your stack in five questions
Q1. Latency budget end-to-end? < 300 ms → Cartesia Sonic 3.6, ElevenLabs Flash v2.5 / v4 Turbo or Inworld TTS-2. < 500 ms → OpenAI gpt-realtime-2.1 / GPT-Live-1, Azure Personal Voice. < 3 s → batch REST on any major vendor.
Q2. Quality tier? Broadcast → ElevenLabs PVC or Respeecher. Product voices → ElevenLabs few-shot or Cartesia PVC. Ephemeral user clones → any zero-shot.
Q3. Regulatory region? EU → Article 50 disclosure, AudioSeal watermark, regional endpoints. US → BIPA / ELVIS / California coverage. APAC → local residency contracts; review each country.
Q4. Scale target in year 2? < 500 concurrent → managed API. 500–3,000 → managed API with volume commit. 3,000+ → evaluate self-hosted Chatterbox, VoxCPM2 or NVIDIA Riva as the cost line flips.
Q5. Who operates the system? No dedicated ML ops → managed vendor end-to-end. Small ML team → managed TTS with in-house orchestration. Full ML platform team → DIY with open-source models.
Ready to ship a real-time voice product?
We’ve shipped custom voice pipelines across telemedicine, education, interpretation and customer support. Share your target use case and we’ll scope a 12-week build with conservative cost modelling.
KPIs: the four numbers that tell you the voice product is healthy
1. Time-to-first-audio p95. Target < 500 ms. The single metric that determines whether conversations feel natural.
2. Speaker similarity rolling average. Target ≥ 0.85 for PVC voices, ≥ 0.75 for zero-shot. Falls when fine-tuning drifts, reference audio degrades or you switch vendors.
3. Task completion rate (agent products). Target ≥ 75% on defined intents. The business outcome that justifies the whole stack.
4. Consent incidents per 1k clones. Target zero. Revocation requests, legal complaints, provenance gaps — any of these spiking is a stop-the-line event.
FAQ
How much sample audio do I actually need?
3–10 seconds for zero-shot agent-quality clones (Inworld accepts 3 s, Cartesia recommends 10 s, OpenAI custom voices use 10–30 s). 30 seconds to 2 minutes for stable brand or tutor voices. About 30 minutes of clean audio for Professional Voice Cloning. Sample quality matters more than raw length.
Is real-time voice cloning legal?
Yes, with documented consent, disclosure and provenance; it is illegal for impersonation, unauthorised likeness use, election interference and fraud. In the EU, Article 50 disclosure has applied since 2 August 2026; in the US, Illinois BIPA, Tennessee’s ELVIS Act and California’s AB 2602 and AB 1836 set the boundaries. Always build the consent flow first.
Which vendor has the best latency today?
Among vendor-published figures in October 2026, Inworld TTS-2 Flash (~50 ms) and ElevenLabs Flash v2.5 (~75 ms model latency) are fastest, with Cartesia Sonic 3.6 under 90 ms and Inworld TTS-2 at 90 ms P90. Eleven v4 Turbo trades a little speed (~150 ms median time to first speech) for the top quality score on Artificial Analysis. Cartesia retires Sonic Turbo on 20 October 2026, so don’t start new work on it.
Can I self-host voice cloning?
Yes. Chatterbox (MIT) and VoxCPM2 (Apache-2.0) clone voices and are safe for commercial use; XTTS-v2 and F5-TTS weights are non-commercial, and Piper is now GPL-3.0. Small scale runs on a consumer RTX 4090; production needs an L40S or A100-class fleet. Self-host wins on privacy (healthcare, defence, legal) and flips cheaper than managed APIs at sustained high concurrency.
What’s the minimum viable consent workflow?
Written consent document, dynamic challenge phrase during sample capture, expiry date on every clone, revocation button in the user’s dashboard, watermark on every output, tamper-evident log for 24+ months. Miss any of those and you’re one incident away from a crisis.
How do I handle multiple languages?
Pick a multilingual model that keeps one voice across languages — Eleven v4 (90+ languages), Cartesia Sonic 3.6 (44) or Chatterbox Multilingual (23+, self-host) — and clone from one reference sample. For the highest fidelity per language, record per-language samples of the same speaker. Validate on accent variants and code-switching, not just the dominant dialect.
How do I detect if a clip is a deepfake clone?
Use three layers: watermark detection (AudioSeal, Perth, ElevenLabs AI Authenticity), a provenance check (C2PA Content Credentials) and a deepfake classifier (Resemble Detect, Pindrop, AI or Not). No single layer is perfect, so combine them and route low-confidence calls to a human. Resemble AI now works only on detection after leaving commercial voice AI in August 2026.
Which voice cloning stack is best suited for real-time conversations?
For most live agents in October 2026: streaming ASR (Deepgram Nova-3 or Whisper-streaming), a small streaming LLM and a sub-100 ms cloning TTS such as Cartesia Sonic 3.6, ElevenLabs Flash v2.5 or Inworld TTS-2, on a WebRTC transport like LiveKit with barge-in. Choose a speech-to-speech model (OpenAI gpt-realtime-2.1 or GPT-Live-1) when one integration matters more than voice choice and per-minute cost.
Which voice cloning platforms offer API access and union-compliant consent for game studios?
ElevenLabs, Cartesia and Inworld all expose voice cloning through public APIs, but no API makes you union-compliant on its own. SAG-AFTRA’s 2025 Interactive Media Agreement (ratified July 2025) requires the performer’s informed consent and disclosure for digital replicas, so keep consent scope, expiry and revocation per performer in your own clone registry.
Is the GitHub Real-Time-Voice-Cloning repo still worth using?
Only for learning. CorentinJ’s 2019 SV2TTS repository (60k+ stars) says in its own README that it has aged and points to newer models such as Chatterbox. For a product, use a maintained open model or a managed API.
Can Fora Soft build a voice-cloning product for us?
Yes. We build voice pipelines end-to-end: capture, consent, clone registry, streaming synthesis, barge-in, watermarking, audit trails, compliance reviews. Typical scope is 8–12 weeks for a production pilot, 12–20 weeks for a full commercial deployment. Book a call to scope yours.
What to Read Next
TTS vendors
6 Best Synthetic Voice Libraries for App Development
The broader TTS toolkit that sits alongside voice cloning.
Audio stack
7 Best AI Tools to Elevate Audio Apps
ASR, enhancement, denoising and the complete audio pipeline.
Interpretation
AI Interpretation Platform Development in 2026
The companion playbook for multilingual voice experiences.
Call centre
AI Call Assistants: Third-Party APIs for Business
VoIP bridging, barge-in and the telephony layer for cloned voices.
ASR
Speech Recognition Accuracy in Noisy Environments
The upstream ASR decisions that define the agent’s overall latency.
Ready to ship real-time voice cloning in your product?
Real-time voice cloning technology is shipped and production-ready in 2026. Sub-100 ms time-to-first-audio is available from multiple vendors, quality is broadcast-grade in the PVC tier, and the unit economics work in call centres, accessibility, dubbing, games, education and media localisation. What separates a product that makes it to production from one that stalls in pilot is the four-layer discipline: pick the cloning tier that matches the use case, hit the latency budget with overlapping ASR/LLM/TTS, wire consent and watermarking as first-class architecture, and measure speaker similarity and WER on a weekly cadence.
If you want a team that has shipped this across telemedicine, education, interpretation and customer support — and that can give you a conservative cost model with a realistic 12-week timeline — book a call. Our Agent Engineering workflow gets the first production pilot in front of real users fast.
The book · Volume 7 of 7
AI for Video: A Complete Guide to Intelligence in Video Products: From Real-Time Pipelines and Agents to Serving, Cost, Compliance, and Verticals
Getting a cloned voice under 500 ms is a real-time pipeline problem as much as a model problem. Volume 7 covers latency budgets in a call, where AI fits into a WebRTC pipeline, agents as engineering, serving on vLLM and Triton, cost per stream-hour and the EU AI Act. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Let’s build your voice-cloning product
20+ years of multimedia and AI engineering, 250+ projects shipped since 2005. Book 30 minutes and walk away with a vendor recommendation, a realistic cost-per-minute, and a 12-week plan tailored to your use case.

