
Key takeaways
• Sub-second latency at mass scale is a solved problem once you pick the right protocol. Sub-second latency means less than one second glass-to-glass, from camera capture to the viewer’s screen. WebRTC and the new MoQ (Media over QUIC) deliver glass-to-glass under 500 ms; LL-HLS and CMAF chunked sit at 2–5 seconds; classic HLS at 15–30 seconds.
• Architecture matters more than protocol. A cascaded SFU tree (master + edge) is what carries WebRTC from 100 to 100,000 viewers; an LL-HLS-only setup will not get you under 2 seconds no matter how it is tuned.
• The cost gap is in self-hosting, not in managed services. At October 2026 US list prices, managed delivery costs about $48–72 per 1,000 viewer-hours whether it is LL-HLS or real-time (AWS IVS, Mux, Cloudflare Stream). Self-run LL-HLS on a CDN drops to $18–77 depending on volume tier, so a hybrid keeps WebRTC capacity for the small talking tier only.
• MoQ is the next chapter. The IETF transport draft reached draft-22 on 1 October 2026, and the working group plans to send it to the IESG in December 2026. Cloudflare’s MoQ relay runs in 330+ cities as a free tech preview. Expect pilots in 2026 and production adoption through 2027.
• Latency choices are revenue choices. Industry estimates say sub-3-second live sports retains viewers 2–3x longer than 7–9 second delays; sub-250 ms video-and-odds synchronisation lifts live-betting volumes 25%; auction houses see 20% more bids when video is interactive.
Updated October 2026: AWS IVS, Mux, Cloudflare Stream and CloudFront list prices re-checked (Cloudflare began billing WebRTC delivery on 15 October 2026), MoQ transport draft-22, WHEP sent to the IESG, and a new latency-budget breakdown.
Why Fora Soft wrote this playbook
Fora Soft has been shipping live video products since 2005 — 250+ projects across real-time video, streaming and AI. Sub-second streaming at mass scale started as a single-product challenge for us — WorldCast Live, a platform that streams HD concerts at 0.4–0.5 s glass-to-glass to up to 10,000 simultaneous viewers with audience-and-performer interaction in real time — and has since become a recurring requirement on our roster: live shopping (Sprii), live-event translation (the software we developed for Blaze Streaming Media’s Volo), enterprise video conferencing (ProVideoMeeting), and the broader real-time video stack on BrainCert.
This playbook collapses what we have learned across those products — and delivered through our video streaming development team — into a single decision framework. The numbers come from public sources (Cloudflare engineering blog and Stream pricing, Mux pricing, AWS IVS and CloudFront price pages, the IETF MoQ and WISH working groups, Apple LL-HLS documentation), re-checked in October 2026. The architecture patterns are battle-tested. Skim the key takeaways for the headline, jump to the protocol comparison for the trade-off you came for, or jump to the five-question decision framework.
Building a live streaming product and need sub-second latency at scale?
Book a 30-minute scoping call with our streaming lead. We will sanity-check your protocol choice, fan-out architecture, and CDN strategy against your specific viewer profile.
The latency taxonomy — and why “low” is not the same as “interactive”
Latency in live streaming is glass-to-glass: the time between a photon hitting the encoder’s camera and a photon leaving the viewer’s screen. Marketing teams use it loosely; engineering teams need to be precise. The industry has converged on four tiers.
| Tier | Glass-to-glass | Use cases | Default protocol |
|---|---|---|---|
| Interactive | < 400 ms | Live betting, auctions, telemedicine, video calling | WebRTC, MoQ, AWS IVS Real-Time |
| Low | 1–3 s | Sports, live shopping, gaming, esports | LL-HLS, LL-DASH, CMAF chunked, MoQ |
| Near-real-time | 3–6 s | Concerts, news, conferences | CMAF chunked, SRT |
| Standard | 10–30 s | Music streams, archives, broadcast TV simulcast | HLS, DASH, RTMP |
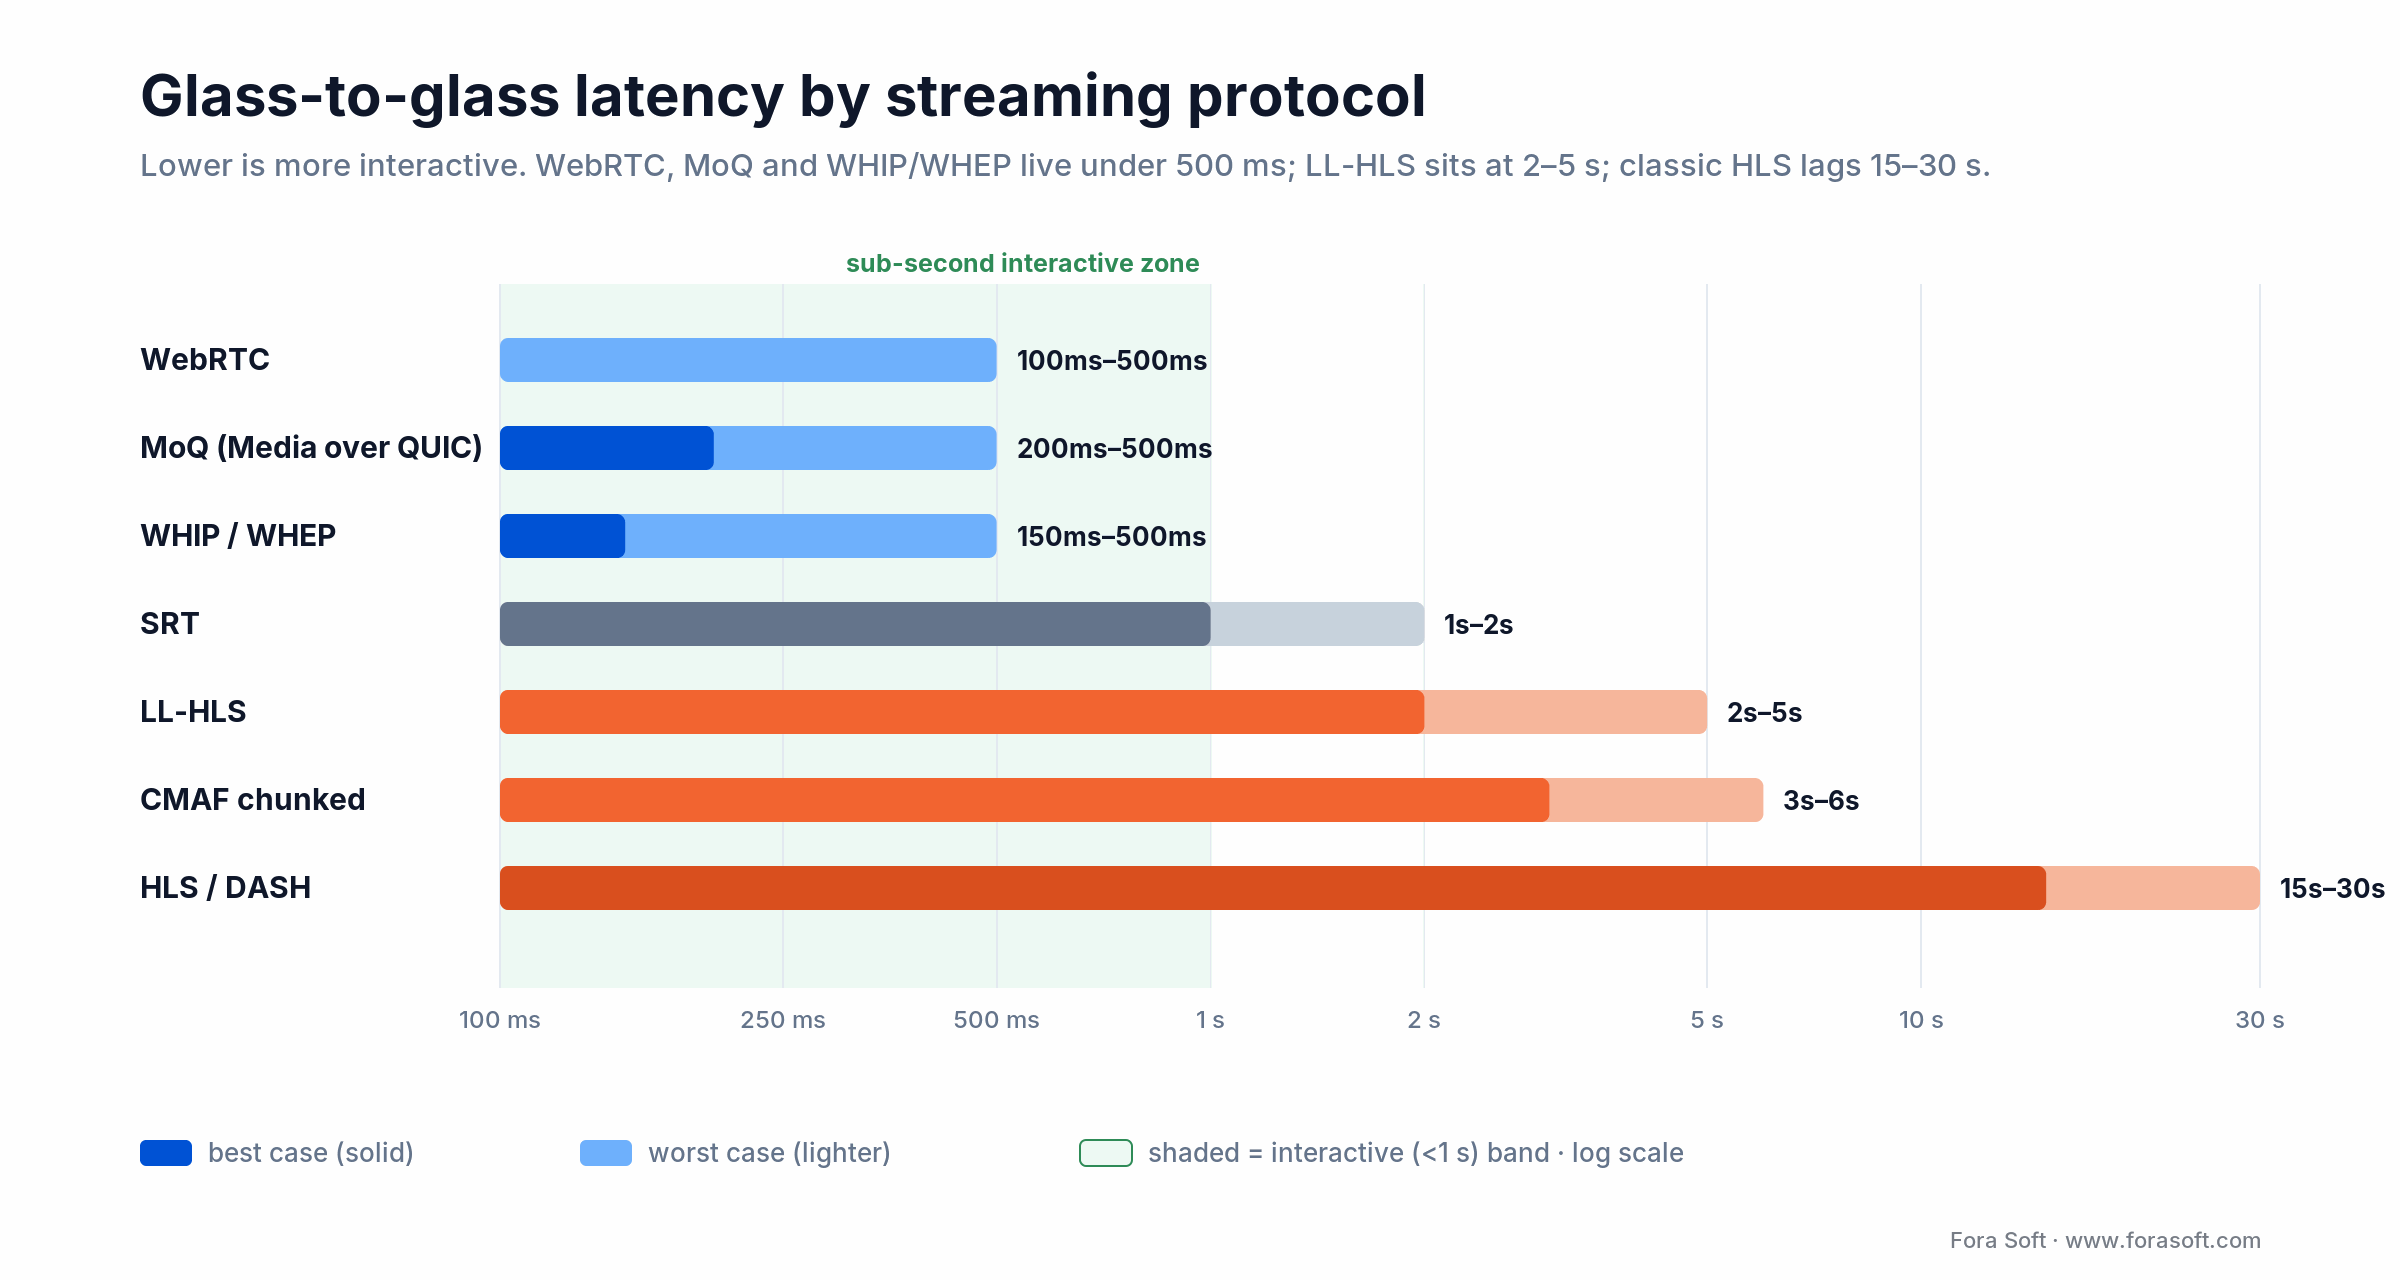
Figure 1. Where each protocol lands on the glass-to-glass latency scale — only WebRTC, MoQ and WHIP/WHEP clear the sub-second bar.
Picking a tier is a product choice, not a technical preference. A live concert can survive at 3 seconds; a live auction collapses at 1.5 seconds. Map the use case to the tier first, then choose the protocol.
What is sub-second latency, and where do the milliseconds go?
Sub-second latency means the viewer sees a frame less than one second after the camera captured it, measured glass-to-glass. It is the threshold where chat, bids and two-way talk feel live. In 2026 only WebRTC-based delivery (including WHIP/WHEP) and MoQ reach it reliably at scale; LL-HLS stops at about 2 seconds.
A sub-second stream is a budget, not a protocol setting. Every stage spends part of the 1,000 ms, and the player buffer is usually the biggest line item. The table shows a typical split we plan against for a 720p interactive stream.
| Stage | WebRTC / MoQ budget | LL-HLS for comparison | What controls it |
|---|---|---|---|
| Capture and encode | 30–100 ms | 50–200 ms | B-frames off, zero-latency tune, hardware encoder |
| First mile and ingest | 20–100 ms | 50–300 ms | WHIP or SRT instead of RTMP, ingest close to the source |
| Server: forward, transcode, package | 10–150 ms | 500–1,000 ms | SFU forwarding vs transcoding; part duration in LL-HLS |
| Delivery to viewer | 20–150 ms | 100–500 ms | Edge distance, cascade depth, CDN live config |
| Player buffer, decode, render | 50–300 ms | 1–3 s | Jitter buffer target; parts held before playback |
The arithmetic explains why LL-HLS cannot go sub-second: its player must hold a few partial segments before it starts, and that buffer alone eats more than the whole WebRTC budget. Vendor benchmarks line up with the table. Wowza’s October 2026 test of Streaming Engine 4.12 measured 258 ms glass-to-glass over WebRTC with a 130 ms network round trip, and 367 ms with packet-loss recovery switched on (Wowza, 2026).
Why sub-second latency moves real revenue
A second of latency is the difference between a feature and a product category. Six places where the number shows up directly in revenue.
1. Live sports retention. iGameMedia and Dolby OptiView data: viewers stay 2–3x longer on sub-3-second feeds than 7–9-second feeds. The neighbour-shouts-GOAL problem is brutal — once a viewer learns the local pub is ahead of the stream, they switch off.
2. Live betting. Sub-250 ms synchronisation of video and odds drives ~25% uplift in betting volume per public industry estimates. Micro-betting (next ball, next play) is impossible above one second.
3. Live auctions. Industry and vendor estimates credit sub-second auction feeds with ~20% more bids and ~25% more remote participation versus comparable mid-latency feeds. Bid-and-confirm cycles fail when delays exceed the auctioneer’s gavel. If you’re building one, our guide to live auction software covers the bid engine, anti-sniping, and latency budget in depth.
4. Interactive concerts and live shopping. Real-time chat, reactions, polls and Q&A only work below ~1 second. Above that, the comment thread reads like reading the news after it happened.
5. Telemedicine. Sub-300 ms is a clinical requirement for examination video; outside that range, the patient cannot read the doctor’s face fast enough to feel listened to.
6. Esports and game streaming. Twitch’s low-latency mode and YouTube’s ultra-low-latency setting are direct responses to spoiler-by-chat — viewers will not tolerate a 6-second feed when chat is real-time.
Protocol comparison: WebRTC, MoQ, LL-HLS, CMAF, SRT, WHIP/WHEP
Six protocols matter in 2026. The table below is the cheat sheet we hand junior engineers on day one of a streaming engagement.
| Protocol | Latency | Scale ceiling | Reach for it when |
|---|---|---|---|
| WebRTC | 100–500 ms | 10k+ via cascaded SFU | Two-way interaction is core (calling, auctions, betting). |
| MoQ (Media over QUIC) | 200–500 ms | 100k+ via relay network | You want sub-second at WebRTC scale, plus CDN-style fan-out. |
| WHIP / WHEP | < 500 ms | 5k–100k | You want WebRTC ingest/playback over plain HTTP without custom signaling. |
| SRT | 1–2 s | Point-to-point | Contribution feeds (camera-to-cloud), broadcast pipelines. |
| LL-HLS | 2–5 s | 100k+ via CDN cache | Cost-sensitive mass distribution; one-way streams. |
| CMAF chunked | 3–6 s | 100k+ via CDN cache | Cross-platform standard playback (DASH + HLS) with chunk transfer. |
A note on classic RTMP: it is dead for delivery in 2026 and dying for ingest as WHIP matures. Keep it only where legacy encoders demand it.
Reach for LL-HLS when: the stream is one-way, 2–5 s latency is acceptable, and cost per viewer-hour has to stay in the low cents — it rides ordinary CDN cache, so it scales to 100k+ viewers cheaply.
WebRTC at scale: SFU mesh and the cascaded tree
Vanilla WebRTC handles a 1:1 call beautifully and falls over at 50 viewers. The reason is the math: peer-to-peer mesh requires N×(N-1)/2 connections, every encoder uploads N times, every viewer renders N feeds. The fix is a Selective Forwarding Unit (SFU) that ingests one publisher stream and forwards it to every subscriber.
How low is WebRTC latency in practice? In one region on healthy networks, WebRTC lands at roughly 150–400 ms glass-to-glass; network round trip, loss recovery and the jitter buffer make up most of it. Across continents add the propagation delay, which is why big audiences need edge SFUs close to viewers. Designing that topology is what our custom WebRTC architecture team does first on every sub-second project.
A single SFU node tops out at roughly 500–5,000 concurrent subscribers depending on bitrate and CPU. Past that, you cascade: a master SFU receives the publisher feed, edge SFUs subscribe to the master and re-fan-out to their own viewer pool. WCL’s original architecture used a tree of Master and Edge Kurento nodes; modern equivalents (LiveKit, mediasoup, Janus, ion-sfu) follow the same pattern.

Figure 2. The cascaded SFU tree: a master SFU feeds edge SFUs, each re-fanning ~500 viewers, so WebRTC scales without a peer-to-peer mesh.
Three knobs make the difference between this architecture surviving and collapsing.
Simulcast. The publisher uploads three quality layers (e.g., 180p / 360p / 720p). The SFU picks the right layer per subscriber. Dropping a viewer from 720p to 360p when their bandwidth dips keeps the stream alive without freezing the whole room.
SVC (scalable video coding). One stream, multiple temporal/spatial layers, less encoder overhead than simulcast. AV1 SVC is the modern target.
TURN scaling. 10–15% of viewers will be behind symmetric NATs and need a TURN relay. Provision TURN bandwidth at 1.5× expected publisher bitrate × viewer count behind NAT — underprovisioned TURN is the #1 cause of “live stream stalled” tickets.
Reach for a cascaded WebRTC SFU when: two-way interaction is the core of the product (calling, auctions, betting) and you need sub-500 ms — size the master for the first ~500 viewers and add one edge node per additional ~500.
MoQ (Media over QUIC) — the next protocol generation
MoQ — Media over QUIC — is the IETF working group’s answer to the “sub-second at CDN scale” problem. It rides on top of QUIC directly (or via WebTransport), uses a relay topology that maps cleanly to existing CDN infrastructure, and avoids the per-viewer TCP-stream overhead of HLS by sharing chunks across subscribers at the relay.
Three reasons MoQ matters now and not in 2028.
Deployments are running. Cloudflare’s MoQ relay runs on its edge in 330+ cities as a free tech preview, with a planned price of about 5 cents per GB at general availability. At NAB Show 2026, 11 vendors demoed interoperating MoQ implementations, and the October 2026 DEMOQED conference in San Francisco included a talk on shipping MoQ for Instagram and Facebook Live ingest. Our MoQ production status report tracks who runs what.
Specification stability. The IETF MoQ transport draft reached draft-22 on 1 October 2026, and the working group’s milestone is to request IESG publication in December 2026. The object model has held steady across recent drafts, but wire details still change between versions, so pin a draft version and budget one upgrade before the RFC.
Architectural fit. Unlike WebRTC, MoQ does not require an SFU per region; the relay topology scales like a CDN. Unlike LL-HLS, it does not pay the segmentation latency tax. We ship MoQ-ready streaming products today through our custom MoQ / QUIC development practice.
Reach for MoQ when: you need WebRTC-class latency for a one-to-many or few-to-many stream and your viewer count is in the tens of thousands or higher. Use Cloudflare’s relay or roll your own with one of the open-source Go or Rust implementations.
Curious whether MoQ fits your roadmap?
We have shipped early MoQ pilots and run production WebRTC stacks with cascaded SFUs. A 30-minute call narrows the choice to one or two architectures specific to your viewer profile.
WHIP and WHEP: WebRTC ingest and egress over plain HTTP
WHIP and WHEP are the two small protocols that finally make WebRTC as easy to wire up as RTMP. Both replace the bespoke, hand-rolled signaling that every WebRTC stack used to ship with a single HTTP request. If sub-second latency is the goal, they are how the stream gets in and out.
WHIP for ingest. WHIP (WebRTC-HTTP Ingestion Protocol) became RFC 9725 in March 2025, so it is frozen and safe to build on. One HTTP POST negotiates the whole WebRTC session, which is why OBS, Cloudflare, AWS IVS and Mux all speak it without custom glue. It is the modern replacement for RTMP contribution — same “point an encoder at a URL” simplicity, none of the multi-second latency tax.
WHEP for playback. WHEP does the mirror image for egress: an HTTP request pulls a WebRTC stream out of a media server. It is not an RFC yet, but it is close: draft-05 (October 2026) passed Working Group Last Call in July 2026 and has been submitted to the IESG for publication. It is already interoperable across the major players and fine to run in production; since October 2026 Cloudflare Stream bills WebRTC (WHEP) playback as regular delivery. Our WHEP egress explainer walks the handshake step by step, and our WHIP and WHEP vs RTMP guide covers migrating a legacy pipeline off RTMP.
Reach for WHIP/WHEP when: you want WebRTC-grade sub-second ingest or playback but do not want to build and maintain a signaling layer. Standardise on WHIP for contribution now; add WHEP for playback wherever your clients support it.
Hybrid architecture: WebRTC interactive + LL-HLS mass
Most production streaming products today — live shopping, interactive concerts, esports — are not pure WebRTC or pure LL-HLS. They are hybrids. The interactive tier (10–200 active participants who can talk back, ask questions, place bids) runs on WebRTC; the mass passive tier (everyone else) runs on LL-HLS via CDN. The transcoder bridges the two.
The economics are the reason. A 720p stream at 2 Mbps to 10,000 concurrent viewers is about 9 TB of egress per hour. On a managed real-time service that is roughly $480–720 per hour at October 2026 list prices (AWS IVS Real-Time charges $0.048–0.072 per participant-hour). Self-hosted, a WebRTC SFU fleet must push all 9 TB from your own servers, with TURN on top, while LL-HLS rides cacheable CDN delivery at $0.02–0.085 per GB on CloudFront list prices. A hybrid architecture pays the WebRTC premium only for the small interactive tier and uses cheaper, slightly higher-latency delivery for the rest.
How do you relay a real-time call to a large RTMP or HLS audience? Composite the call on the server (a media server mixer, or a managed feature such as AWS IVS server-side composition), push the composite over WHIP or RTMP to a packager, and serve it as LL-HLS through a CDN. The people in the call stay sub-second; the audience watches 2–4 seconds behind.
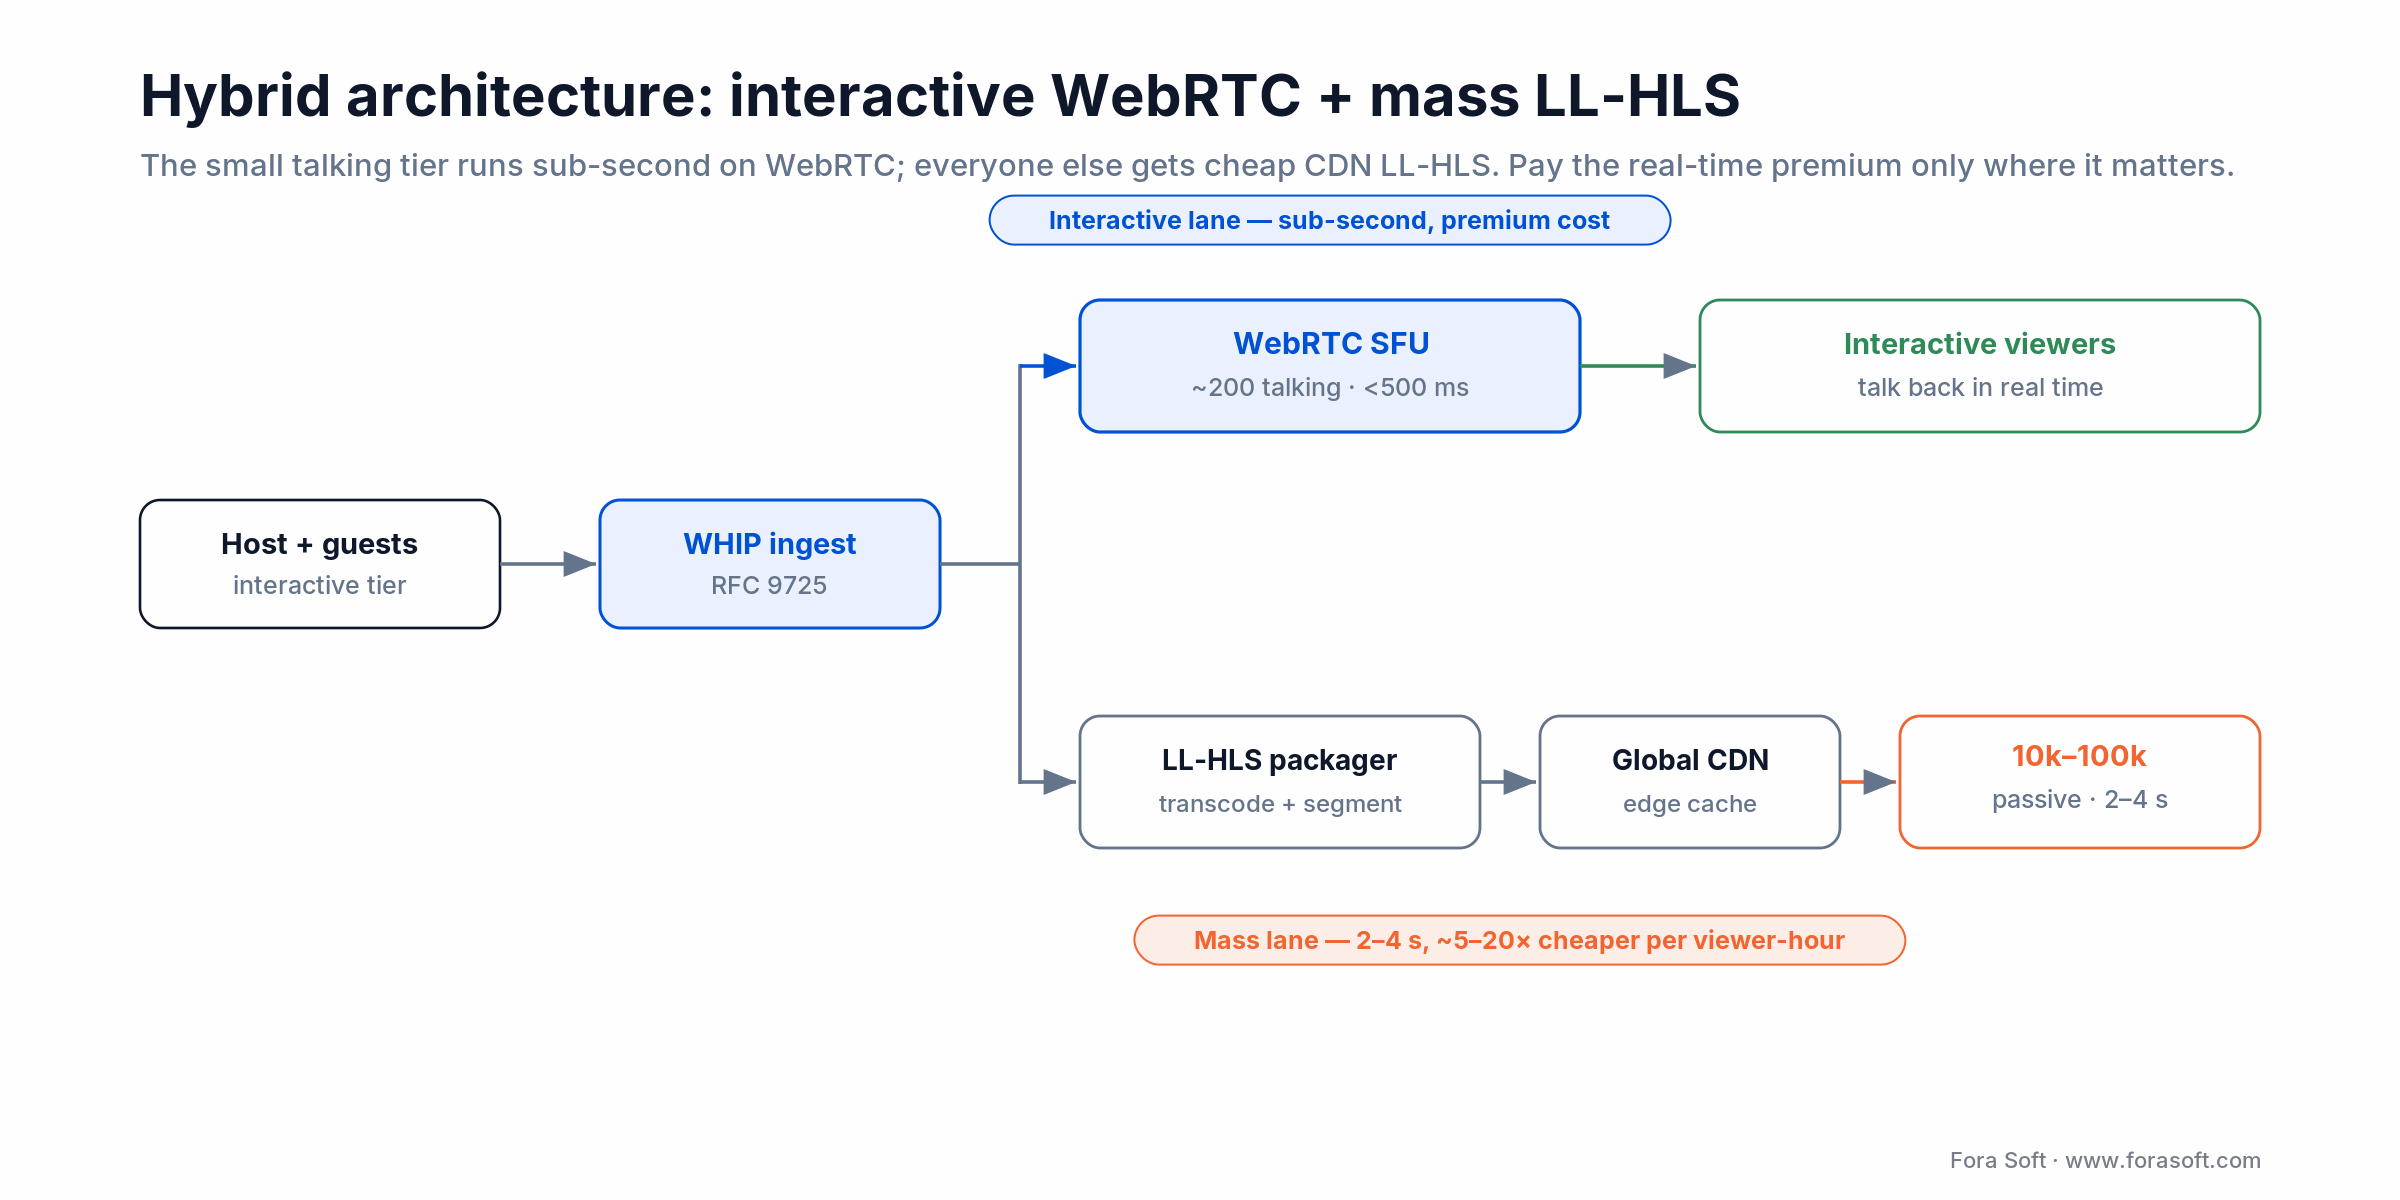
Figure 3. A hybrid split: pay for sub-second WebRTC only for the small talking tier; serve the mass audience cheaply over LL-HLS and a CDN.
The trade-off is that the passive tier sees the stream 2–4 seconds later than the interactive tier. For most product designs that is acceptable; the active participants do not see the chat from the passive viewers in real time anyway.
Reach for a hybrid WebRTC + LL-HLS split when: your talking tier is under ~200 and your passive tier is over ~5,000. It shrinks the SFU and TURN fleet to the talking tier (200 of 10,000 viewers is 2%) while keeping that tier sub-second. See the LL-HLS deep-dive for the mass-tier tuning.
Cost economics in 2026 (per 1,000 viewer-hours)
At October 2026 US list prices, delivering 1,000 viewer-hours of 720p video costs about $48–72 on managed services, LL-HLS or real-time alike, and $18–77 on a self-run CDN. The figures below come from the public price pages of AWS IVS, Mux, Cloudflare Stream and Amazon CloudFront, checked on 19 October 2026. We assume 720p at about 2 Mbps, or roughly 0.9 GB per viewer-hour, and count delivery only.
| Stack | Latency | Cost / 1k viewer-hr | Notes |
|---|---|---|---|
| AWS IVS Low-Latency (HLS) | 2–5 s | $24–36 SD, $48–72 HD | Per hour delivered; tiers fall with monthly volume. |
| Mux | LL-HLS, a few seconds | ~$48 (720p) | $0.0008 per delivered minute at 720p; live input from $0.025 per minute per stream. |
| Cloudflare Stream | < 1 s (WebRTC) or HLS | $60 | $1 per 1,000 delivered minutes for HLS, DASH and WebRTC (WHEP); ingest and encoding free. WebRTC delivery billed since 15 Oct 2026. |
| AWS IVS Real-Time | < 300 ms | $48–72 | $0.048–0.072 per participant-hour; hosts and viewers billed the same. |
| Self-run LL-HLS on CloudFront | 2–5 s | $18–77 | 0.9 GB × $0.02–0.085 per GB; committed contracts go lower. |
| Self-hosted WebRTC SFU | 100–500 ms | Servers + egress | Every viewer is a separate stream from your servers; bandwidth dominates at scale. |

Figure 4. Delivery cost per 1,000 viewer-hours at October 2026 US list prices — managed LL-HLS and managed real-time now cost about the same; self-running LL-HLS on a CDN is where the savings are.
Bandwidth is the dominant variable at scale. A 720p stream at 2 Mbps to 10,000 concurrent viewers is 20 Gbps of egress. CDN bandwidth pricing dominates the bill once you cross ~5,000 concurrent viewers, so the practical saving comes from the per-GB rate you negotiate, not from the protocol label on a managed price list.
Encoder settings that move latency by hundreds of ms
Even with the right protocol, the encoder can blow the latency budget. Five settings to audit on day one.
1. B-frames off. B-frames depend on future frames and add encoder buffering. For interactive streams, set bframes=0; the bitrate cost is small (~5%) and the latency cost is huge (50–200 ms saved).
2. Short GOP / I-frame interval. 2-second GOP for LL-HLS; 1-second or sub-second for interactive. Shorter GOPs let segments close faster and players start faster.
3. Codec choice. H.264 has the lowest encode latency and the widest device support; HEVC and AV1 give 30–50% bandwidth savings at the cost of 50–100 ms more encoding latency. AV1 SVC is the future for WebRTC; legacy devices still need H.264 fallback.
4. Tune for zero-latency, not film. x264 tune=zerolatency preset=veryfast sacrifices some bitrate efficiency for buffer-free encoding. Necessary for interactive workloads, optional for sub-3-second LL-HLS.
5. Hardware acceleration. NVIDIA NVENC, Intel Quick Sync, Apple VideoToolbox encode 5–10× faster than software at the price of slightly higher bitrate at the same quality. For a real-time pipeline, hardware encode is mandatory above 1080p.
Network resilience: surviving the lossy last mile
Sub-second latency is fragile. WebRTC starts to break above ~5% packet loss; LL-HLS handles loss better at the cost of latency. Four mechanisms keep streams alive on real networks.
FEC (forward error correction). Send 10–20% redundant data so receivers can reconstruct lost packets without retransmission. Trades bandwidth for latency stability.
NACK and selective retransmit. The receiver requests specific lost packets; the sender retransmits only what is missing. Effective up to ~150 ms RTT.
Jitter buffer tuning. Aggressive buffers (50–100 ms) for interactive, conservative buffers (200–500 ms) for one-way. The buffer is what absorbs microbursts of network instability.
Bandwidth estimation. Google’s gcc and BBR-based congestion control. Modern WebRTC stacks ship this by default; the trap is old forks of open-source stacks that never picked up upstream congestion-control fixes.
Mini case: WorldCast Live shipping sub-second to 10,000 concurrent
WorldCast Live streams HD concerts at 0.4–0.5 s glass-to-glass to up to 10,000 simultaneous viewers across multiple embed sites. The product requirement was unforgiving: viewers and performers had to talk back and forth in real time during a live concert; latency above 1 second made Q&A unworkable.
The architecture: WebRTC end-to-end, multichannel audio (5 channels for stage mix), bitrate raised to 1.5 Mbps for true HD, increased audio sampling for lossless music quality, and a cascaded Kurento tree (Master + Edge nodes). Master handles the first 500 viewers; each Edge adds another 500. The tree extends as the audience grows.
Outcome: 0.4–0.5 s glass-to-glass at up to 10,000 simultaneous viewers, with dynamic quality adjustment keeping viewers on poor connections in the stream instead of freezing. The same tree also carries full-duplex sessions where performers in different cities play together live. The architecture has carried multi-thousand-viewer concerts without a meaningful rebuild.
Five pitfalls we see in low-latency streaming projects
1. Picking the wrong protocol for the use case. Trying to hit 500 ms with LL-HLS is a fool’s errand; trying to hit 100k viewers with vanilla WebRTC will bankrupt you. Map use case to tier to protocol — in that order.
2. Underprovisioned TURN. 10–15% of viewers will need TURN relay; provisioning at 1.5× expected NAT bandwidth is the floor. Underprovisioned TURN is the top cause of “why does the stream stall for some users” tickets.
3. Missing simulcast. A single 720p stream sent to a viewer on 3G freezes the room. Always simulcast at least three layers (180p / 360p / 720p) and let the SFU pick.
4. B-frames left on. Every interactive WebRTC stream we have audited that had B-frames enabled was paying 100–200 ms of avoidable latency. Audit first, then optimise.
5. CDN configured for VOD, not live. Stale-while-revalidate, long cache TTLs, missing chunked-transfer support, no LL-HLS partial-segment cache configuration. The default CDN profile is wrong for live; always configure live-specific edge rules.
A decision framework — choose the right stack in five questions
Q1. What is the maximum acceptable glass-to-glass latency? Under 500 ms → WebRTC or MoQ. 1–3 s → LL-HLS. 3–6 s → CMAF chunked. Above 6 s → standard HLS / DASH.
Q2. How many concurrent viewers do you expect peak? Under 1k → single SFU. 1k–10k → cascaded SFU or hybrid. 10k+ → MoQ relay or hybrid WebRTC+LL-HLS+CDN.
Q3. How many viewers actually need to talk back? Under 200 → WebRTC interactive tier sized for that. Above 200 → hybrid architecture is the only way the math works.
Q4. What is your target unit cost per viewer-hour? Under about $0.03 → self-run LL-HLS on a CDN at negotiated rates. Around $0.05–0.07 → managed services at list price (AWS IVS, Mux, Cloudflare Stream), real-time included. Above $0.10 → pure WebRTC is affordable for the whole audience.
Q5. Is latency a hard product requirement (betting, auctions) or a polish item (concerts, news)? Hard → over-invest now in cascaded SFU and FEC. Polish → ship LL-HLS first, upgrade selectively.

Figure 5. Five questions that pick the stack — latency target and viewer count choose the protocol; the talking-tier size decides pure vs hybrid.
When NOT to chase sub-second latency
Three cases where the cost outweighs the benefit. First, music or talk-only streams where the audience is passive and listens, not interacts. The standard 6-second TV-style delay is fine and saves significant infrastructure spend.
Second, archival workflows or long-tail VOD that catches up after the live moment. Use HLS or DASH; reach for low-latency only on the live edge.
Third, products in clear MVP mode where infrastructure cost is the dominant constraint. Ship LL-HLS for the first 12 months; upgrade to a hybrid stack once you have validated demand and the unit economics support it.
KPIs: what to measure on every live stream
Quality KPIs. Glass-to-glass latency p50 and p95 (measured via SMPTE timecode or NTP-stamped audio tones). Packet loss rate (target under 2%). Freeze ratio (frozen frame seconds divided by stream seconds, target under 1%). VMAF or PESQ scores for video and audio.
Business KPIs. Average watch time (compare against a 6-second-latency baseline). Chat-to-stream sync delta (target under 1 second). Bid completion rate for auctions; play-action latency for live betting; question-to-answer time for interactive Q&A.
Reliability KPIs. SFU CPU utilisation (target under 70%). TURN bandwidth utilisation (target under 60% with autoscale). Edge node failure-recovery time (target under 5 seconds). Cost per concurrent viewer-hour, tracked per channel weekly.
How to measure glass-to-glass latency. Point the camera at a millisecond clock (or burn a timecode into the source), film the publisher and viewer screens side by side, and subtract the two readings; repeat 20+ times for p50 and p95. For screen sharing, share a page showing the clock and compare it with the viewer’s render. For WebRTC, add getStats() fields such as round-trip time and jitter-buffer delay to every session so you can see which stage moved.
Time to first frame. Track it next to latency: viewers judge “instant” by start time. Short keyframe intervals (1 s), starting playback on the newest keyframe instead of buffering a full segment, and pre-warmed connections to the edge keep first frame under one second on WebRTC and MoQ.
Adjacent topics worth a deeper read
Five companion reads round out the streaming-product picture.
Protocols and APIs. For the full range of latency tiers beyond sub-second, with platform APIs compared by latency and price, read our guide to low latency video streaming protocols and APIs.
Architecture deep-dive. The custom video conferencing architecture guide covers the SFU, MCU and P2P trade-offs in more detail.
Reliability foundation. Sub-second latency is moot if the stream crashes. See our crash-proof software guide for SLOs, error budgets and DORA metrics applied to streaming.
Hiring & teams. Real-time streaming is a specialist hire; our LiveKit hiring guide covers skills, rates and interview questions for the WebRTC and SFU specialists you will need.
Mobile foundations. The Android foreground service guide covers the lifecycle scaffolding mobile streaming clients need so the OS does not kill them mid-stream.
FAQ
What does sub-second latency mean?
Sub-second latency means a viewer sees each frame less than one second after the camera captured it, measured glass-to-glass. In live streaming it is reached with WebRTC (including WHIP/WHEP) or MoQ; LL-HLS bottoms out at about 2 seconds.
How do edge delivery networks compare to standard HTTP CDNs for sub-second streaming?
A standard HTTP CDN caches segments, so it scales cheaply but adds the 2–5 seconds of LL-HLS buffering. Sub-second needs an edge that forwards media in real time — WebRTC SFUs or MoQ relays placed close to viewers — which costs more per viewer-hour unless you bought it as a managed service.
Can one video API switch between sub-second small groups and 5-second large broadcasts?
Yes, if it supports both a real-time tier and an HLS tier from the same session. AWS IVS, for example, can composite a Real-Time stage server-side and broadcast it to a Low-Latency HLS channel, so the talking group stays sub-second while the large audience watches a few seconds behind.
What is the lowest latency achievable for live streaming today?
In production, around 100–200 ms glass-to-glass with WebRTC on healthy networks within a single region. AWS IVS Real-Time advertises sub-300 ms; Cloudflare’s WebRTC delivery sits below 1 second to global audiences. Below about 100 ms across continents you run into speed-of-light limits.
Can LL-HLS deliver sub-second latency?
No. Apple’s LL-HLS spec targets 2–5 seconds via partial segments and preload hints. Anyone advertising sub-1-second LL-HLS is either using a non-standard variant or measuring from the wrong point. For sub-second latency, use WebRTC or MoQ.
How many concurrent viewers can a single WebRTC SFU handle?
Roughly 500–5,000 depending on bitrate, codec, and CPU. A high-end LiveKit or mediasoup node tuned for 720p H.264 SFU forwarding can hit 5,000 subscribers; for higher bitrates or more publishers, plan to cascade across multiple nodes.
Is MoQ ready for production in 2026?
Yes for early adopters. The IETF transport draft reached draft-22 on 1 October 2026 and is planned for IESG submission in December 2026; Cloudflare runs a free MoQ relay tech preview across 330+ cities; 11 vendors showed interoperating implementations at NAB Show 2026. Pin a draft version, pilot in 2026 and plan production for 2027. We are happy to scope an MoQ pilot if your roadmap supports it.
When should we use a hybrid WebRTC + LL-HLS architecture?
Whenever the active interactive tier is small (under ~200 talking participants) and the passive viewer tier is large (5,000+). The hybrid pays the WebRTC premium only for the interactive tier and uses cheap CDN delivery for the rest, cutting infrastructure cost 50–70% versus pure WebRTC.
What is WHIP and why is it replacing RTMP for ingest?
WHIP (RFC 9725, published March 2025) is a simple HTTP-based protocol for publishing a WebRTC stream into a server. It eliminates the bespoke signaling layers most WebRTC stacks ship and is supported by OBS, Cloudflare, AWS IVS, Mux and most modern streaming infrastructure. WHEP is its playback counterpart. Together they make WebRTC ingest as plug-and-play as RTMP without the latency tax.
How much does a sub-second mass streaming product cost to build?
A scoped MVP with a hybrid WebRTC + LL-HLS architecture typically lands in a 6–10 week engineering window on a healthy team. Our agentic-engineering practice compresses the typical timeline. Infrastructure cost depends entirely on viewer counts; see the cost economics section for October 2026 per-viewer-hour prices. For a scoped estimate against your specific use case, a 30-minute call is usually enough.
What metrics should we monitor on a live stream?
Glass-to-glass latency p50/p95, packet loss percentage, freeze ratio (frozen seconds / total seconds), VMAF or PESQ quality scores, SFU CPU utilisation, TURN bandwidth utilisation, and cost per concurrent viewer-hour. See the KPI section for the full list and how to measure latency.
What to read next
Architecture
Custom video conferencing architecture in 2026
P2P, SFU, MCU — the architecture trade-offs that underpin every low-latency streaming product.
Media servers
What is Kurento?
The open-source WebRTC media server that powered the original WorldCast Live tree.
Hiring
How to hire LiveKit developers in 2026
Skills, rates and interview questions for the WebRTC and SFU specialists you will need.
Reliability
Building reliable, crash-proof software in 2026
SLOs and error budgets applied to live streaming — sub-second latency means little if the stream crashes.
Mobile
Foreground services and deep links on Android 14
The lifecycle scaffolding mobile streaming clients need so the OS does not kill them mid-stream.
Ready to ship sub-second streaming to thousands of viewers?
Sub-second streaming at mass scale is a solved problem in 2026. The two paths are a cascaded WebRTC SFU tree (proven, server-heavy, sub-500 ms) and the new MoQ relay model (CDN-class scale at WebRTC-class latency, cost still being shaped). For most products today, a hybrid WebRTC interactive tier plus LL-HLS mass tier delivers the right balance of cost and experience.
If you want a second pair of eyes on your streaming architecture, or a team that has shipped sub-second streaming products since the WebRTC 1.0 era, we are a 30-minute call away. We will return a written architecture memo with cost estimates inside a week.
The book · Volume 2 of 7
Video Streaming: A Complete Guide to Video Delivery: From Network Protocols and Transport to Ingest, HLS, and MPEG-DASH
Sub-second at scale starts with a glass-to-glass latency budget, and Volume 2 is built around it. It covers what networks do to a live stream, TCP versus UDP and congestion control, QUIC and HTTP/3, ingest over SRT and RIST, and segment protocols from LL-HLS to CMAF. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Need streaming under one second to thousands of viewers?
Tell us about your viewer profile and budget. We will return an architecture memo with protocol choice, fan-out plan, and cost per viewer-hour inside a week.

