
Key takeaways
• Two portable patterns. Use TTL + Dead Letter Exchange for durable, same-delay pipelines; use per-message delays when each timer differs. Both run on plain RabbitMQ.
• The upstream plugin is dead; the fork lives on. Team RabbitMQ archived the x-delayed-message plugin because Mnesia was removed in RabbitMQ 4.3. The CloudAMQP fork moved to a node-local Leveled store and runs on 4.3.3+ (August 2026), but still keeps a single, unreplicated copy of each delayed message.
• Quorum queues now delay natively. RabbitMQ 4.4 (October 20, 2026) lets you publish a message with an x-opt-delivery-time timestamp and the quorum queue holds it until then — no plugin, no exchange type. RabbitMQ 4.3 (April 2026) added built-in delayed retries with linear back-off — min(retry-min × delivery-count, retry-max) — Raft-replicated, no DLX dance.
• Delayed is not scheduled. For weeks-out schedules, multi-step workflows, or audit-grade retries, reach for Temporal, EventBridge, or Azure Service Bus — not RabbitMQ.
• We ship this in production. Fora Soft runs RabbitMQ delayed messages on video platforms for renewal emails, payment webhooks, and deferred media jobs — see the mini case below.
Updated October 2026: RabbitMQ 4.4 (October 20, 2026) adds native per-message delayed messages to quorum queues; the CloudAMQP plugin fork now runs on 4.3; Amazon MQ supports 4.3 delayed retries; hosting prices rechecked.
Why Fora Soft wrote this playbook
Get delayed messaging wrong and the failure is quiet and expensive: a payment webhook that never retries, a class reminder that fires twice, a node recycle that drops every scheduled job on the floor. We’ve been building video, audio, and e‑learning platforms since 2005 (250+ projects), and almost every production system we ship needs delayed or repeating side-effects somewhere — a push 10 minutes after a lesson starts, a webhook retry with back-off, a renewal reminder 24 hours out, a nightly cleanup of temp uploads.
In the multi-node, multi-region architectures we deploy — think Janson Media’s internet-TV platform, BrainCert’s virtual classroom, or ProVideoMeeting — a single-server cron falls over the first time a node is recycled. RabbitMQ delayed messages give us a cluster-safe scheduling primitive that survives deployments, autoscaling, and partial outages.
This is the condensed version of what we teach engineers joining our backend team: how to implement RabbitMQ delayed messages every way that still works in 2026, when each approach earns its complexity, and when the honest answer is “use something else.” Every version number, argument, and price here is checked against the RabbitMQ 4.3 and 4.4 releases and the official docs (last verified October 27, 2026), not copied from a 2019 tutorial.
Stuck on retry loops or head-of-queue blocking?
Fora Soft engineers have debugged delayed-message pipelines for video, fintech, and telehealth products since 2005. Bring us the error logs and we’ll sketch a fix in 30 minutes.
When you actually need delayed messages
Before you add a broker feature to your stack, check the job. Delayed messages earn their keep in four patterns we hit constantly in custom software products:
1. Retry with back-off. A webhook, payment capture, or third-party API call fails with a 5xx. Republish the job after 30 seconds, then 2 minutes, then 10 minutes before giving up. Losing a charge to a transient timeout is not acceptable.
2. Time-bound reminders. An SMS 10 minutes before class, an email 24 hours before renewal, a nudge when a cart sits idle for 20 minutes. These are the growth-loop triggers on e‑learning and OTT products.
3. Deferred work inside a pipeline. A user uploads a 2 GB video. You ack the upload instantly, then fire a delayed job that hands the file to an ffmpeg worker 15 seconds later — long enough for object-storage consistency to settle (see how the file is turned into playable renditions in our video encoding primer).
4. Cleanup and housekeeping. Expire OTP codes, delete orphan upload folders, invalidate caches, prune guest sessions. Cheaper and safer than a global cron racing across a cluster.
If your problem looks like any of those — and especially if it must survive a node restart — RabbitMQ delayed messages fit. If the delay is weeks long, calendar-deterministic, or part of a multi-step orchestration, skip to the alternatives.
The four approaches at a glance
How do you delay a message in RabbitMQ? On RabbitMQ 4.4+, publish to a quorum queue with an x-opt-delivery-time header set to a future Unix timestamp in milliseconds. On 4.3, use quorum-queue delayed retries for back-offs and TTL + Dead Letter Exchange for fixed delays. On 4.2 and older, use TTL + DLX or the delayed-message-exchange plugin.
As of October 2026, four mechanisms cover almost every real use case, and which one you pick depends on your RabbitMQ version, because the ground shifted twice: in 4.3 (April 2026) and again in 4.4 (October 2026).
Pattern A — TTL + Dead Letter Exchange (DLX). Publish to a “waiting room” queue where messages carry a time-to-live. When the TTL expires, RabbitMQ dead-letters the message into your real processing queue. Works on any RabbitMQ, no plugin, survives clustering with quorum queues. The sharp edge: FIFO order means a short-TTL message can wait behind a long-TTL one.
Pattern B — the x-delayed-message plugin. Declare an exchange of type x-delayed-message and set an x-delay header per publish. Per-message delays, no head-of-queue blocking. The catch in 2026: the official plugin is archived, so this path survives only through the CloudAMQP fork (4.3.3+ or 4.2.x), and each delayed message still lives as one unreplicated copy.
Pattern C — quorum-queue native delayed retries (4.3+). For retries, the best option. The queue holds a returned message aside internally and redelivers it after a linear back-off. No plugin, no DLX, Raft-replicated. Bounded to retry-style delays, not arbitrary per-message scheduling.
Pattern D — quorum-queue native delayed messages (4.4+). The newest option. Set x-opt-delivery-time on publish; the quorum queue stores and replicates the message at once and hides it from consumers until that time. Per-message timers without a plugin, released by due time, Raft-replicated. Brand new, so capacity at scale is not yet field-proven.
Reach for TTL + DLX when: every message in a queue shares the same delay (retry buckets), or you need strict durability across a clustered, quorum-replicated deployment on any RabbitMQ version.
Reach for the plugin (fork) when: each message needs its own delay (scheduled reminders, per-user timers), you can’t move to RabbitMQ 4.4 yet, and you accept a soft ceiling near 100k in-flight delays with failover handled at the app layer.
Reach for quorum native retries when: you’re on RabbitMQ 4.3+ and the delay is a processing retry with back-off. It’s durable, needs no extra topology, and there’s nothing to rip out later.
Reach for native delayed messages when: you’re on RabbitMQ 4.4+ and each message needs its own release time (reminders, per-user timers, a webhook retry that must honor Retry-After). Replicated like any quorum-queue message, no plugin to babysit.
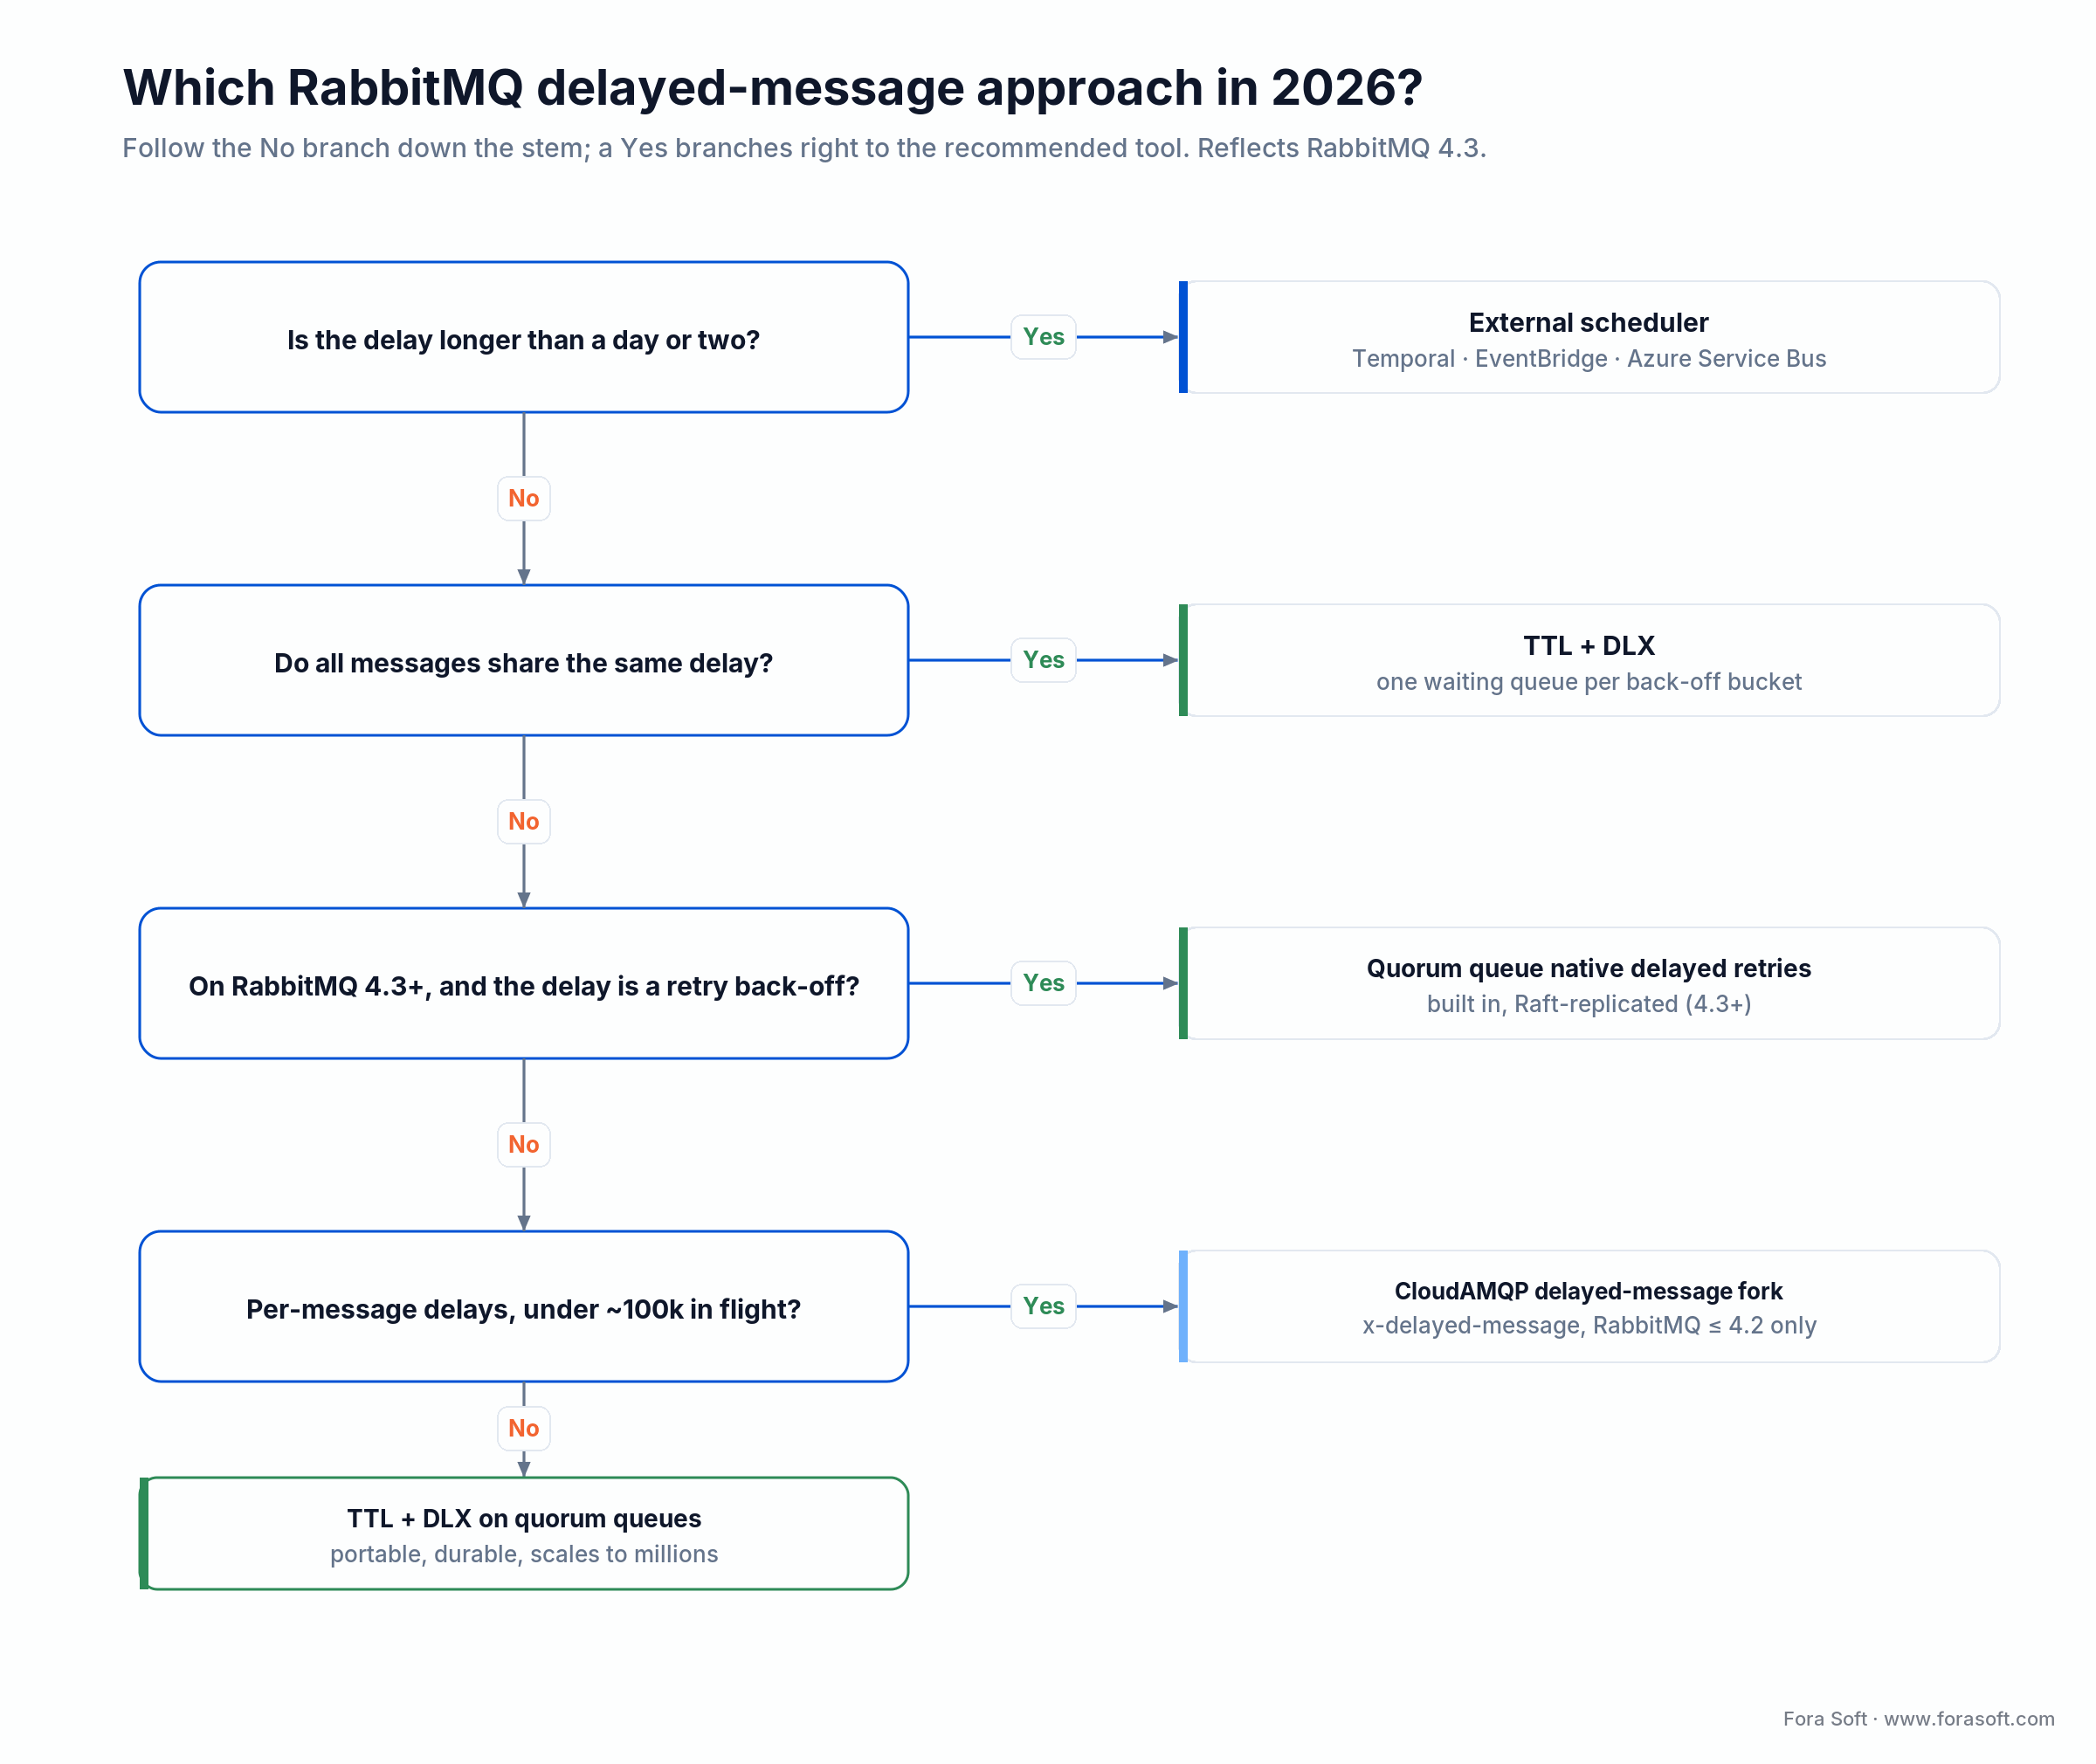
Figure 1. Follow the No branch down the stem; each Yes points to the mechanism that fits, updated for RabbitMQ 4.3. On 4.4+, the per-message branch can use native delayed messages instead of the fork.
Comparison matrix: which approach wins
| Dimension | TTL + DLX | x-delayed-message plugin | Quorum retry (4.3+) | Native delayed (4.4+) |
|---|---|---|---|---|
| Per-message delay | Same TTL per queue (use buckets) | Yes, via x-delay header |
Linear back-off; per-message via AMQP 1.0 | Yes, absolute x-opt-delivery-time |
| Head-of-queue blocking | Yes — short-TTL waits behind long-TTL | No — released on due time | No — held aside internally | No — released at delivery time |
| Cluster replication | Yes, on quorum queues (Raft) | No — node-local scheduler, single copy | Yes — Raft-replicated | Yes — Raft-replicated |
| Practical capacity per node | Millions, disk-bound | ~100k delayed (soft cap) | Millions | Not published yet; load-test |
| Typical delay range | Seconds to hours | Seconds to hours (a day or two max) | Seconds to minutes (retries) | Seconds to hours; long horizons unproven |
| Maintained in 2026? | Yes — core RabbitMQ | Upstream archived; CloudAMQP fork runs on 4.3.3+ | Yes — native since 4.3 | Yes — core since 4.4 (Oct 2026) |
| Plugin required | No | Yes (community fork) | No (native in 4.3+) | No (native in 4.4+) |
Pattern A: TTL + Dead Letter Exchange
The idea: publish to an exchange whose bound queue does no real work, only holds messages for their TTL. When the TTL fires, RabbitMQ dead-letters the message into a second exchange where your consumers live. It’s the one pattern that runs unchanged on every RabbitMQ version, which is exactly why we still reach for it first on portable code.
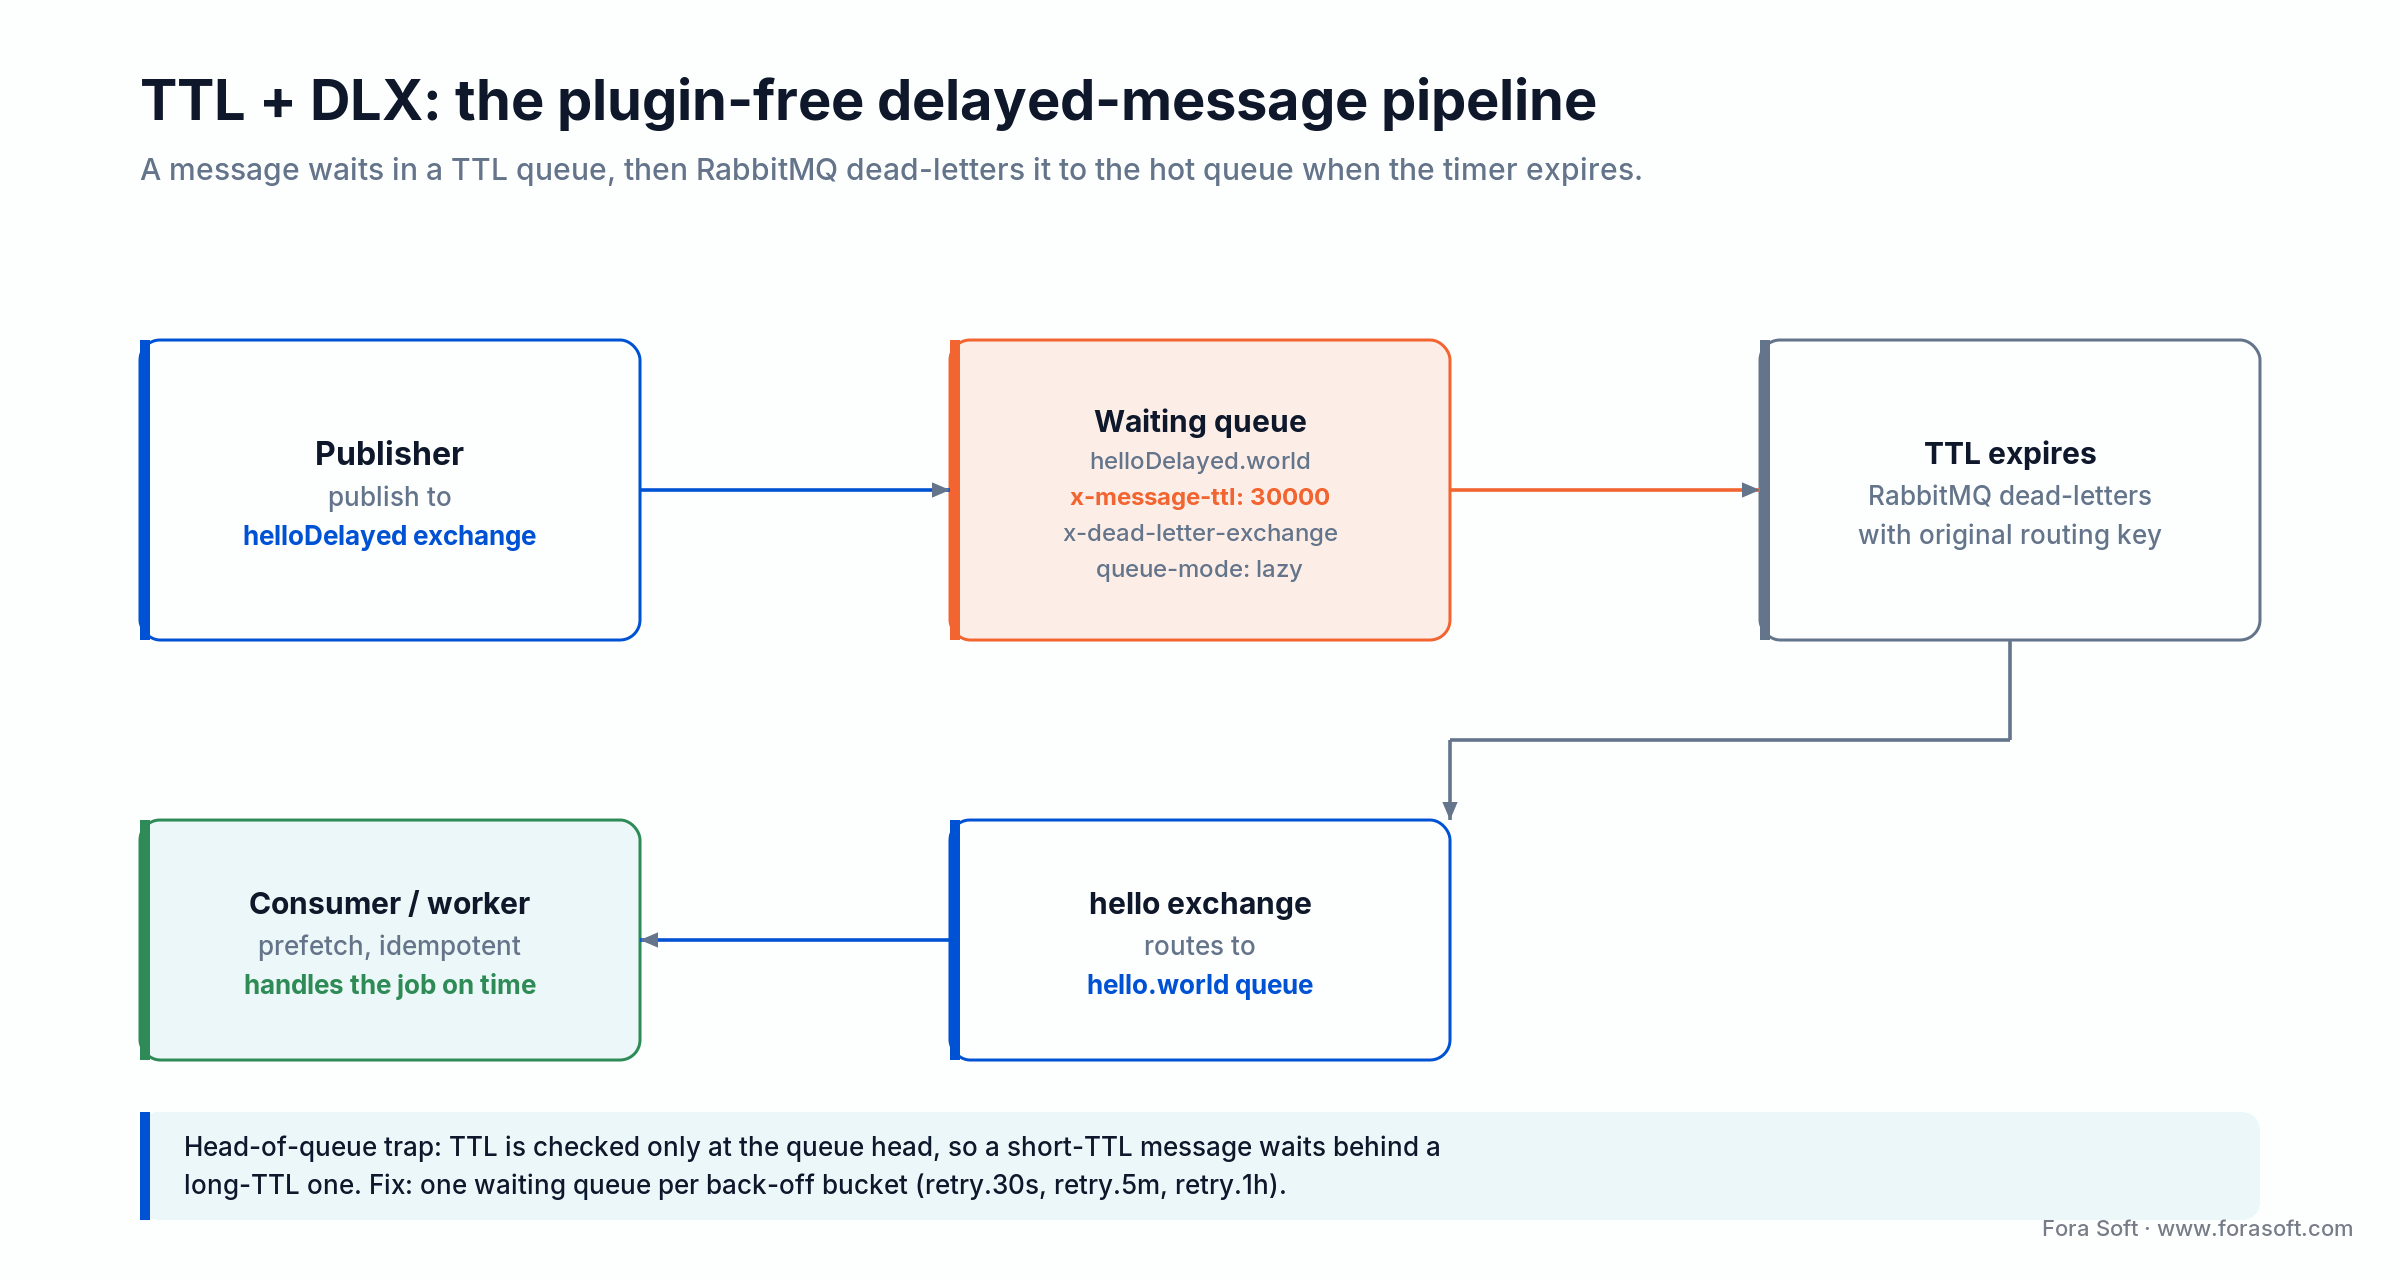
Figure 2. The waiting queue holds the message for its TTL, then RabbitMQ moves it to the hot queue with the original routing key.
Step 1. Declare two exchanges
One is the “hot” exchange your workers subscribe to; the other is the delay waiting room.
// broker/const/exchanges.ts
export const HELLO_EXCHANGE = Object.freeze({
  name: 'hello',
  type: 'direct',
  options: { durable: true },
  queues: {},
});

export const HELLO_DELAYED_EXCHANGE = Object.freeze({
  name: 'helloDelayed',
  type: 'direct',
  options: { durable: true },
  queues: {},
});
Step 2. Bind one queue to each exchange
Keep the binding key identical. The delayed queue’s only job is to hold messages until TTL expires, then hand them off.
// HELLO_EXCHANGE queues
queues: {
  WORLD: {
    name: 'hello.world',          // consumers subscribe here
    binding: 'hello.world',
    options: { durable: true, arguments: { 'x-queue-type': 'quorum' } },
  },
},

// HELLO_DELAYED_EXCHANGE queues
queues: {
  WORLD: {
    name: 'helloDelayed.world',
    binding: 'hello.world',
    options: {
      durable: true,
      arguments: {
        'x-queue-type': 'quorum',                 // Raft-replicated, survives failover
        'x-dead-letter-exchange': HELLO_EXCHANGE.name,
      },
    },
  },
},
The x-dead-letter-exchange argument is the glue: when a message in helloDelayed.world expires, RabbitMQ republishes it to hello with its original routing key. On RabbitMQ 4.x we declare both as quorum queues so the waiting room is replicated — the classic lazy mode is gone, and quorum queues already page to disk.
Step 3. Publish to the delayed exchange with an expiration
// broker/hello/publisher.ts
export const publishHelloDelayedWorld = createPublisher({
  exchangeName: HELLO_DELAYED_EXCHANGE.name,
  queue: HELLO_DELAYED_EXCHANGE.queues.WORLD,
  expirationInMs: 30_000,   // 30 seconds
});
Step 4. Consume the hot queue as normal
// broker/hello/consumer.ts
export const initHelloExchange = () => Promise.all([
  createConsumer(
    { queueName: HELLO_EXCHANGE.queues.WORLD.name, prefetch: 50, log: true },
    controller.consumeHelloWorld,
  ),
]);

// broker/hello/controller.ts
export const consumeHelloWorld: IBrokerHandler = async ({ payload }) => {
  const result = await world({ name: payload.name });
  logger.info(result.message);
  // Republish for a recurring job:
  // await publishHelloDelayedWorld({ name: payload.name });
};
Republishing from inside the consumer is how we implement “fire every 5 minutes” without a cron. The loop survives node restarts because the message lives in a durable, replicated queue the whole time.
The head-of-queue trap
RabbitMQ processes a queue in strict FIFO order, and TTL is evaluated only when a message reaches the head. That means this sequence misbehaves:
1. Publish message A with TTL = 1 hour. It sits at the head of the delayed queue.
2. Publish message B with TTL = 1 minute, a second later.
3. After 1 minute, B is due — but RabbitMQ won’t dead-letter it until A expires an hour later. B lands ~59 minutes late.
This is the single most common reason teams rip out their TTL+DLX setup. Two clean fixes:
Fix A — one queue per back-off bucket. Create a delayed queue for each TTL (retry.5s, retry.30s, retry.5m, retry.1h). Every message in a queue shares the same TTL, so nothing blocks. This is the standard exponential-back-off pattern.
Fix B — use per-message delays. On 4.3+, quorum retries release by computed delay, not arrival order; on 4.2 and earlier, the plugin fork schedules per message. Either way, order is by due time, so the trap disappears.
Pattern B: the x-delayed-message plugin
Read this before you build on it: Team RabbitMQ archived the rabbitmq_delayed_message_exchange plugin. The README opens with “This Project is No Longer Maintained.” It was built on Mnesia, and Mnesia was removed entirely in RabbitMQ 4.3. The upstream build will not load on 4.3+, and its official Team RabbitMQ repository is archived. The community-maintained CloudAMQP fork kept the exchange alive: it replaced Mnesia with Leveled, a node-local LSM-tree store, and its current release requires RabbitMQ 4.3.3 or later (CloudAMQP, August 2026). Fork v4.2.6 is the last Mnesia build and the migration bridge for 4.2 clusters.
How to install the delayed message exchange plugin in 2026: grab the .ez that matches your RabbitMQ series from the fork’s releases page, drop it in the plugins directory, then enable it. CloudAMQP enables it for you on paid plans.
# Use the CloudAMQP fork build for your series (4.3.3+, or v4.2.6 on 4.2.x); upstream is archived.
rabbitmq-plugins directories -s          # find the plugins dir
# copy rabbitmq_delayed_message_exchange-*.ez into it, then:
rabbitmq-plugins enable rabbitmq_delayed_message_exchange
Upgrading a 4.2 cluster that still holds delayed messages? Per the fork’s README: install fork v4.2.6 on every node before enabling the khepri_db feature flag, or the Mnesia-stored messages never migrate; then move to RabbitMQ 4.3.3+ with the matching fork release. Never disable the plugin mid-upgrade, and rehearse on a test cluster first.
Declare an exchange of type x-delayed-message and specify the underlying routing via x-delayed-type (direct, topic, fanout).
// broker/const/exchanges.ts
export const HELLO_PLUGIN_DELAYED_EXCHANGE = Object.freeze({
  name: 'helloPluginDelayed',
  type: 'x-delayed-message',
  options: {
    durable: true,
    arguments: { 'x-delayed-type': 'direct' },
  },
  queues: {
    WORLD_PLUGIN_DELAYED: {
      name: 'helloPluginDelayed.world',
      binding: 'helloPluginDelayed.world',
      options: { durable: true },
    },
  },
});
Publish with the x-delay header in milliseconds:
// broker/hello/publisher.ts
export const publishHelloPluginDelayedWorld = createPublisher({
  exchangeName: HELLO_PLUGIN_DELAYED_EXCHANGE.name,
  queue: HELLO_PLUGIN_DELAYED_EXCHANGE.queues.WORLD_PLUGIN_DELAYED,
  delayInMs: 60_000,   // 60 seconds
});

// Under the hood, amqplib publishes with:
// channel.publish('helloPluginDelayed', routingKey, payload, {
//   headers: { 'x-delay': 60000 },
// });
Consumers look identical to any other RabbitMQ consumer. A message with a 1-minute delay published after a 1-hour delay is released first, so the head-of-queue problem is gone. Delivery is timer-based and approximate — don’t expect millisecond precision.
Migrating off the archived delayed-message plugin?
We’ve moved production pipelines from the plugin to quorum retries and TTL+DLX without dropping a message. Walk us through your topology and we’ll map the safe path.
Plugin limits before you ship it
Fork or not, the plugin README is refreshingly honest about where it breaks. Read it before you bet a production pipeline on it.
1. It’s scoped to short delays. Straight from the README: “This plugin was designed for delaying message publishing for a number of seconds, minutes, or hours. A day or two at most.” Counting your delay in days or weeks? Pick a different tool.
2. It’s node-local, not replicated. Delayed messages live as a single copy on the node that received them (Mnesia upstream, Leveled in the fork). They survive a restart, but losing that node — or disabling the plugin on it — loses those messages. The mandatory flag isn’t supported either.
3. Capacity soft-caps near 100k. The README states plainly that the design “doesn’t really fit scenarios with a high number of delayed messages (e.g. 100s of thousands or millions).” In our own load tests, CPU saturated past roughly 100k queued delays on a 4-vCPU node.
4. Disabling the plugin destroys pending messages. The README is blunt: disable it and “all delayed messages that haven’t been delivered will be lost.” Drain first, always.
5. It’s a bridge, not a destination. The upstream plugin has no path past 4.2; the fork carries you to 4.3, but new projects on 4.4 should start on native delayed messages, quorum retries or TTL+DLX. The commercial Tanzu Delayed Queue remains the option for replicated per-message scheduling with enterprise support.
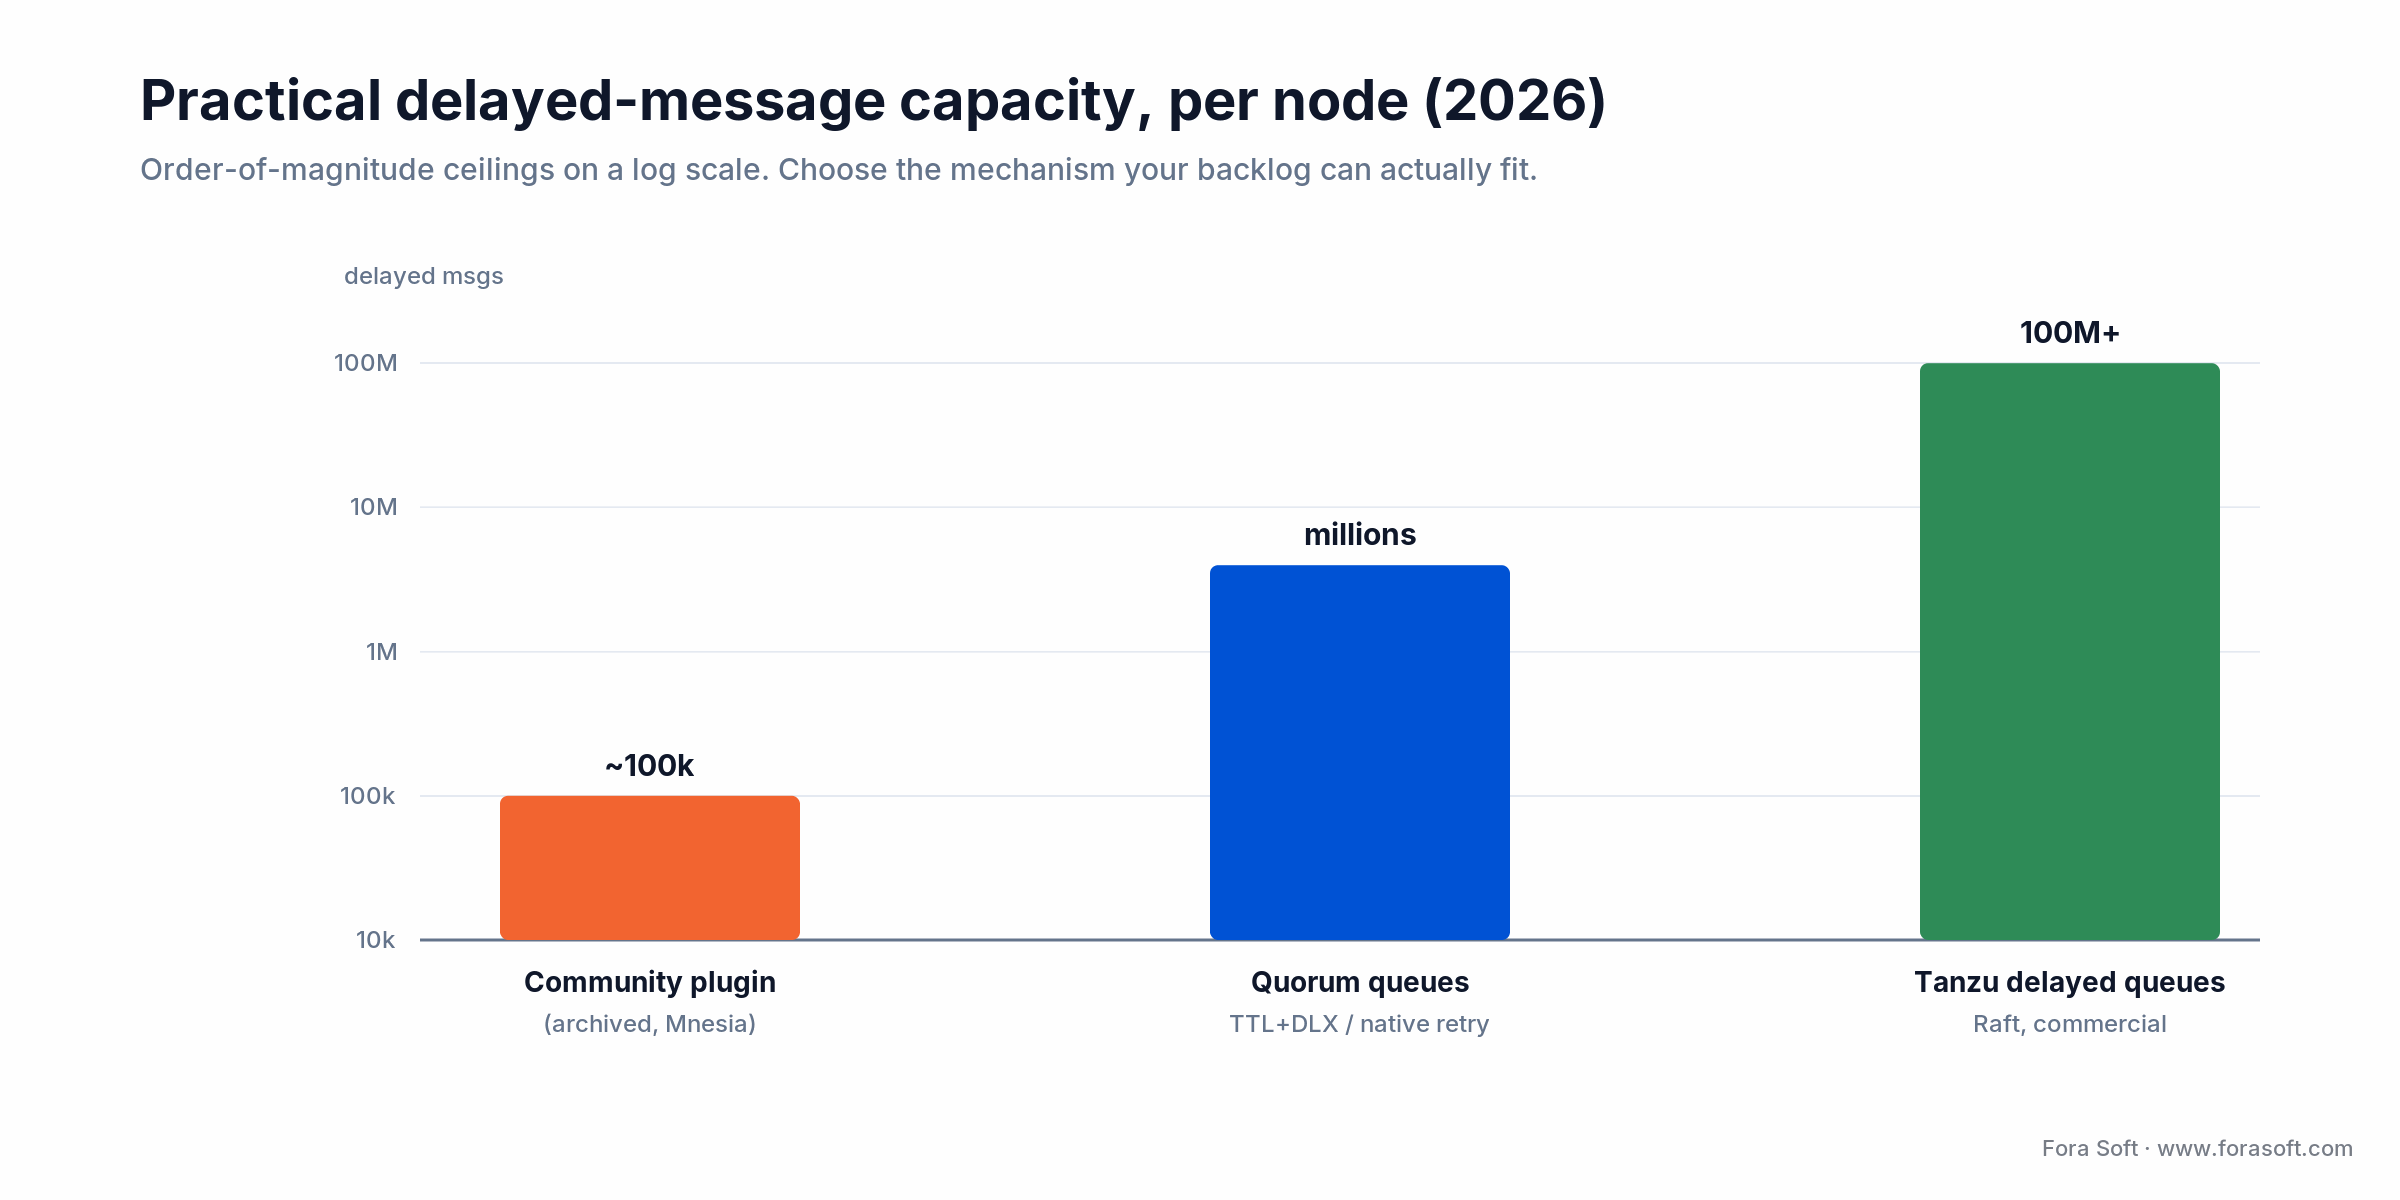
Figure 3. Match the mechanism to the backlog: the plugin tops out near 100k, quorum queues scale to millions, Tanzu Delayed Queues to 100M+.
Quorum queues: native delayed retries
RabbitMQ 4.3, released April 2026, added native delayed retries to quorum queues — and for the most common delayed-message job, retries, it’s now the best answer. Instead of a DLX cycle or a scheduler round-trip, the quorum queue sets a returned message aside internally and makes it available again only after the delay elapses. No message rewrite, no duplication risk, and it’s Raft-replicated across nodes.
You configure it with three queue arguments or an equivalent policy. The delay grows with the delivery count using linear back-off: min(delayed-retry-min × delivery-count, delayed-retry-max).
# RabbitMQ 4.3+: delay only failed deliveries, 30s -> 60s -> 90s -> 120s (capped)
rabbitmqctl set_policy delayed-retry "^orders\." \
  '{"delivery-limit":20,
    "delayed-retry-type":"failed",
    "delayed-retry-min":30000,
    "delayed-retry-max":120000}' \
  --apply-to queues

// Or as queue-declare arguments (amqplib):
await channel.assertQueue('orders.process', {
  durable: true,
  arguments: {
    'x-queue-type': 'quorum',
    'x-delayed-retry-type': 'failed',   // 'all' | 'returned' | 'failed'
    'x-delayed-retry-min': 30000,       // 30s
    'x-delayed-retry-max': 120000,      // cap at 120s
  },
});
// A failed delivery (basic.reject / reject-with-requeue) triggers the back-off.
With min = 30s and max = 120s, a message that keeps failing is redelivered after 30s, 60s, 90s, then 120s on every attempt after that. Need exact timing for one message — say a tenant hit an HTTP 429 with a Retry-After header? A consumer on AMQP 1.0 can override the computed delay with the x-opt-delivery-time annotation, so one slow tenant doesn’t stall the rest.
One more 4.3 win worth stealing: quorum queues now track acquired-count separately from delivery-count, so returns that aren’t genuine failures no longer push a message toward the poison-message delivery-limit (default 20). Retry loops stop eating your dead-letter budget.
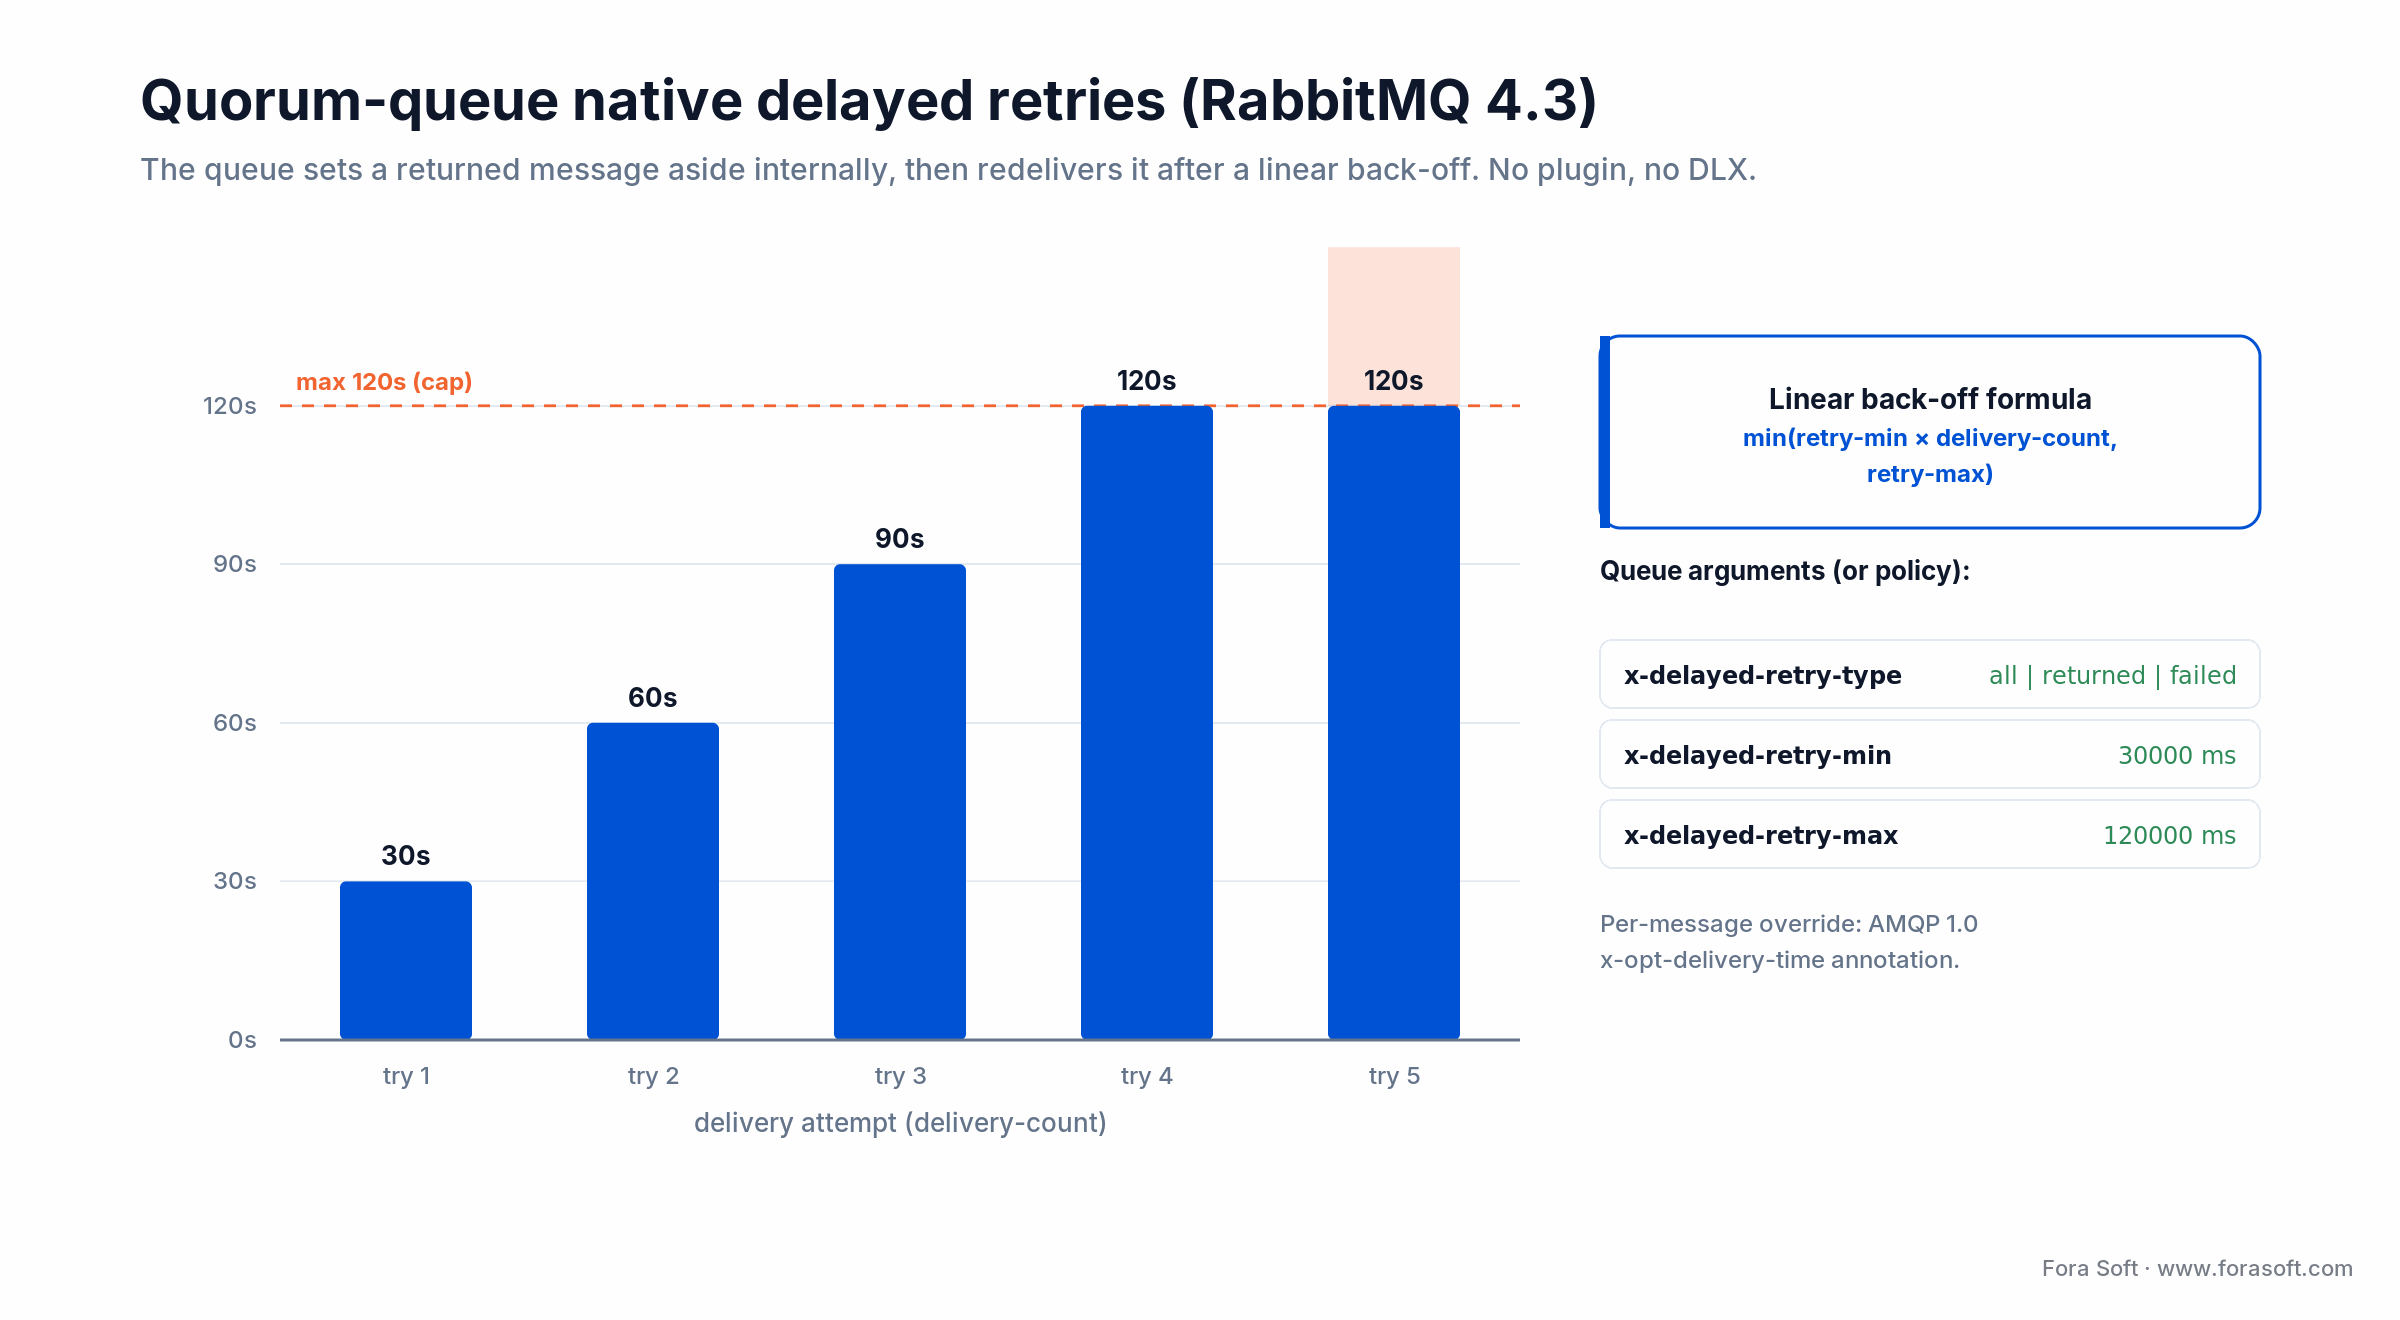
Figure 4. Linear back-off in action: each failed delivery waits longer, capped at delayed-retry-max.
The trade-off: quorum retries are for retries. The delay is a back-off tied to delivery count, not an arbitrary “fire this at 3pm” timer. For true per-message scheduling, use native delayed messages on 4.4 (next section), the plugin fork on 4.3, or an external scheduler. Managed clouds have caught up on retries: CloudAMQP offered 4.3 from August 2026, and Amazon MQ added RabbitMQ 4.3 on September 10, 2026 (AWS What’s New), with delayed retries manageable through policies on m7g brokers. Check which version your provider runs before you design around a feature.
Native delayed messages in RabbitMQ 4.4
Does RabbitMQ support delayed messages natively? Yes, since RabbitMQ 4.4 (released October 20, 2026). Any quorum queue accepts a message carrying x-opt-delivery-time, an absolute Unix timestamp in milliseconds, and keeps it invisible to consumers until that time. No plugin, no special exchange type, no queue argument (RabbitMQ 4.4 highlights).
This closes the gap the archived plugin left. Routing happens at publish time, so the message is replicated and confirmed immediately; there is no internal re-publish later, and therefore no second chance for a message to get lost on the way. Over AMQP 1.0 the value is a message annotation; per the 4.4.0 release notes, AMQP 0-9-1 clients set it as a long header.
// RabbitMQ 4.4+: per-message delay on a quorum queue, no plugin (amqplib, AMQP 0-9-1)
await channel.assertQueue('reminders', {
  durable: true,
  arguments: { 'x-queue-type': 'quorum' },
});

const deliverAt = Date.now() + 24 * 60 * 60 * 1000;   // absolute time, Unix ms
channel.sendToQueue('reminders', Buffer.from(JSON.stringify(job)), {
  persistent: true,
  messageId: job.eventId,                              // keep consumers idempotent
  headers: { 'x-opt-delivery-time': { '!': 'long', value: deliverAt } },
});

// AMQP 1.0 (RabbitMQ Java AMQP 1.0 client), same idea:
// publisher.message(body).annotation("x-opt-delivery-time", deliverAt);
What to know before you move timers onto it:
1. Quorum queues only. The feature lives in quorum queues; keep classic queues and streams out of the design.
2. Delayed messages count toward the queue’s length limit. If you cap a queue with x-max-length, a pile of future reminders can push out live work. Give delayed traffic its own queue.
3. You can see them. The Management UI shows a “Delayed” column, so the backlog of pending timers is observable without a plugin-specific metric.
4. Capacity is not published yet. The 4.4 announcement gives no ceiling for pending delayed messages. Load-test with your real backlog before you move 100k+ timers, and keep days-ahead schedules in a database until the numbers are in.
5. Consumers can defer, too. 4.4 also adds deferred messages: a consumer parks a message with a token of up to 256 bytes and fetches it later, with x-opt-delivery-time as the deadline that makes it available again if nobody retrieves it.
Upgrade planning: RabbitMQ lists community support for 4.3 until January 31, 2027 and for 4.4 until July 31, 2027 (release information, checked October 2026). If you are on 4.2 with the plugin, the sensible path is 4.2 → fork v4.2.6 → 4.3 → 4.4, then move per-message timers from the exchange to native delayed messages queue by queue.
When RabbitMQ is the wrong tool
RabbitMQ delayed messages cover maybe 70% of the scheduling patterns we see. The rest belong to tools purpose-built for their niche. Choosing between them for an existing backend is a standard question in our independent architecture review.
1. Temporal (or Cadence). A workflow engine with first-class timers, retries, and compensation. Best for multi-step business processes that pause for days or weeks — onboarding, refunds, complex orchestration. Self-hosted Temporal starts around a few hundred dollars a month in infra; Temporal Cloud is per-action.
2. AWS SQS delay queues. Native, fully managed, but capped at a 15-minute delay per message (DelaySeconds 0–900). For anything longer, pair SQS with EventBridge Scheduler, which has no time limit. No cluster to run.
3. Azure Service Bus scheduled enqueue. Built-in, no plugin, supports delays out to days and weeks via ScheduledEnqueueTime (ScheduledEnqueueTimeUtc in the legacy SDK). The natural pick if you’re already in Azure.
4. Google Cloud Tasks. An HTTP task queue with arbitrary delay and automatic retry. Excellent for triggering serverless endpoints on a timer.
5. Redis ZSET + worker. A sorted set keyed by due-time, plus a worker that pops ready entries every second. Sidekiq, BullMQ, and Celery-beat all do this. Fast and simple — you own the operational burden.
6. Tanzu RabbitMQ Delayed Queues. The commercial successor to the archived plugin, supporting x-opt-delivery-time and x-opt-delivery-delay: Raft-replicated, standard AMQP 1.0 annotations, flat memory whether you schedule a thousand or a million, browse-and-purge, cross-DC standby. The answer when you need per-message scheduling at extreme scale with vendor support; on open-source 4.4, native delayed messages now cover the everyday cases.
Reach for an external scheduler when: the delay is days-to-weeks, calendar-based, or part of a workflow with human-approval stops. RabbitMQ is for “now + X within a few hours,” not “every Tuesday at 09:00 UTC.”
Hosting and pricing snapshot (2026)
A rough ballpark for a production-grade delayed-message pipeline handling a few hundred thousand events per day. Treat these as order-of-magnitude starting points (prices checked October 2026); always confirm current rates with the provider.
| Option | Monthly starting point | Delayed support | Best for |
|---|---|---|---|
| Self-hosted (Hetzner, other bare metal or VMs) | Infra only; recheck rates (Hetzner raised prices in 2026) | Everything open-source: TTL+DLX, quorum retries, native delayed (4.4) | EU teams comfortable running ops |
| CloudAMQP | $19 shared; dedicated from $50; 3-node cluster from $297 | TTL+DLX, plugin fork (4.3), quorum retries | Fast start, maintains the fork |
| Amazon MQ for RabbitMQ | ~$610 for a 3-node mq.m7g.large cluster ($0.2734/h per node, us-east-1) | TTL+DLX, quorum retries (4.3 since Sep 2026) | All-AWS architectures, compliance |
| Azure Service Bus (Premium) | Billed hourly per messaging unit; use the Azure calculator | Native scheduled enqueue | Azure shops that need SLAs |
| Tanzu RabbitMQ (Broadcom) | Enterprise quote | Raft delayed queues (100M+) | Regulated enterprise at scale |
Mini case: delayed messages in OTT
We used RabbitMQ delayed messages on Janson Media’s internet-TV platform to replace a patchwork of cron jobs and one-off Node scripts. Three jobs mattered: reminding users 24 hours before a rental period ended, pushing payment-completion notifications to the front-end socket channel, and handing newly uploaded videos to the transcoding workers.
The old setup ran on a single Node server with node-schedule. When we added a second app node behind a load balancer, timers started firing twice or not at all depending on which node took the restart. We refactored every schedule into a delayed exchange with an idempotent consumer keyed on the event ID. Restart safety went from “maybe” to deterministic, and duplicate notifications dropped to zero over a 30-day window.
Because the plugin’s per-message scheduling had a capacity ceiling, we sharded schedules across two smaller exchanges (reminders vs webhooks) and ran TTL+DLX for the highest-volume webhook-retry queues. Total infra footprint: one 3-node quorum cluster, roughly $180 per month on CloudAMQP at the time. On 4.3+, those retry queues collapse into native quorum retries, and on 4.4 the per-message reminders can move to native delayed messages — less topology to babysit. If you’re building that kind of product, our OTT and IPTV platform development team designs this event backbone together with the video stack. Want a similar assessment for your stack? Book a 30-min architecture review.
Idempotency is not optional
RabbitMQ guarantees at-least-once delivery. Delayed pipelines compound this: retries, republishes, and node failovers can all deliver a message more than once. Every consumer for a delayed job must be idempotent, or you’ll send the same user two reminder emails the first time you bounce a node.
The pattern we use on every project:
- Every message carries a stable
event_id— a UUID or a natural key likereminder:rental:123:24h. - The consumer writes a processed-event row in Postgres inside the same transaction as the side effect.
- A unique constraint on
event_idmeans the second delivery no-ops cleanly. - For non-transactional side effects like sending an email, gate on a
sent_atcolumn plus a short-lived Redis lock.
Monitoring: three metrics that matter
Scrape Prometheus metrics off the RabbitMQ management plugin every 15–30 seconds. Three alerts cover the failure modes we see in production.
Quality KPI — delivery latency. Track publish-to-consume p99 per delayed queue. If a 30-second delay is delivering at p99 = 2 minutes, the scheduler is backlogged. Alert when p99 > 3× the configured delay.
Business KPI — DLQ depth. rabbitmq_queue_messages{queue=~".*dlq"}. Every message here is a job your consumer gave up on. Any non-zero value should page during business hours; a ramp-up signals an upstream outage.
Reliability KPI — redeliver rate. rate(rabbitmq_queue_messages_redelivered_total[5m]). A sustained non-zero value is the classic retry-loop fingerprint: a poison message re-queued forever. On 4.3, pair it with the delivery-limit so poison messages dead-letter instead of looping.
A decision framework in five questions
1. How long is the delay? Under a few hours → RabbitMQ is fine. Hours to a day or two → native delayed messages (4.4+), the plugin fork (4.3 and older) or Azure Service Bus. Days or weeks → Temporal, EventBridge Scheduler, or Google Cloud Tasks.
2. Is the delay a retry back-off? Yes, and you’re on 4.3+ → quorum native retries. Yes, on older RabbitMQ → TTL+DLX with one queue per bucket.
3. Do all messages share the same delay? Yes → TTL+DLX. No, each is different → native delayed messages on 4.4+; on older versions, the plugin fork or an external scheduler.
4. What is the cost of a dropped message? “Annoying” → node-local plugin is acceptable. “Financial” or “compliance” → quorum queues or Raft-replicated delayed queues, with end-to-end auditing.
5. Are you already in a managed cloud? Deep in AWS → try SQS delay + EventBridge first. In Azure → Service Bus scheduled enqueue is native. RabbitMQ shines when you need the broker for pub/sub, RPC, or fan-out anyway.
Five pitfalls we keep finding
1. One TTL+DLX queue for every back-off tier. Short-TTL messages block behind long-TTL ones. Fix: one queue per tier, or move retries to quorum native retries on 4.3+.
2. Starting a new build on the archived plugin. Nobody maintains upstream, and even the CloudAMQP fork keeps one unreplicated copy per message. On 4.4, start with native delayed messages; use the fork only as a bridge on 4.2–4.3 and budget the move.
3. Missing idempotency. Every retry-heavy delayed pipeline needs a unique event_id and a dedup table. Add it on day one; bolting it on after a duplicate-notification incident is painful.
4. Scheduling days ahead through a broker. Memory grows linearly with pending delayed messages. Long-horizon schedules belong in Postgres or Temporal; pull them into RabbitMQ only when they’re due within a few hours.
5. Silent DLQ backlog. We’ve inherited codebases where the DLQ hadn’t been drained in a year. Always consume your DLQ: archive to S3, alert on depth, and keep a replay tool ready. If a retry loop is already burning CPU in production, our software troubleshooting and optimization engineers profile the broker and consumers and fix the hot path.
When not to use delayed messages
Three cases where reaching for RabbitMQ delayed messages is over-engineering:
1. You already have a database and under ~1k delays per day. A Postgres table with a due_at column and a worker polling every 5 seconds is simple, auditable, and enough.
2. Schedules are calendar-based and known in advance. Use a Kubernetes CronJob or AWS EventBridge cron. RabbitMQ is for “now + X,” not “every Tuesday at 09:00 UTC.”
3. The workflow has many steps that pause for hours or days. Reach for Temporal or a workflow engine with first-class timers, retries, and human-approval stops. RabbitMQ can approximate it, but you’ll rebuild half a workflow engine badly.
Need a partner who has shipped this in production?
Fora Soft has built event-driven backends for OTT, e‑learning, and fintech since 2005. We’ll audit your current pipeline or design a new one, matched to your RabbitMQ version.
FAQ
What is the difference between TTL + DLX and the x-delayed-message plugin?
TTL + DLX is a pattern built on native RabbitMQ primitives: you park a message in a waiting queue with a time-to-live, and when it expires RabbitMQ dead-letters it into your real queue. The plugin added an x-delayed-message exchange type that held each message in an internal scheduler and released it per-message at the due time. TTL + DLX is simpler operationally, scales to millions, and runs on every RabbitMQ version; the plugin was more ergonomic for per-message delays, but the upstream build is archived and only the CloudAMQP fork runs on 4.3+. On RabbitMQ 4.4, native delayed messages give you per-message delays without either.
Is the RabbitMQ delayed message plugin still supported in 2026?
Not by Team RabbitMQ. The upstream rabbitmq_delayed_message_exchange repository is archived because it depended on Mnesia, which RabbitMQ 4.3 removed. CloudAMQP maintains a fork that swapped Mnesia for a node-local Leveled store and runs on RabbitMQ 4.3.3+ (August 2026). For new work on 4.4, use native delayed messages (x-opt-delivery-time) or quorum-queue delayed retries.
Does RabbitMQ support delayed messages natively without a plugin?
Yes, from RabbitMQ 4.4 (October 20, 2026). Publish to a quorum queue with x-opt-delivery-time set to a future Unix timestamp in milliseconds (an AMQP 1.0 annotation, or a long header on AMQP 0-9-1); the queue replicates the message immediately and releases it to consumers at that time. On 4.3 the native option is limited to delayed retries.
How do I install the rabbitmq_delayed_message_exchange plugin?
Download the .ez build matching your RabbitMQ series from the CloudAMQP fork’s releases (the upstream repo is archived), copy it into the directory shown by rabbitmq-plugins directories -s, and run rabbitmq-plugins enable rabbitmq_delayed_message_exchange. Current fork builds need RabbitMQ 4.3.3+; on 4.2.x use fork v4.2.6. On 4.4 you may not need the plugin at all.
How do quorum-queue native delayed retries work?
In RabbitMQ 4.3+, a quorum queue can hold a returned message aside internally and redeliver it after a delay set by x-delayed-retry-min, x-delayed-retry-max, and x-delayed-retry-type. The delay grows with delivery count using linear back-off: min(retry-min × delivery-count, retry-max). It’s Raft-replicated, rewrites nothing, and needs no DLX or plugin — the cleanest path for retry-style delays.
Why are my delayed messages firing late or out of order?
If you use TTL + DLX with one shared queue, you’re hitting the FIFO head-of-queue problem: a short-TTL message behind a long-TTL one must wait for the long one to expire first. Switch to one queue per back-off tier, or use per-message delays (quorum native retries on 4.3+, or the plugin fork on 4.2), which release strictly by due time.
Can RabbitMQ delayed messages schedule days or weeks ahead?
Not reliably yet. The plugin README scopes it to “seconds, minutes, or hours, a day or two at most,” quorum retries are back-offs, not calendar timers, and RabbitMQ has not published capacity figures for 4.4 native delayed messages. For longer horizons use Temporal, AWS EventBridge Scheduler, Azure Service Bus scheduled enqueue, or a database-backed poller that pushes jobs into RabbitMQ when they are due within the next few hours.
Will I lose delayed messages if a RabbitMQ node restarts?
With TTL + DLX, quorum native retries, or 4.4 native delayed messages on quorum queues, messages are Raft-replicated and survive restarts and failovers. The plugin (upstream and the CloudAMQP fork) keeps each delayed message as a single node-local copy, so a node failure before the due time could lose the message — one reason it’s no longer the recommended path. In 2026, quorum-backed options are the durable choice.
Do I still need idempotent consumers with delayed messages?
Yes, more than with regular queues. RabbitMQ delivers at-least-once, and delayed pipelines add retries, republishes, and failovers. Every consumer should be idempotent, keyed on a stable event_id, and guarded by a unique constraint or a Redis lock. Otherwise one node restart can double-send a batch of reminders.
Should I still use RabbitMQ for delayed messages given Temporal exists?
Yes, for retries and short-horizon reminders on teams already running RabbitMQ. Use quorum native retries for back-offs (4.3+), TTL + DLX for same-delay pipelines on any version, and Temporal or a workflow engine for anything multi-step or longer than a few hours. Layering them is normal — match each scheduling pattern to the tool with the right durability and latency.
What to read next
OTT & STREAMING
How to Develop an OTT Platform Like Netflix
See how delayed jobs fit into a full Netflix-style streaming pipeline.
E-LEARNING
How to Implement Video Streaming in an E‑learning App
Event-driven flows we use alongside RabbitMQ for class reminders and uploads.
ENTERPRISE
How to Develop a Corporate Training Video Platform
Where scheduled notifications and webhook retries save LMS rollouts.
HIRING
How to Hire LiveKit Developers
Building a backend team that owns messaging, signaling, and delay pipelines.
Ready to ship reliable delayed messages?
RabbitMQ gives you four ways to implement delayed messages, and in 2026 the right pick depends on your version. On 4.4+, native delayed messages on quorum queues handle per-message timers without a plugin. TTL + DLX is the portable, cluster-safe workhorse for same-delay pipelines. Quorum-queue native retries (4.3+) are the cleanest option for retry back-offs, with nothing to rip out later. The old x-delayed-message plugin is archived upstream — alive only as the CloudAMQP fork for 4.2–4.3, and replaced at scale by Tanzu’s Raft-based delayed queues.
The real work is matching each slice of your workload to the right tool, adding idempotency and monitoring on day one, and keeping long-horizon scheduling out of the broker. If you want a second pair of eyes on your design — or a team that can implement it fast — Fora Soft has done this for video, e‑learning, fintech, and telehealth products since 2005.
The handbook · 7 volumes
Fora Soft Video Engineering Handbook
Delayed messages keep renewal emails, webhook retries and deferred media jobs on time, and the media jobs themselves sit on a deeper stack. We wrote a seven-volume handbook on that stack, from encoding and delivery to audio and AI. Backend engineers on video platforms can start with Volume 3 on delivery and streaming economics, then Volume 1 on transcoding and Volume 2 on packaging. Written by Nikolay Sapunov, CEO at Fora Soft.
Browse the handbook on Amazon →7 volumes · 9,000+ pages · Kindle & paperback
Talk to an engineer who has shipped delayed pipelines?
Bring us your queue diagram and failure modes — we’ll point at the three highest-impact fixes in 30 minutes. Agent Engineering-accelerated, no sales fluff.

