
Software estimation techniques are the methods a team uses to forecast the effort a piece of software will take: analogous estimation, top-down and bottom-up decomposition, parametric models such as COCOMO II fed by Function Point size counts, Planning Poker and three-point PERT. The short answer: use analogy for a first range at the idea stage, a bottom-up breakdown with three-point (PERT) bands once a spec exists, and always stack two methods to cross-check each other. This guide is about choosing and running those techniques; if what you need is the money side, our software development cost estimation playbook turns effort into a priced, defensible range, and our guide to software development time estimation turns it into a calendar date. Estimation is also the most commercially charged conversation you'll have with a vendor. Quote too low and the project limps to the finish line with surprise change orders. Quote too high and you lose the deal to a competitor who will quote too low. This guide is how Fora Soft, with 250+ shipped projects since 2005, actually estimates modern software work, what we refuse to estimate, and how you can tell a credible estimate from a marketing document.
Not a technical reader? Here's the 60-second version.
Any honest vendor will give you a range, not a single number. The range narrows as you move from an idea to a detailed technical design — that's the Cone of Uncertainty. If your vendor promises a precise fixed price from a one-page brief, they've either padded the number heavily or they will change-order you later. Ask for a paid discovery phase, a line-item breakdown, and written assumptions. Then compare models (fixed price vs time & materials vs capped T&M) against your risk tolerance and scope stability.
Key takeaways
- →Every credible software estimate is a range with documented assumptions, not a single number. The range shrinks from a 0.25×–4× spread at concept to about ±10% once detailed technical design is done.
- →McKinsey and the University of Oxford (2012, 5,400+ IT projects) found large projects run 45% over budget and deliver 56% less value than predicted. The fix starts with scoping and estimation, not with coding faster.
- →Choose your pricing model to match scope stability: fixed price for frozen specs, capped T&M for exploratory builds, pure T&M for long-running platforms.
- →2026 changes the math. AI-assisted coding shifts effort from typing to reviewing, so estimation now has to budget for verification time and model/infra costs, not just developer hours.
- →Refuse vendors who skip discovery. A paid 2–4 week discovery phase typically costs 5–10% of the project and turns an undefined scope into a priced one.
Updated October 2026: four more estimation methods (Wideband Delphi, T-shirt sizing, Function Points, Monte Carlo), the components of an estimate, and 2025–2026 data from METR, DORA, Stack Overflow and the FinOps Foundation on how AI changes estimation.
Why most software estimates are wrong — and why that's usually fixable
The industry loves to blame engineers for missed deadlines, but the data disagrees. McKinsey and Oxford's 2012 study of 5,400+ IT projects found that large programs ran 45% over budget and 7% over schedule while delivering 56% less value than predicted, and traced the damage to four groups of causes: missing business focus, shifting requirements and technical complexity, skill gaps, and execution problems such as unrealistic schedules. Three of the four are settled before anyone writes code. The same research advises analysing a large project’s prospects and scope before it starts — which is exactly what a discovery-first estimate does.
In practice, three specific mechanics keep repeating:
- Probability-free estimates. Humans naturally estimate the "most likely" path and call that the answer. Real schedules are a distribution with a long tail of integrations, dependencies, and rework. If you quote the mode rather than the expected value, you will be late more than half the time — the failure mode we unpack in why developers' time estimates don't always work.
- Frozen scope fiction. Fixed-price contracts assume the spec won't move. It always moves. A vendor who doesn't budget for a change-control process is mis-pricing the risk.
- Hidden non-billables. Onboarding, discovery, DevOps setup, code review, security review, client workshops, retrospectives: somebody pays for these. If they're not in the estimate, they'll either erode the vendor's margin (then come back as change orders) or degrade quality.
Every one of these is fixable with process discipline, and most of the fix happens in discovery — the phase our software product planning and discovery service runs before anyone commits to a number. The rest of this guide shows how Fora Soft handles each of them and how you can audit any vendor's numbers against the same checklist. Book a 30-min estimate review if you'd like us to stress-test a quote you've already received.
What are the components of software estimation?
Software estimation has five components, and a credible estimate states all five: size (how much software: features, stories or function points), effort (person-hours to build it), schedule (calendar time once team size and dependencies are applied), cost (effort times rates, plus cloud, licences and other non-labour items) and confidence (the range and the probability attached to it). Estimation techniques differ mainly in how they get from size to effort; schedule and cost follow from effort, and confidence is what separates an estimate from a guess.
Software project estimation guidelines
- Size first, effort second. Never start from a budget and work backwards to the scope.
- Use two independent techniques (for example analogy and bottom-up) and investigate when they disagree.
- Give a range with a confidence level — a 50% target and a 90% ceiling — never a single number.
- Write the assumptions and exclusions next to the number, so a change in scope has a visible price.
- Let the people who will do the work estimate it, then have a second lead review the breakdown.
- Re-estimate at every stage gate of the Cone of Uncertainty below, not only when something goes wrong.
- Track actuals against estimates and feed them back into your analogy library and parametric models.
The Cone of Uncertainty, 2026 edition
Barry Boehm described it in 1981; Steve McConnell operationalised it in Software Estimation: Demystifying the Black Art; Luiz Laranjeira tightened the math. The claim is simple and hard to argue with: the earlier in a project you estimate, the wider the honest range has to be. At the "initial concept" stage your range is roughly 0.25× to 4× the real cost. By the time detailed technical design is signed off, it's roughly 0.9× to 1.1×.
What does the cone actually look like in numbers?
| Project stage | Honest range | What you can commit to |
|---|---|---|
| Initial idea / one-pager | 0.25×–4× | Feasibility & rough order of magnitude |
| Product vision approved | 0.5×–2× | T&M engagement, capped discovery |
| Requirements specified | 0.67×–1.5× | Capped T&M, phased fixed-price |
| Architecture & UX signed off | 0.8×–1.25× | Milestone-based fixed price |
| Detailed technical design | 0.9×–1.1× | Sprint-level fixed-price commitments |
The 2026 twist: AI-assisted coding narrows the build band a bit (Copilot and similar tools do help ship code faster) but widens the integration and verification band. More generated code means more review time, more subtle bugs around prompt boundaries, and — for anything that calls an LLM at runtime — a whole new line-item for inference cost that's historically been volatile. Estimates that ignore these are yesterday's estimates.
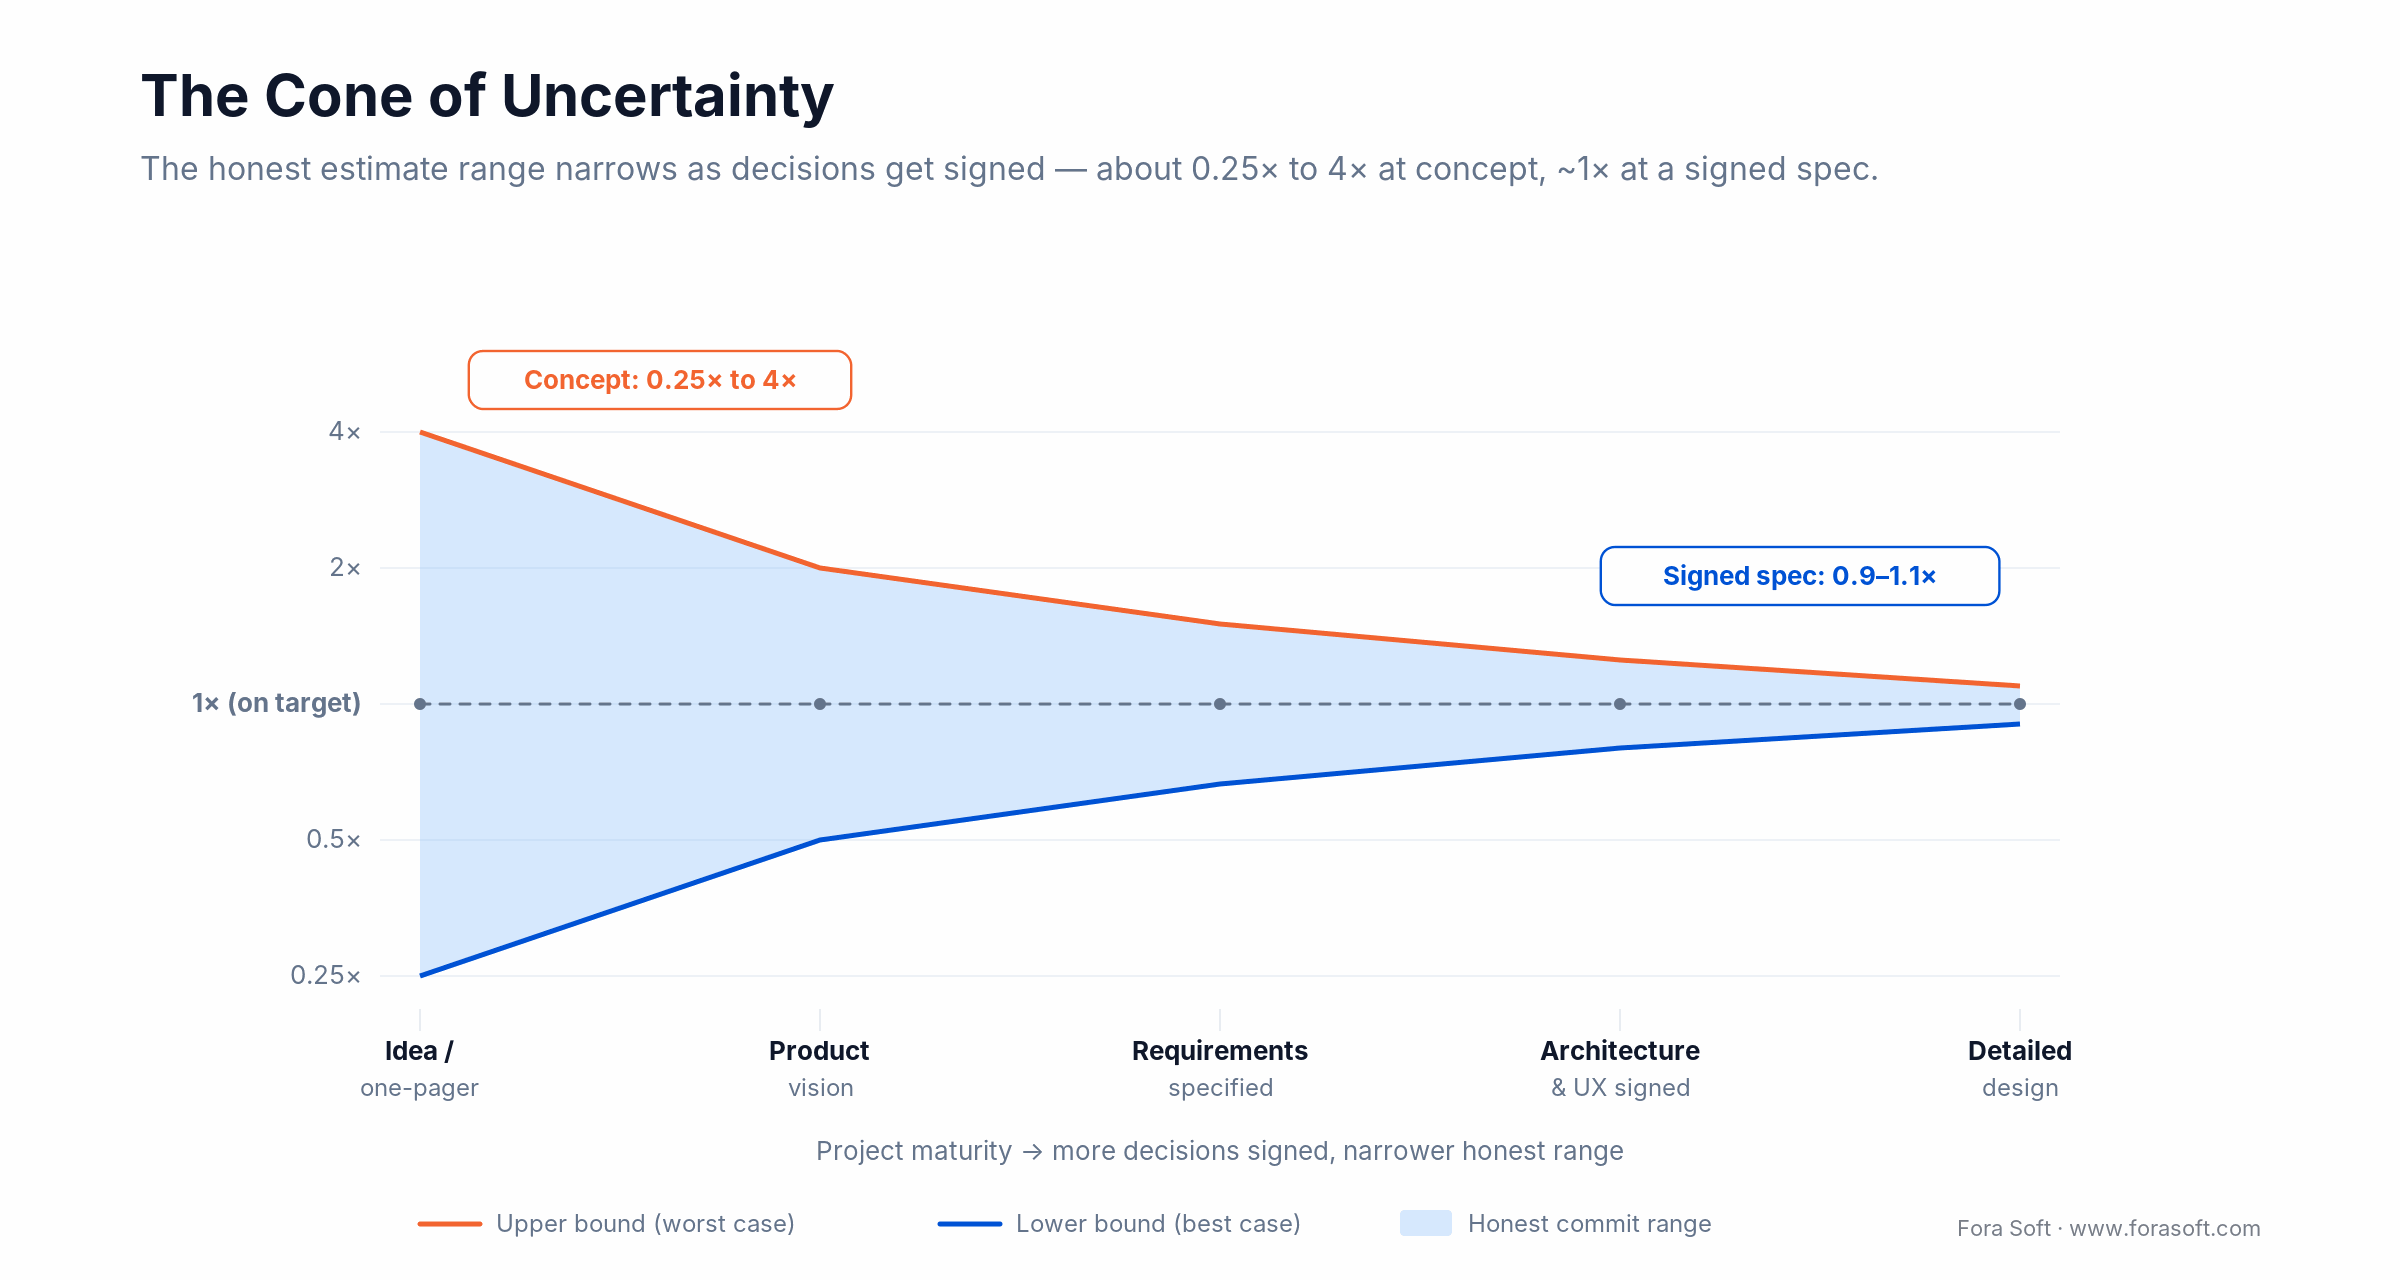
Figure 1. The Cone of Uncertainty — the honest range narrows from about 0.25×–4× at concept to 0.9–1.1× at detailed technical design.
Reach for the cone when: a vendor hands you a single hard number for a 6-month build after one call. Ask which stage of the cone they think they're at, and why.
Six estimation techniques, and when each one earns its keep
No single technique works for every project. Mature vendors stack two or three and triangulate. Here's the working set we use at Fora Soft.
1. Analogy-based (top-down)
You compare the new project to a finished one with similar scope, adjust for known differences, and anchor the rough order of magnitude. It's fast and surprisingly accurate if you have a deep portfolio. Our 250+ shipped projects mean we can usually find three or four close analogues for any brief — a multi-tenant video platform, a mobile IoT dashboard, a WebRTC SFU on AWS. It's weak when the project introduces genuinely new tech.
2. Bottom-up work breakdown
Decompose the system into features, features into stories, stories into tasks, and estimate each leaf. Sum up and add overhead for PM, QA, DevOps, review. This is the most accurate method at a late stage, and the most misleading one at an early stage, where you're multiplying confident-looking numbers by a tree you barely understand.
3. Three-point (PERT)
For every task, capture optimistic (O), most-likely (M), and pessimistic (P) estimates. The expected value is E = (O + 4M + P) / 6; the standard deviation is σ = (P − O) / 6. Summed across the project it gives you a confidence band instead of a single scalar, and that band is the right thing to put in a contract.
4. Story points & velocity
Relative sizing (Fibonacci 1/2/3/5/8/13) turns estimation into a team conversation rather than an individual guess. You measure velocity over 3–4 sprints and project the backlog out. Excellent for ongoing teams; useless for vendor selection, because a story point in one team has no exchange rate with a story point in another.
5. Parametric / COCOMO-II-style models
Effort is calculated from a size measure (source lines of code or function points in COCOMO II; use-case points or screen and API counts in lighter in-house models) and scaled by product, project and team factors. Strong for enterprise work with historical data; requires calibration, otherwise it's pseudo-precision.
6. AI-assisted triangulation (2026)
LLMs are now credible first-pass estimators for well-described features, especially when grounded in a vendor's own historical tickets. We use them to generate a bottom-up WBS candidate, then every node is reviewed by a human lead who can catch the hallucinations. Never present an AI-only estimate to a client — but never ignore the productivity gain either. On one 1M+ line video platform, AI-assisted workflows cut delivery time 30–40%; the full case study shows how. Keep the human review honest, though: in METR’s July 2025 randomised trial, experienced open-source developers took 19% longer with AI tools while believing they had been about 20% faster, so use delivery data measured on your own projects, not developers’ impressions, as the estimation input.
Other software estimation methods: Delphi, T-shirt sizing, Function Points, Monte Carlo
Beyond the six core techniques, four more methods show up in mature teams: Wideband Delphi for expert consensus, T-shirt sizing for fast roadmap triage, Function Point Analysis for a size measure that does not depend on the technology, and Monte Carlo forecasting for delivery dates driven by a team’s real throughput. The table shows when each is worth the effort.
| Method | How it works | Best for | Limitation |
|---|---|---|---|
| Wideband Delphi | 3–5 experts estimate anonymously, compare, discuss the outliers and re-estimate for 2–3 rounds (popularised by Barry Boehm, 1981) | Novel work with no close analogue | Slow; needs experienced estimators |
| T-shirt sizing | Items go into XS–XL buckets; each bucket maps to an effort band | Roadmap and backlog triage before a spec exists | Too coarse to contract against |
| Function Point Analysis | Counts inputs, outputs, inquiries and internal and external files, weighted by complexity (IFPUG method, ISO/IEC 20926) | Enterprise and public-sector work; comparing vendors on the same scope | Needs a trained counter; weak for real-time and AI-heavy features |
| Monte Carlo forecasting | Re-samples the team’s historical weekly throughput thousands of times to give a date at 50%, 85% and 95% probability | Running teams with 10+ weeks of delivery history | Useless without history; assumes the process stays stable |
| #NoEstimates (throughput counting) | Slices work into small, similar items and forecasts by counting them instead of sizing each one | Product teams with stable flow | Rarely accepted by buyers for a fixed-scope contract |
Reach for Monte Carlo when: a stakeholder asks “when will it be done?” about a team with 10+ weeks of throughput history. Answer with a date and a probability, not a single date.
Function Points and Monte Carlo answer different questions: the first measures how big the system is before work starts (the counting rules are maintained by IFPUG), the second how fast a running team gets through it. Pair either one with PERT or a bottom-up breakdown rather than replacing them.
Which technique for which stage — a decision matrix
| Technique | Best stage | Accuracy | Effort to produce | Watch out for |
|---|---|---|---|---|
| Analogy | Idea → vision | ±50% | Hours | Tech novelty, region/team shift |
| Bottom-up WBS | Spec → design | ±15% | Days to weeks | Missing leaves, double counting |
| Three-point / PERT | Any, with bottom-up | Band, not point | +20% on top of WBS | Anchoring optimism |
| Story points | Running team | Team-specific | Sprint overhead | Not portable across teams |
| Parametric | Enterprise, repeat work | ±20% if calibrated | Needs history | Garbage-in pseudo-precision |
| AI-assisted | First-pass WBS | Human-verified | Hours | Silent hallucinations |
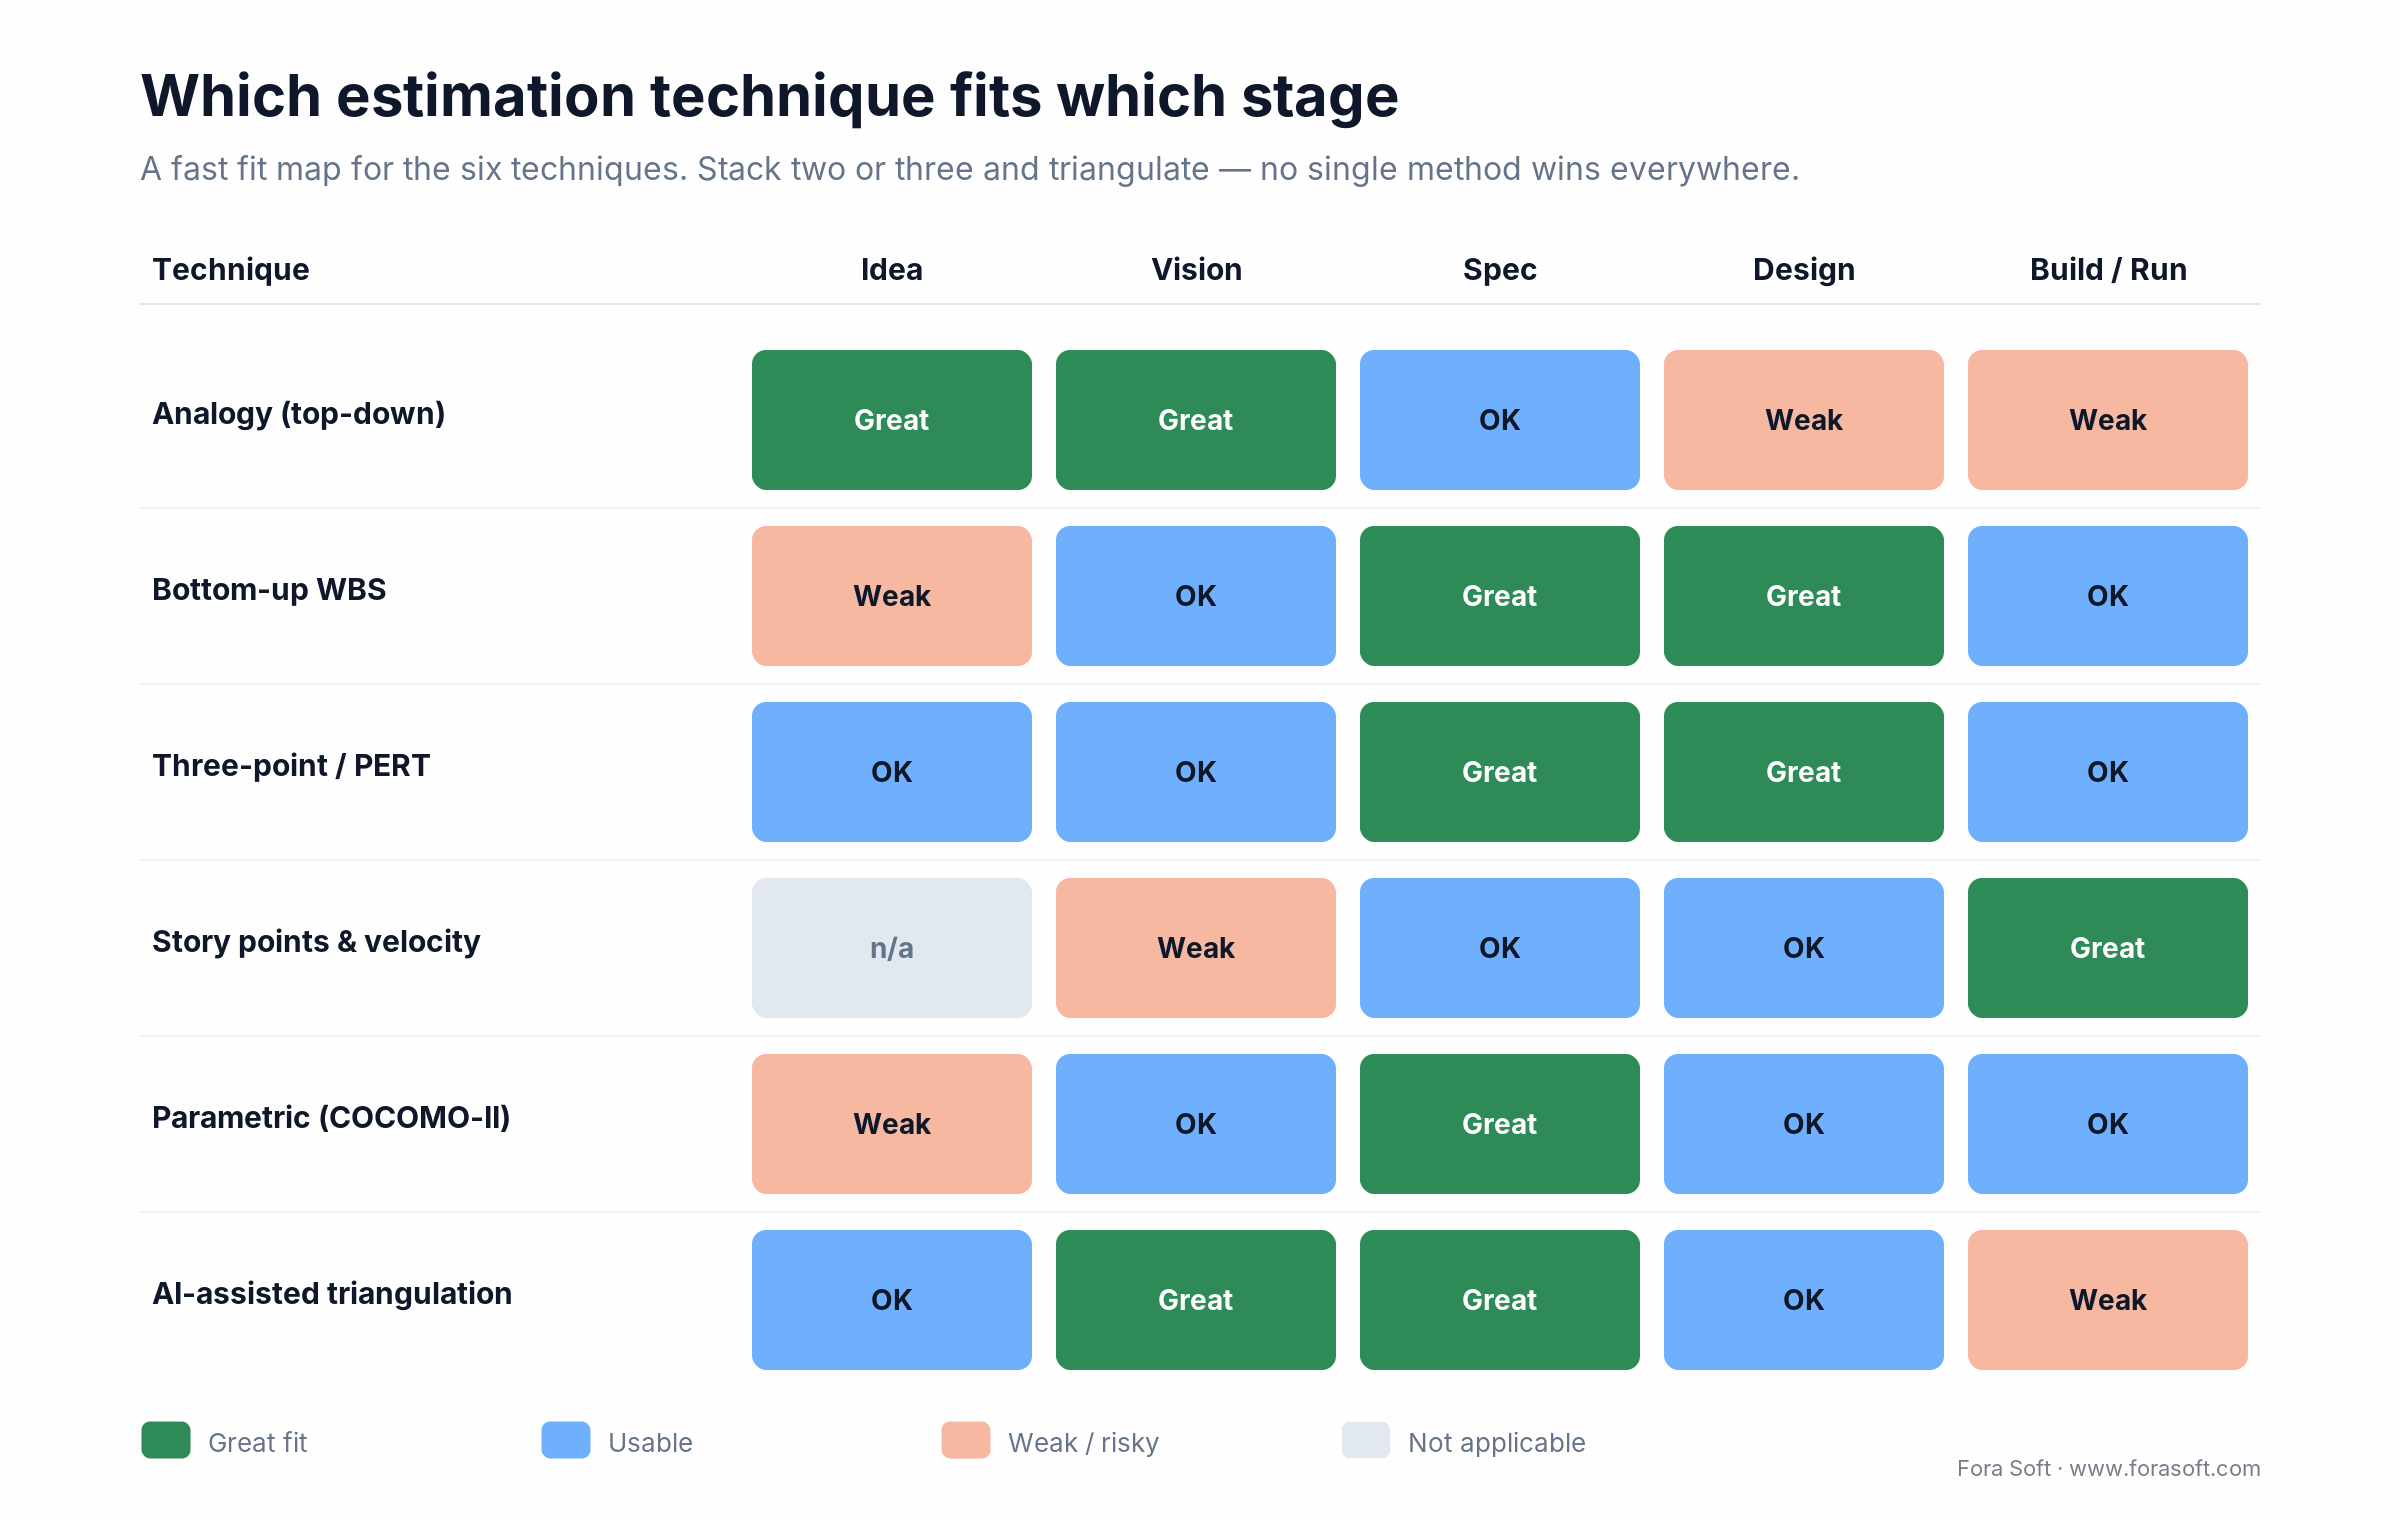
Figure 2. Which estimation technique fits which stage. Stack two or three and triangulate — no single method wins everywhere.
Want these techniques applied to your actual project?
Bring a one-pager to a 30-min intro call — fit, scope, budget; no charge. We’ll tell you which estimation methods fit your stage and what discovery would need to cover.
A four-stage estimation playbook (how Fora Soft actually does it)
This is the workflow we run for every new engagement. It compresses McConnell, PMI, and two decades of our own mistakes into something operational.
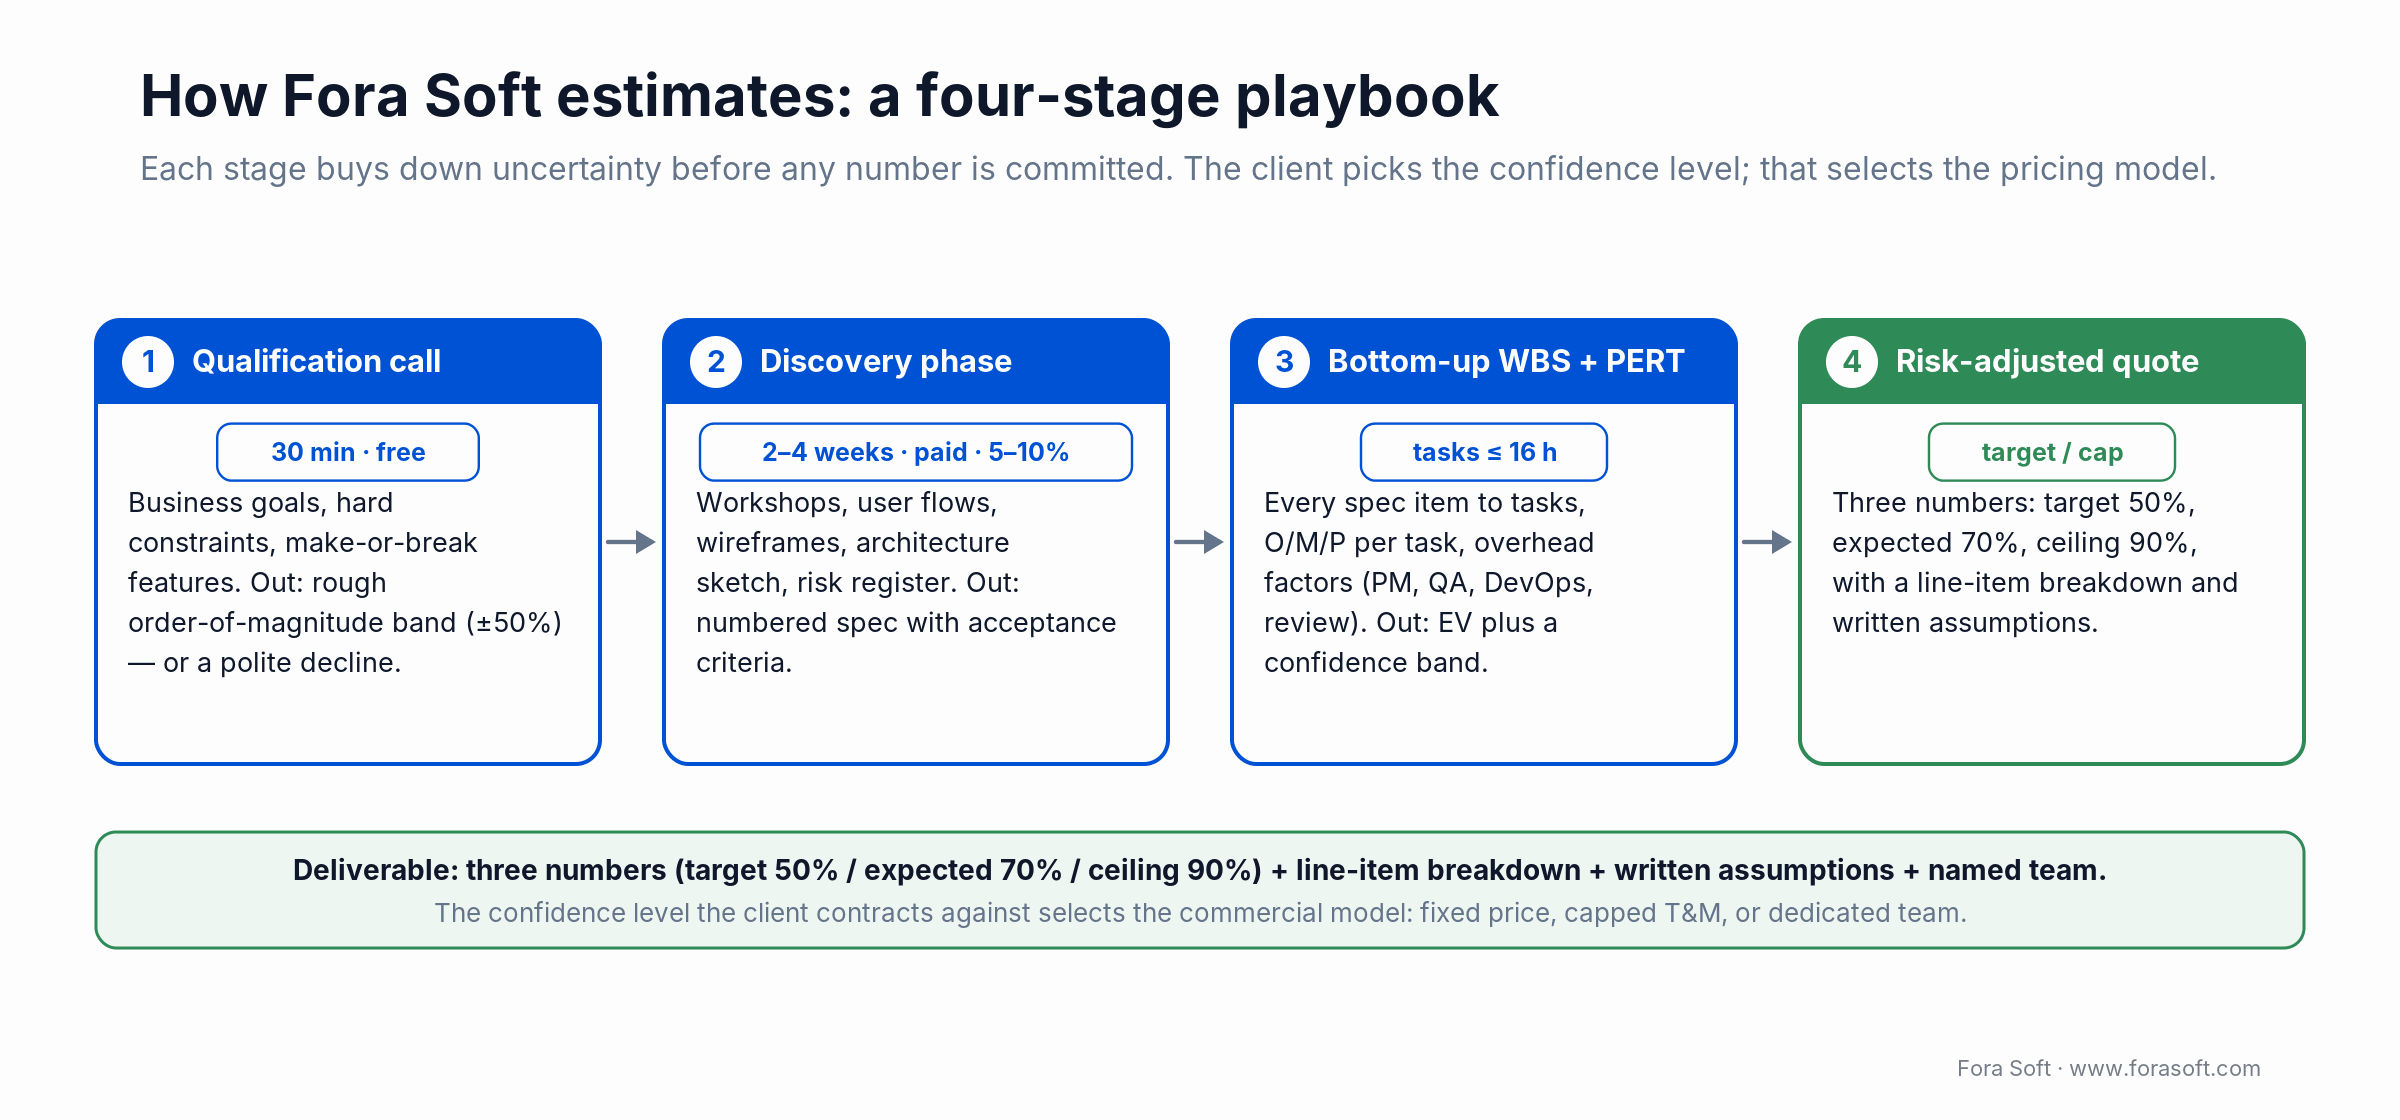
Figure 3. Fora Soft's four-stage estimation playbook, from a 30-minute qualification call to a risk-adjusted quote.
Stage 1 — Qualification call (30 minutes, no charge)
Goal: decide whether to engage at all. We capture business objectives, critical constraints (regulatory, timeline, budget envelope), and the three or four features that determine whether the project ships. At the end of the call we agree whether the project fits, which estimation path suits its stage and what discovery has to answer — or we politely decline.
Stage 2 — Discovery phase (2–4 weeks, paid, 5–10% of project)
Workshops with stakeholders, user-flow mapping, wireframes, tech architecture sketch, risk register. Deliverable is a written spec with numbered requirements, acceptance criteria, and a technical approach. This is the single most ROI-positive phase in any build. Standish Group’s CHAOS research has long ranked user involvement and clear requirements among the top factors in project success.
Stage 3 — Bottom-up WBS with PERT bands
Every spec item is decomposed to tasks ≤ 16 hours. Each task gets O/M/P. We multiply by overhead factors (PM 12%, QA 18%, DevOps 6%, review 10%, meetings 4%). The summed expected value plus about 1.3 standard deviations (the 90% mark) becomes our quote ceiling; the EV becomes our target.
Stage 4 — Risk-adjusted presentation
We present three numbers: target (50% confidence), planned budget (70% confidence), ceiling (90% confidence), plus a line-item breakdown and an explicit assumptions list. The client picks the confidence level they want to contract against — which in turn selects the pricing model. Transparent, auditable, contractable. Walk through our workbook on a call.
From estimate to contract: pricing model and line items
An estimate turns into a contract through two decisions. The first is the pricing model, and the rule is to match it to scope stability: fixed price for a signed, stable spec; capped time and materials for an MVP whose last 30% will move; a dedicated team for a roadmap of 12 months or more — our dedicated development team page shows how we structure that last case. The second is the line-item breakdown: a credible one names every cost centre (engineering, QA, design, project management, DevOps, discovery and contingency) instead of quoting one number.
Both decisions are about money rather than technique, so we cover them in depth elsewhere: contract models and who owns the risk, what a complete estimate must price, and typical 2026 cost ranges are in our software cost estimation playbook for buyers.
The 2026 line items nobody budgeted for in 2022
Modern builds ship with AI components, and modern estimates have to as well. The FinOps Foundation’s State of FinOps 2026 survey of 1,192 practitioners found that 98% of organisations now manage AI spend, up from 31% two years earlier: AI cost control went from niche to default because the bills arrived before the budget lines did. Name these items upfront.
- LLM inference tokens. Model + context size × queries/day × days/month. Budget for both the development and the production environments. Include a bound for traffic spikes.
- Embedding & vector DB. Pgvector on existing Postgres is cheap; managed vector services (Pinecone, Weaviate) add a recurring line-item.
- Observability. Trace storage for LLM chains (Langfuse, Phoenix) and standard APM both grow with usage. Budget 3–5% of infra on observability, not 0.
- Evaluation & guardrails. A small but non-zero budget for human-reviewed eval sets, red-teaming, prompt regression suites.
- Model drift & vendor churn. APIs deprecate, prices change, new models change behaviour. Book one engineer-week per quarter for re-calibration.
If you're building anything AI-assisted, our AI integration service uses a FinOps-first cost model so none of this is a surprise on your cloud bill.
KPIs we use to track estimate quality
Estimates should be audited against outcomes. The metrics below are what we track internally at Fora Soft and the ones a mature client should ask any vendor for.
- Estimate accuracy ratio (EAR). Actual hours ÷ estimated hours. Target 0.9–1.1 on mature stacks; 0.8–1.3 on R&D work. Anything below 0.7 means we padded; above 1.3 means we skipped discovery.
- Change-order ratio. Number of signed change requests ÷ number of planned features. Healthy is 10–20%. Over 50% and the original spec wasn't a spec.
- Discovery-to-total ratio. Discovery hours ÷ total project hours. Healthy is 5–12%. Under 3% is reckless; over 20% is often a pre-sales dump disguised as analysis.
- Confidence-level adherence. How often the actual spend falls inside the 90% band. Target: > 85% of projects.
- Post-launch defect density. Bugs per KLoC in the first 90 days of production. A great estimate hidden behind low quality is a bad estimate.
What the industry data says about estimation
If you’re making the case internally for a discovery-first approach, these are the numbers worth citing, from landmark studies and 2025–2026 research.
- McKinsey & University of Oxford (2012, 5,400+ IT projects). Large IT projects (initial budget above $15 million) run on average 45% over budget and 7% over time while delivering 56% less value than predicted.
- Standish Group CHAOS (2020 edition). About 31% of projects succeed on scope, time and budget, about 50% are challenged and about 19% fail outright.
- PMI Pulse of the Profession (2025). Project professionals with high business acumen report an 8% project failure rate against 11% for their peers, and 73% vs 68% budget adherence; only 18% of respondents rate high on business acumen.
- METR randomised trial (July 2025). Experienced open-source developers took 19% longer on real tasks when allowed AI tools, yet believed afterwards that AI had made them about 20% faster. METR’s February 2026 update says newer results may show a speed-up but calls that evidence weak.
- Google DORA, State of AI-assisted Software Development (September 2025, ~5,000 respondents). 90% of technology professionals now use AI at work and over 80% report higher productivity, while AI adoption is still linked to lower software delivery stability (DORA 2025 report).
- Stack Overflow Developer Survey (July 2025, 49,000+ respondents). 84% use or plan to use AI tools, 46% distrust the accuracy of their output and 45% say debugging AI-generated code is time-consuming (survey results).
- FinOps Foundation, State of FinOps (2026). 98% of organisations manage AI spend in their FinOps practice, up from 31% in 2024.
Read together, the AI data says one thing to an estimator: budget AI as review, verification and inference cost, not as a flat discount on build hours.
A simple estimate template you can hand any vendor
Copy the structure below into your RFP or reply-to-vendor email. Any competent agency can fill it in; any agency that can't is telling you something. For a first rough number before you send it, our app development cost calculator prices features, platforms and integrations in a few minutes.
Three-point estimation, worked example
Take a single feature: "Real-time transcription in a WebRTC meeting, with speaker labels." We decompose it into tasks, capture O/M/P in hours, compute expected value and variance. (Curious how that feature is actually built? See our real-time speech translation guide.)
| Task | O | M | P | E = (O+4M+P)/6 |
|---|---|---|---|---|
| Audio capture pipeline | 6 | 10 | 20 | 11.0 |
| ASR provider integration | 8 | 14 | 28 | 15.3 |
| Speaker diarization | 10 | 20 | 40 | 21.7 |
| Client UI & captions | 6 | 12 | 18 | 12.0 |
| Storage & retrieval of transcripts | 4 | 8 | 14 | 8.3 |
| Testing (functional + load) | 8 | 16 | 24 | 16.0 |
| Sum | 42 | 80 | 144 | 84.3 |
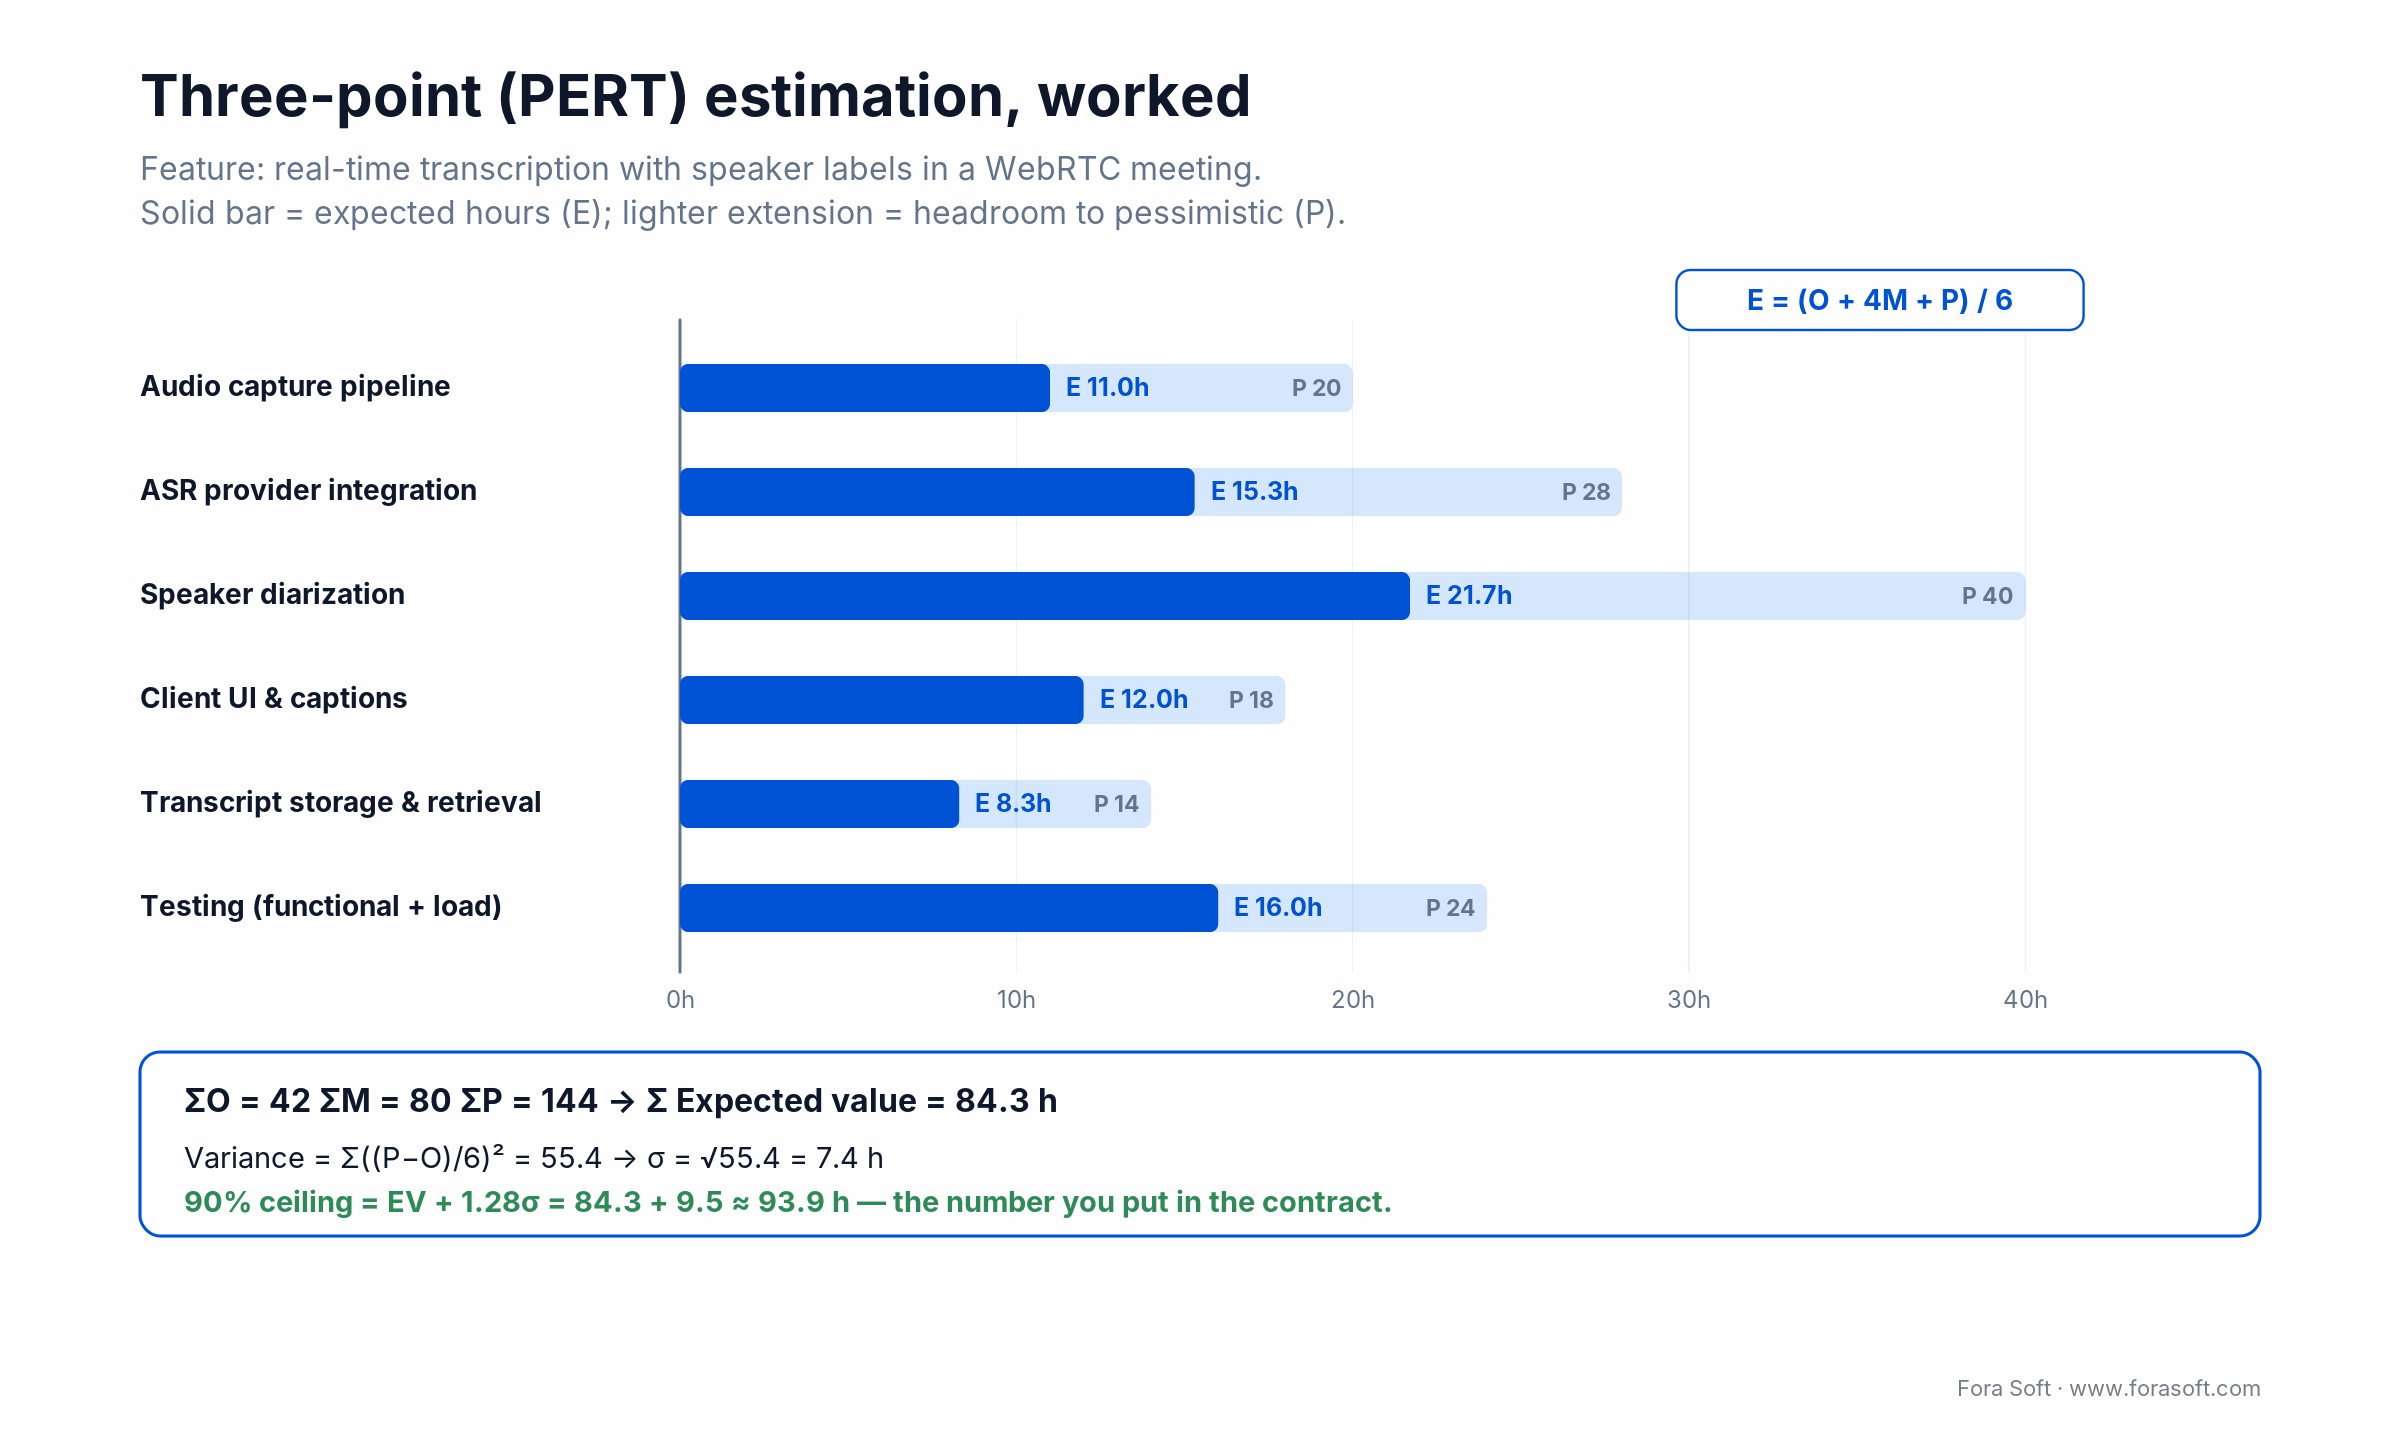
Figure 4. Three-point (PERT) worked example. Expected value 84.3 h, σ 7.4 h, 90% ceiling ≈ 93.9 h.
The summed EV is 84.3 hours. Summed variance is Σ ((P−O)/6)² ≈ 55.4, so σ ≈ 7.4 hours. The 90% upper bound is EV + 1.28σ ≈ 93.9 hours, which becomes the contract ceiling. Add overhead (PM, review, QA) and you have a defendable per-feature number you can show any CFO.
One caveat: summing variances assumes the tasks are independent. Real risks are correlated — one bad integration delays several tasks at once — so on a breakdown with hundreds of tasks the summed σ comes out too narrow. Widen it, or add a project-level contingency, rather than trust the tight band.
Worked example: tracking a 14-month EdTech build against its estimate band
Illustrative project (model numbers, not a client record)
Multi-tenant EdTech platform with live video classes, SCORM course delivery, analytics and Stripe billing. Budget envelope: US$700k. Timeline: 14 months to launch. Team: 7 FTE plus fractional PM and design.
A 3-week paid discovery produces a spec with 186 numbered requirements. The bottom-up WBS breaks them into 412 tasks; three-point bands give an expected value of US$598k and a 90% ceiling of US$684k. The EV becomes the target and the ceiling the cap, priced as capped time and materials with a monthly burn review. That band is tighter than the cone allows straight after requirements, so the cap is re-checked once architecture and UX are signed off.
Suppose the final spend lands at US$633k — about 5.8% above the target and well under the 90% cap, with two requirements dropped and four added on the client’s call. The monthly scorecard makes each trade-off visible when it happens, instead of in a change-order argument at month 11.
The point isn’t the number — it’s that the client always knows where the project stands against the band. If you’d like to see the workbook structure behind this model, book a 30-min call and we’ll walk through it live.
Seven red flags in a vendor estimate
Use this as a checklist when you receive a proposal. Two or more of these and the number is probably fiction.
- One scalar, no range. No confidence band = no estimate. Ask for EV + 90% ceiling.
- No discovery phase. Anyone skipping discovery is either absorbing the risk (and pricing it in invisibly) or handing you a landmine.
- Zero line for QA or PM. It's happening; if it's not in the estimate, the vendor is funding it with margin — and it'll show up later.
- No written assumptions. "Within reason" doesn't hold up when scope shifts.
- No change-request process. Scope will change; the mechanism for re-pricing it must be contractual.
- Round-number pricing. "$150k" is a sales price, not an estimate. Real bottom-up sums are rarely that clean.
- No named team. If the proposal doesn't say who's building, the estimate assumes average performance that may never materialise.
Those seven are the tells inside a single proposal. For the full buyer-side process, from first quote to signature, see our buyer’s playbook for software cost estimation: the Cone of Uncertainty read as a range you can hold a vendor to, the three estimate types, and a five-question accept-or-push-back check.
When Fora Soft refuses to estimate
We will not produce a fixed-price estimate when:
- Business goals aren't written down.
- There's no named decision-maker on the client side.
- Core requirements change more than twice during the qualification call.
- The client insists on fixed price despite active R&D work (e.g., novel ML, hardware integration).
- The timeline is below the physical minimum even on our best-case analogy.
Saying no to an estimate we can’t stand behind is part of how we’ve stayed Top Rated Plus on Upwork across 900+ jobs. A vendor who'll estimate anything is a vendor who'll under-deliver anything.
Got a vendor estimate you don't fully trust?
Bring the breakdown to a 30-min intro call — fit, scope, budget; no charge. We’ll walk it through the red-flag checklist above and tell you which assumptions to challenge.
Frequently asked questions about software estimation
How long does a proper discovery phase take?
Two to four weeks for most mid-complexity builds, longer for regulated industries or hardware-touching systems. Cost is typically 5–10% of the projected total. Deliverable is a written spec with numbered requirements and acceptance criteria you could hand to any vendor.
What are the components of software estimation?
Five: size (how much software), effort (person-hours), schedule (calendar time), cost (effort times rates plus non-labour items) and confidence (the range and its probability). A credible estimate states all five; most weak quotes skip size and confidence. Pricing that estimate is a separate step, covered in the cost estimation playbook linked at the top of this guide.
What is Monte Carlo estimation in software projects?
Monte Carlo forecasting re-samples a team’s historical weekly throughput thousands of times and reports the delivery date at several probabilities, for example 50%, 85% and 95%. It needs roughly 10+ weeks of delivery history, so it suits running teams rather than new projects.
Fixed price or time & materials — which is safer?
Neither by itself. Safety comes from matching model to scope stability. Fixed price is safer when spec is signed, shorter than 6 months, and unlikely to move. T&M is safer on anything exploratory. Capped T&M is the sensible middle ground for most MVP builds.
Do AI coding tools make estimates more accurate?
Not by themselves. AI tools can speed up writing code but leave integration, review and testing largely unchanged, and the evidence on net speed is mixed: METR’s July 2025 trial measured experienced developers 19% slower with AI tools. The reliable shift is where the effort goes — less typing, more reviewing — so estimate review time explicitly.
What's a reasonable risk buffer?
Between 10% (mature tech, frozen scope) and 25% (R&D, external dependencies, regulatory). If the buffer isn't stated explicitly, assume the vendor hid 15–30% inside unit prices.
Should you share your budget with a vendor?
Yes. The fear is that the vendor will quote exactly your budget; the reality is that without an envelope they'll either overshoot and lose, or aim so low they can't deliver. Share the envelope and ask what's feasible inside it.
What makes Fora Soft's estimates different?
Three things. First, every estimate is a band, not a scalar, with explicit confidence levels. Second, we publish the WBS and assumptions so a client can audit any number. Third, 250+ completed projects since 2005 means our analogy library is deep — we've almost certainly built something adjacent to your idea.
What is the Cone of Uncertainty in software estimation?
It's the empirical rule that an honest estimate range is widest at the concept stage — about 0.25× to 4× the real cost — and narrows to roughly 0.9–1.1× once a detailed spec is signed. Barry Boehm described it in 1981; Steve McConnell popularised the numbers. Practically: judge an estimate by which stage it was made at.
What is three-point (PERT) estimation?
For each task you capture an optimistic (O), most-likely (M), and pessimistic (P) figure, then compute the expected value as E = (O + 4M + P) / 6 and the standard deviation as σ = (P − O) / 6. Summed across a project, it hands you a confidence band instead of a single number — which is what belongs in a contract.
Which software estimation technique is most accurate?
None in isolation. Analogy is fastest and best at the idea stage; bottom-up WBS is most accurate once a spec exists; three-point/PERT converts either into a defendable band. Mature teams stack two or three and triangulate rather than trusting one method.
How do AI features change a software estimate in 2026?
AI-assisted coding shifts effort from typing to reviewing, so the build band narrows slightly while integration and verification widen. And any product that calls an LLM at runtime needs its own budget lines: inference tokens, vector storage, observability, evaluation, and model drift. Leave those out and the cloud bill surprises you later.
Which estimation techniques suit Agile and which suit Waterfall projects?
Agile teams estimate with story points, Planning Poker, T-shirt sizing, velocity and Monte Carlo forecasts on throughput, because scope is refined sprint by sprint. Fixed-scope or Waterfall projects rely on analogy, bottom-up WBS, three-point PERT, Function Points and COCOMO II, because the whole scope has to be priced before work starts.
Who should estimate a software project?
The people who will build it, reviewed by a second senior lead. A salesperson’s number or a manager’s target is a budget, not an estimate; the engineers’ bottom-up figures, cross-checked against an analogy from past projects, are.
When should a software project be estimated?
At every stage gate, not once: a rough range at the idea stage, a firmer band after discovery, and a contractable number after architecture and UX are signed off. Each re-estimate should be narrower than the last, as the Cone of Uncertainty predicts.
What should a software estimate include?
A range (expected value plus a 90% ceiling), a line-item breakdown by cost centre, written assumptions, a change-request process, a named team, and the pricing model. A single scalar with no breakdown is a bid, not an estimate.
Tools we use (and tools you can audit us with)
- Jira / Linear for WBS, story points, velocity.
- Harvest / Toggl for time-entry reconciliation against estimates.
- Excel / Google Sheets for three-point worksheets — deliberately boring, reviewable by anyone.
- Miro for user-flow mapping and risk register workshops.
- Figma for clickable prototypes inside discovery.
- Langfuse / Helicone for LLM cost forecasting on AI components.
The short summary — software estimation, 2026
Every credible software estimate is a range, not a number. The range narrows as scope clarifies — that's the Cone of Uncertainty, and ignoring it is the root cause of most budget overruns. Pick a pricing model that matches your scope stability: fixed price for signed specs, capped T&M for MVPs, pure T&M for long-running platforms. Demand a line-item breakdown, written assumptions, a change-request process, and a named team. And in 2026, don't forget to budget for AI inference, vector stores, observability, and model drift — the line items that weren't on any template five years ago.
If you'd like Fora Soft to estimate your build — or to sanity-check an estimate you've already received — we do this for clients in EdTech, MedTech, video streaming, AI and enterprise SaaS — 250+ projects since 2005.
The handbook · 7 volumes
Fora Soft Video Engineering Handbook
A credible estimate for a video product depends on knowing which parts of the stack carry the risk. We wrote a seven-volume handbook on encoding, delivery, sound and AI; before estimating a streaming or calling build, read Volume 3 on WebRTC, CDNs and delivery economics, then Volume 1 on transcoding and Volume 7 on AI cost per stream-hour. Written by Nikolay Sapunov, CEO at Fora Soft.
Browse the handbook on Amazon →7 volumes · 9,000+ pages · Kindle & paperback
Ready for a credible estimate?
Bring a one-pager to a 30-min intro call — fit, scope, budget; no charge. Leave knowing which estimation path fits your stage and what discovery should cover.
Read next
AI & Process
AI in the software development process
How AI-assisted coding shifts estimation, velocity, and reviewer workload.
Service
Product planning & analytics
Our discovery service: scope, spec and estimate before the build commits to a number.
Service
Dedicated development teams
How to structure T&M engagements for 12+ month roadmaps.
Architecture
AI in software architecture design
Validating scalability before you commit to a number.

